Artificial Intelligence
Category: Technical How-to
Scala development in Amazon SageMaker Studio with Almond kernel
This post provides a comprehensive guide on integrating the Almond kernel into SageMaker Studio, offering a solution for Scala development within the platform.
Build a device management agent with Amazon Bedrock AgentCore
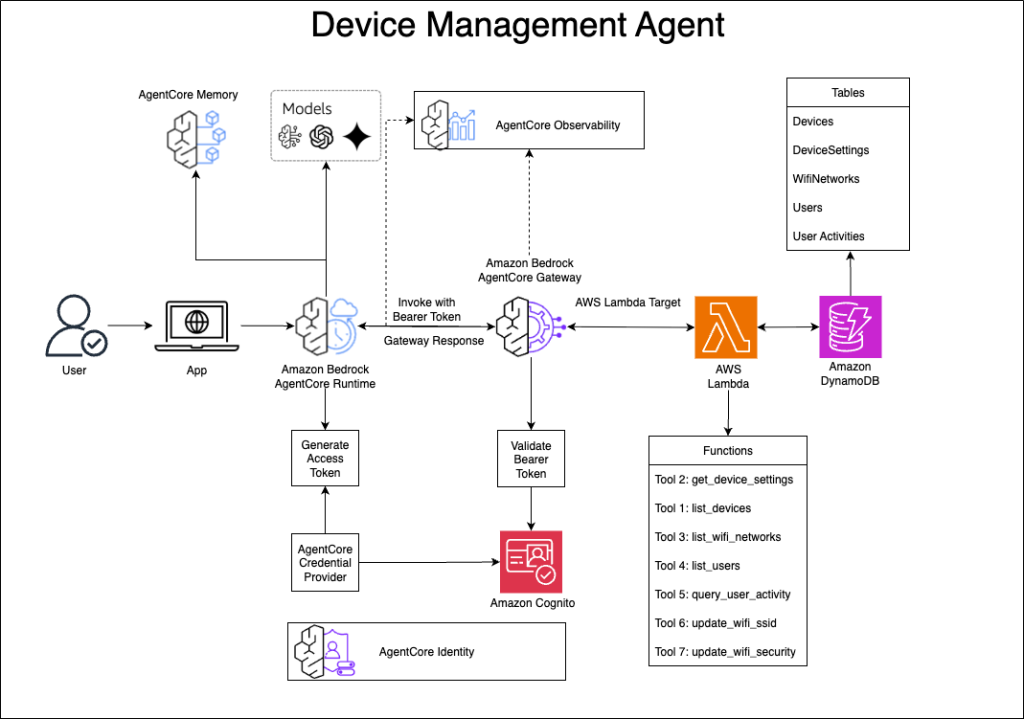
In this post, we explore how to build a conversational device management system using Amazon Bedrock AgentCore. With this solution, users can manage their IoT devices through natural language, using a UI for tasks like checking device status, configuring WiFi networks, and monitoring user activity.

Medical reports analysis dashboard using Amazon Bedrock, LangChain, and Streamlit
In this post, we demonstrate the development of a conceptual Medical Reports Analysis Dashboard that combines Amazon Bedrock AI capabilities, LangChain’s document processing, and Streamlit’s interactive visualization features. The solution transforms complex medical data into accessible insights through a context-aware chat system powered by large language models available through Amazon Bedrock and dynamic visualizations of health parameters.

Connect Amazon Quick Suite to enterprise apps and agents with MCP
In this post, we explore how Amazon Quick Suite’s Model Context Protocol (MCP) client enables secure, standardized connections to enterprise applications and AI agents, eliminating the need for complex custom integrations. You’ll discover how to set up MCP Actions integrations with popular enterprise tools like Atlassian Jira and Confluence, AWS Knowledge MCP Server, and Amazon Bedrock AgentCore Gateway to create a collaborative environment where people and AI agents can seamlessly work together across your organization’s data and applications.
Use Amazon SageMaker HyperPod and Anyscale for next-generation distributed computing
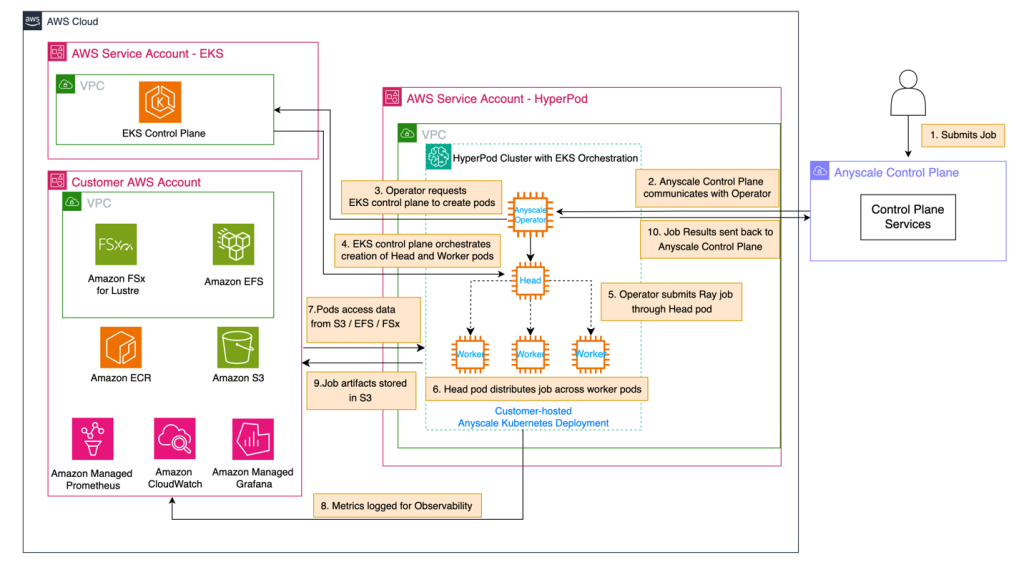
In this post, we demonstrate how to integrate Amazon SageMaker HyperPod with Anyscale platform to address critical infrastructure challenges in building and deploying large-scale AI models. The combined solution provides robust infrastructure for distributed AI workloads with high-performance hardware, continuous monitoring, and seamless integration with Ray, the leading AI compute engine, enabling organizations to reduce time-to-market and lower total cost of ownership.
Customizing text content moderation with Amazon Nova
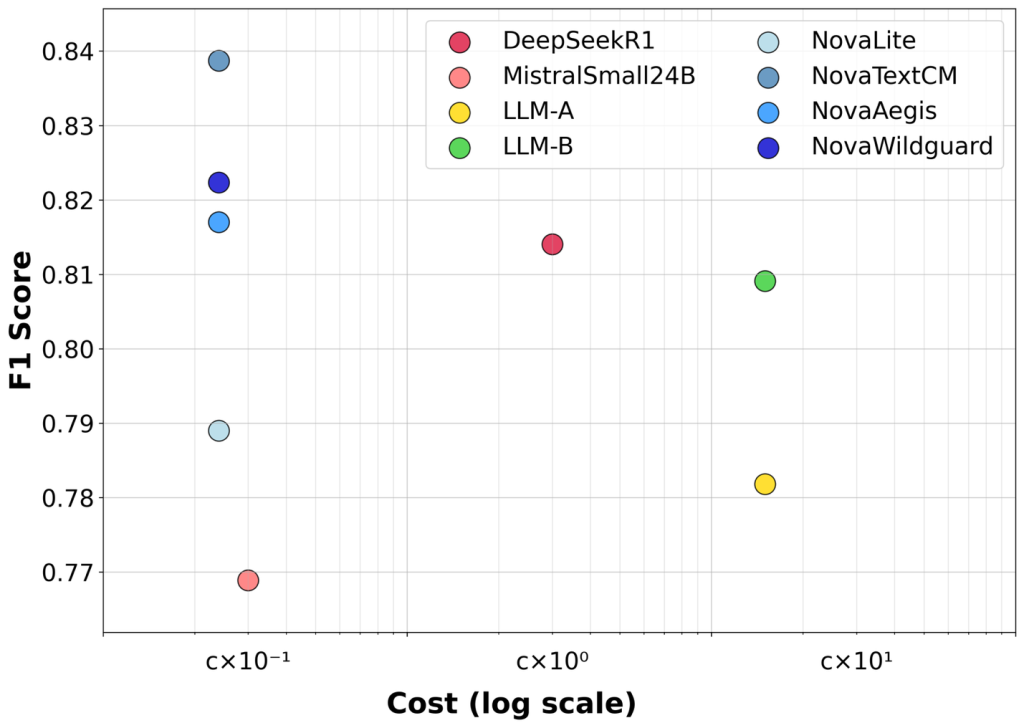
In this post, we introduce Amazon Nova customization for text content moderation through Amazon SageMaker AI, enabling organizations to fine-tune models for their specific moderation needs. The evaluation across three benchmarks shows that customized Nova models achieve an average improvement of 7.3% in F1 scores compared to the baseline Nova Lite, with individual improvements ranging from 4.2% to 9.2% across different content moderation tasks.
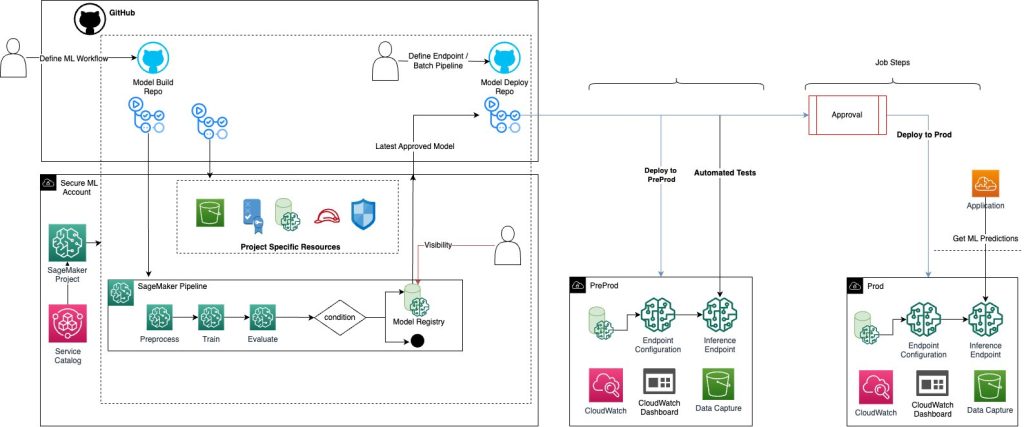
Implement a secure MLOps platform based on Terraform and GitHub
Machine learning operations (MLOps) is the combination of people, processes, and technology to productionize ML use cases efficiently. To achieve this, enterprise customers must develop MLOps platforms to support reproducibility, robustness, and end-to-end observability of the ML use case’s lifecycle. Those platforms are based on a multi-account setup by adopting strict security constraints, development best […]
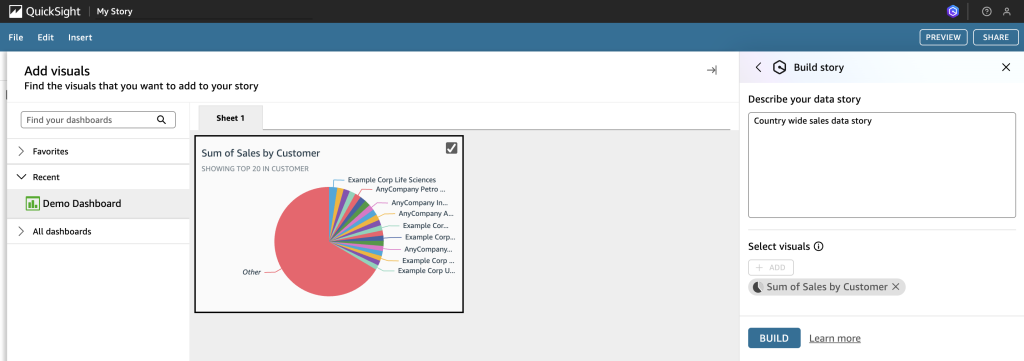
Automate Amazon QuickSight data stories creation with agentic AI using Amazon Nova Act
In this post, we demonstrate how Amazon Nova Act automates QuickSight data story creation, saving time so you can focus on making critical, data-driven business decisions.
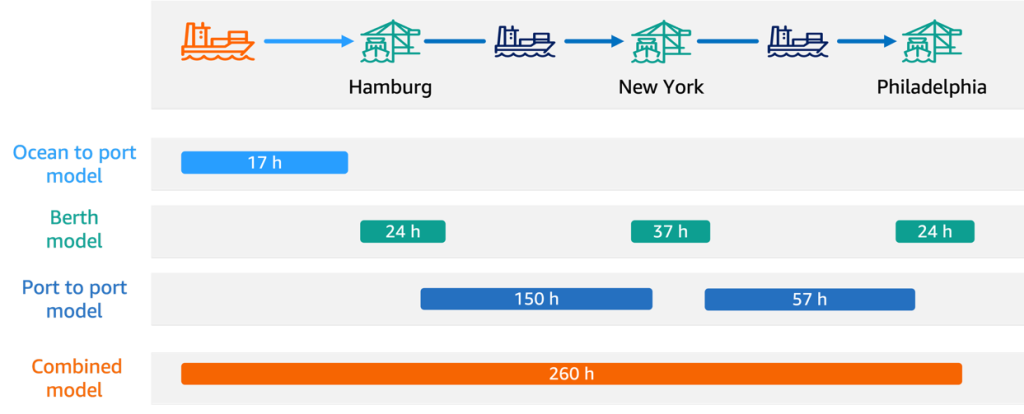
How Hapag-Lloyd improved schedule reliability with ML-powered vessel schedule predictions using Amazon SageMaker
In this post, we share how Hapag-Lloyd developed and implemented a machine learning (ML)-powered assistant predicting vessel arrival and departure times that revolutionizes their schedule planning. By using Amazon SageMaker AI and implementing robust MLOps practices, Hapag-Lloyd has enhanced its schedule reliability—a key performance indicator in the industry and quality promise to their customers.
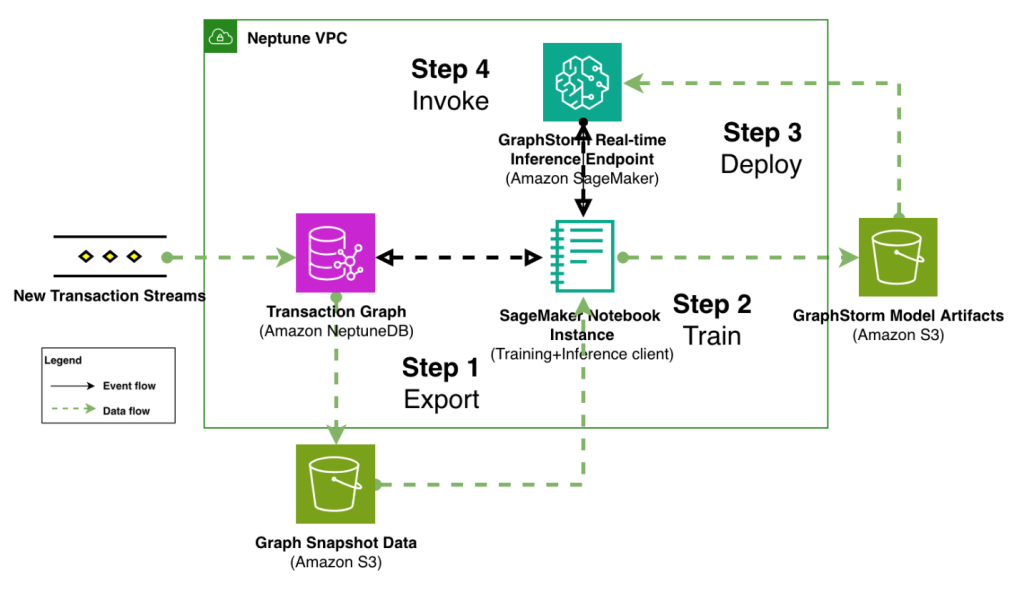
Modernize fraud prevention: GraphStorm v0.5 for real-time inference
In this post, we demonstrate how to implement real-time fraud prevention using GraphStorm v0.5’s new capabilities for deploying graph neural network (GNN) models through Amazon SageMaker. We show how to transition from model training to production-ready inference endpoints with minimal operational overhead, enabling sub-second fraud detection on transaction graphs with billions of nodes and edges.