Dedicated inference on Amazon SageMaker AI
Deploy open source models to production in hours, on dedicated infrastructure you control. You own the model weights, serving runtime and accelerator stack, and AWS manages the rest.
Trusted by enterprise ML teams and AI-native startups deploying models at scale
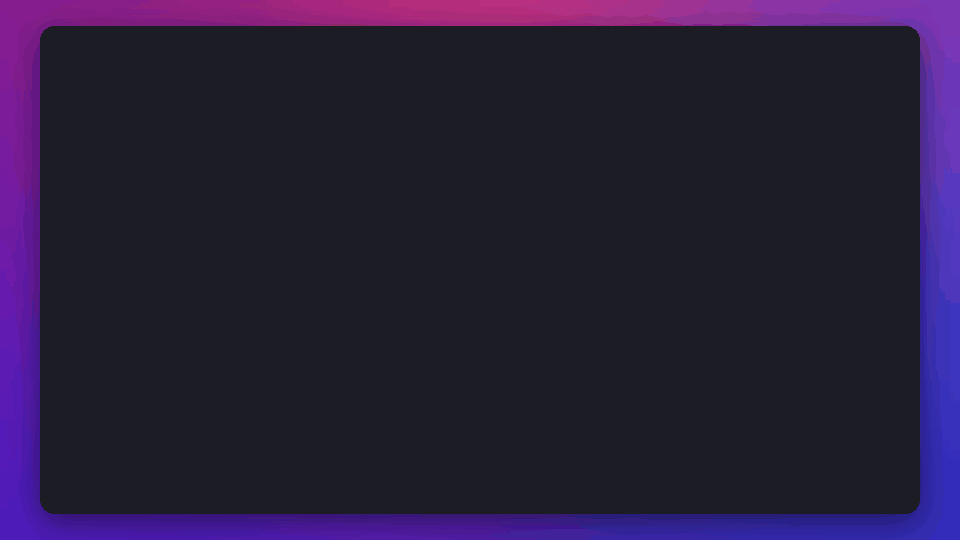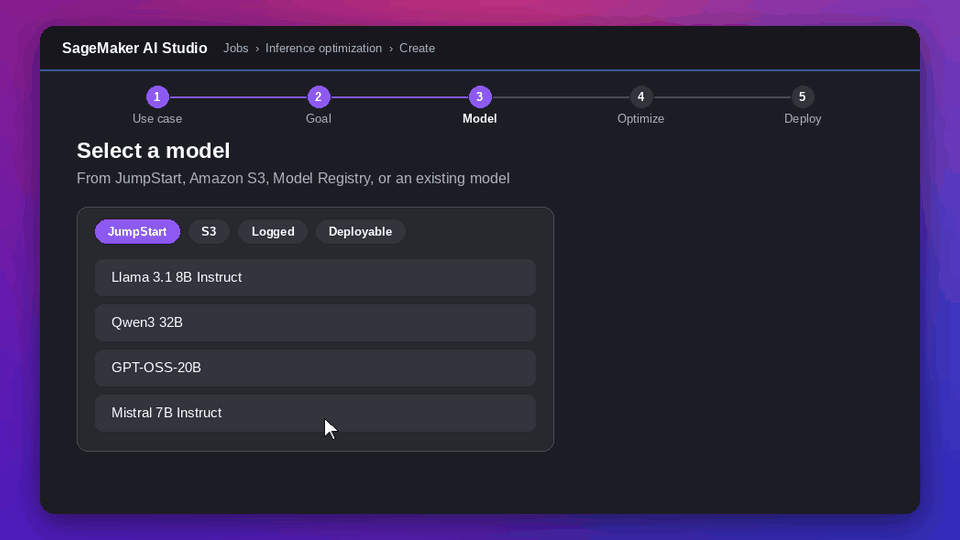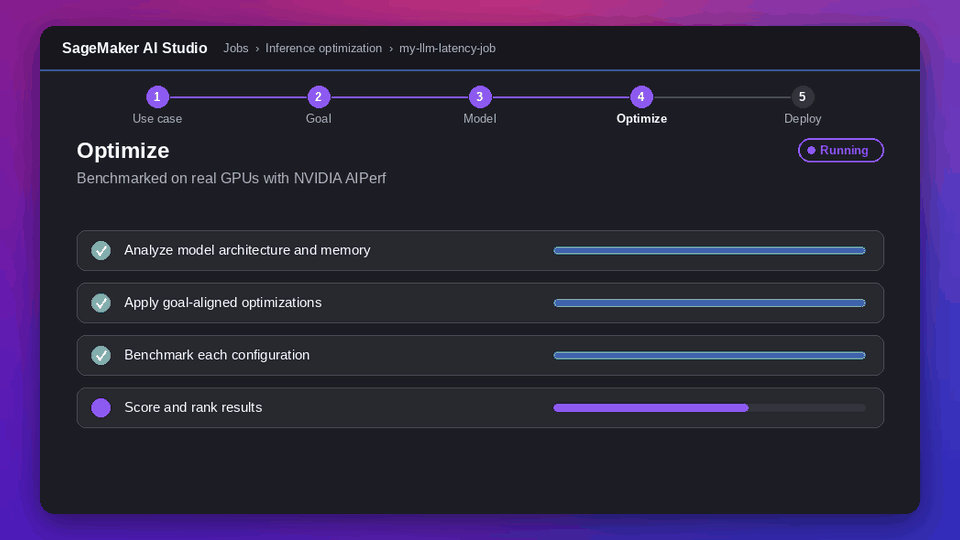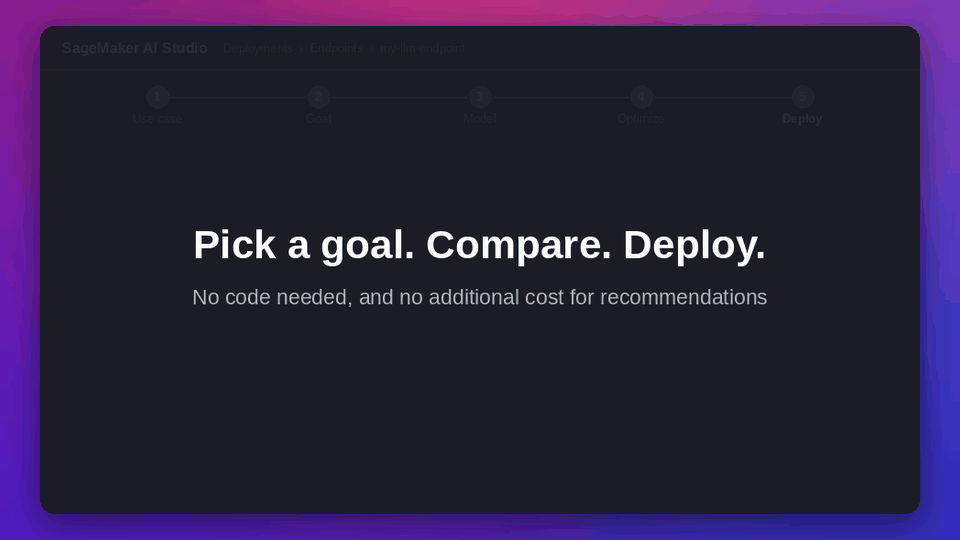
Pick any model. Deploy with one click.
Start serving a popular AI/ML model on a dedicated endpoint in minutes.
SageMaker AI helps you deploy models at production scale
Faster to production
Go live in hours, not weeks, with no manual benchmarking. One path from training to live inference. No separate tools to stitch together.
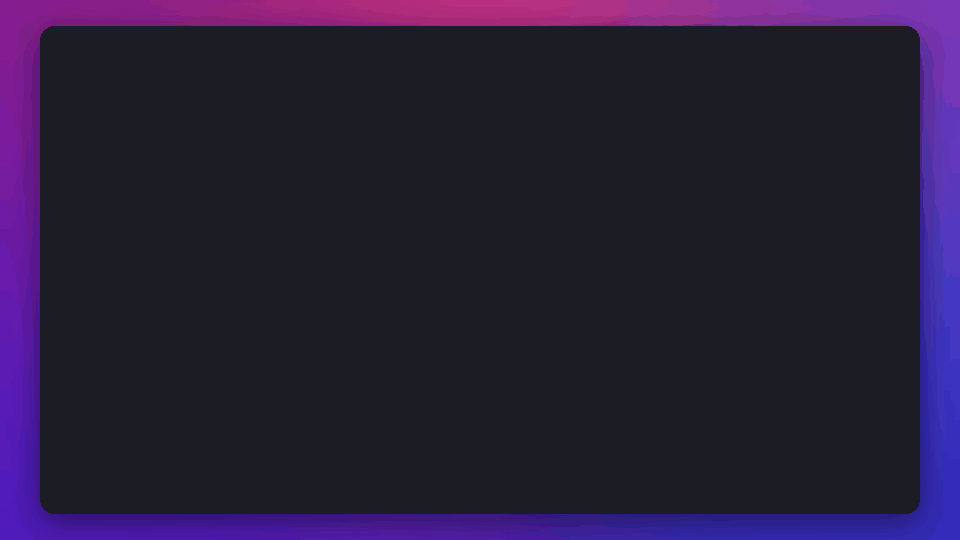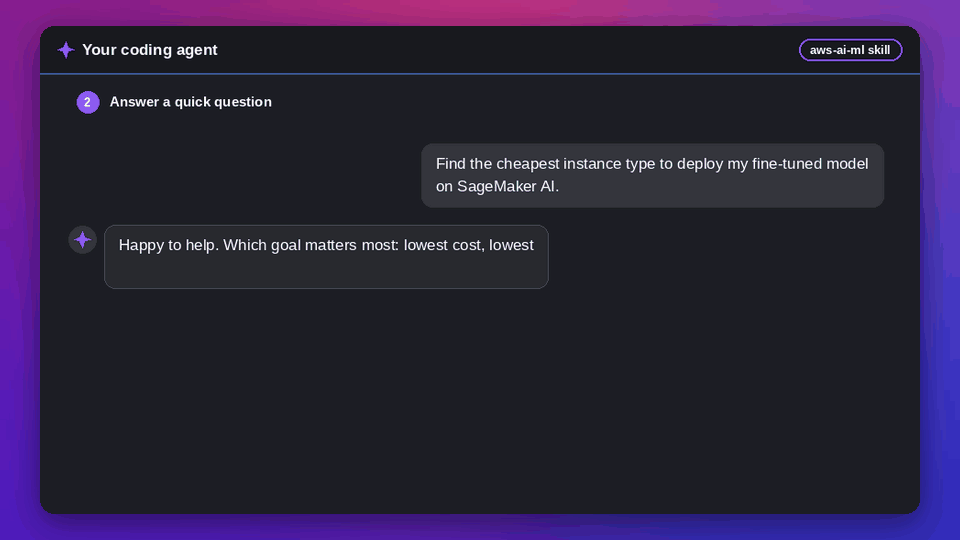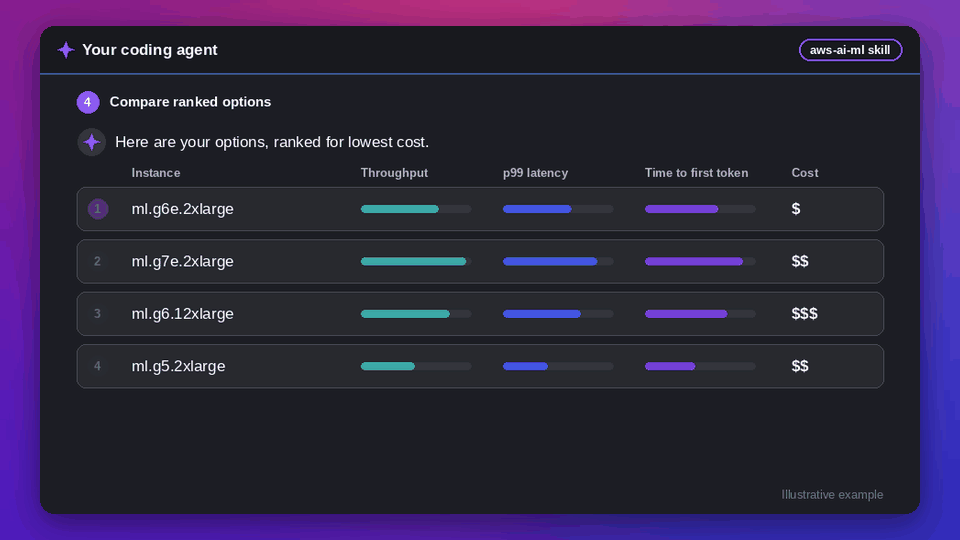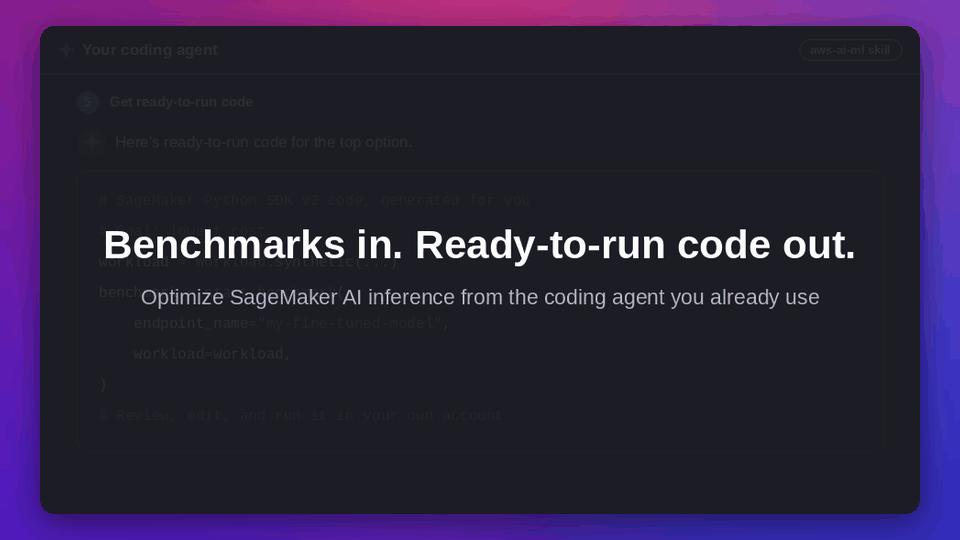
- Achieve your cost, latency, or throughput goal without manual testing, as automated optimization benchmarks your model and picks from 250+ supported instance types
- Optimize from your coding agent, as Kiro, Claude Code, or Codex benchmark endpoints and write ready-to-run SageMaker code
- Start serving popular models in minutes with one-click deployment of 1,000+ pre-optimized models in JumpStart
- Move models from HyperPod training to live endpoints without re-containerizing them
- Bring apps built on the OpenAI SDK, LangChain, or Strands Agents to your own GPUs with a one-line URL change
Lower TCO, better price-performance
Run more models on fewer GPUs and pay less for capacity.
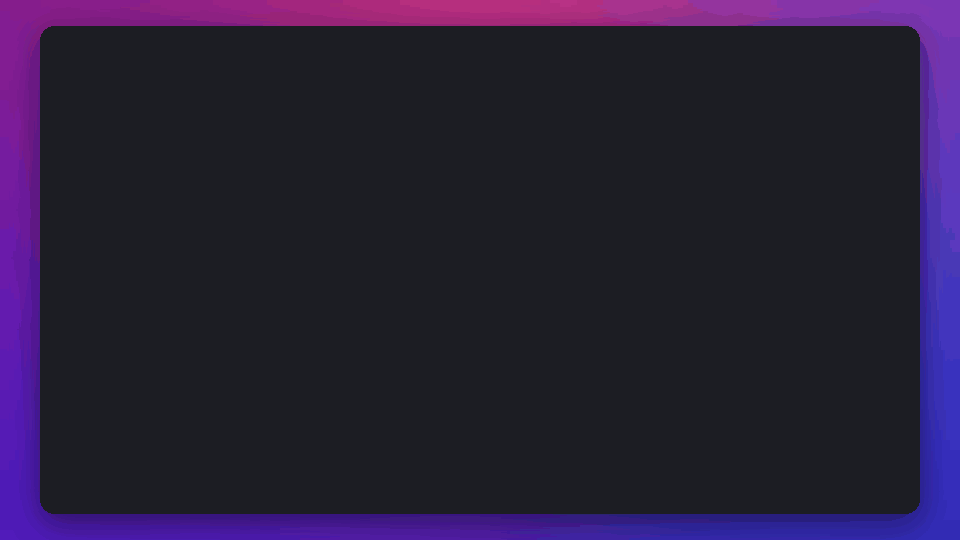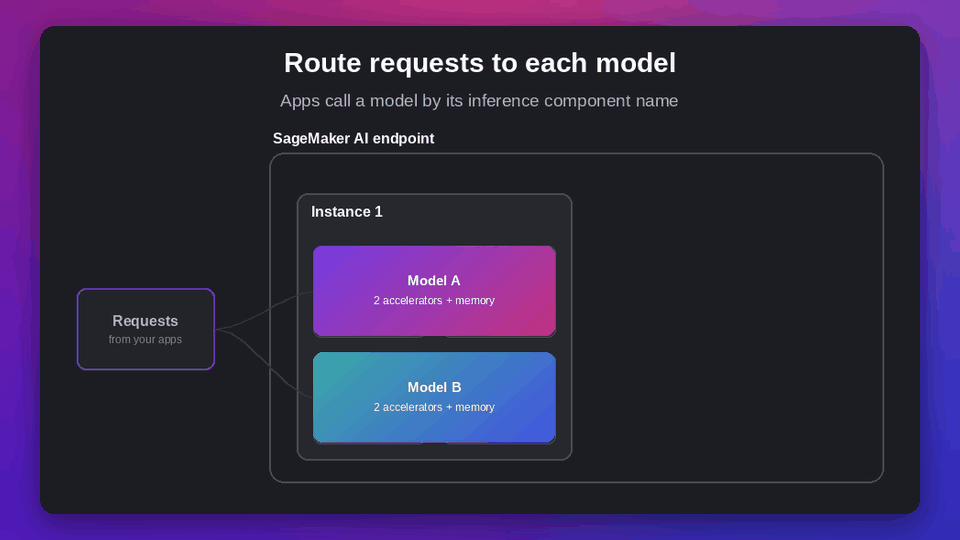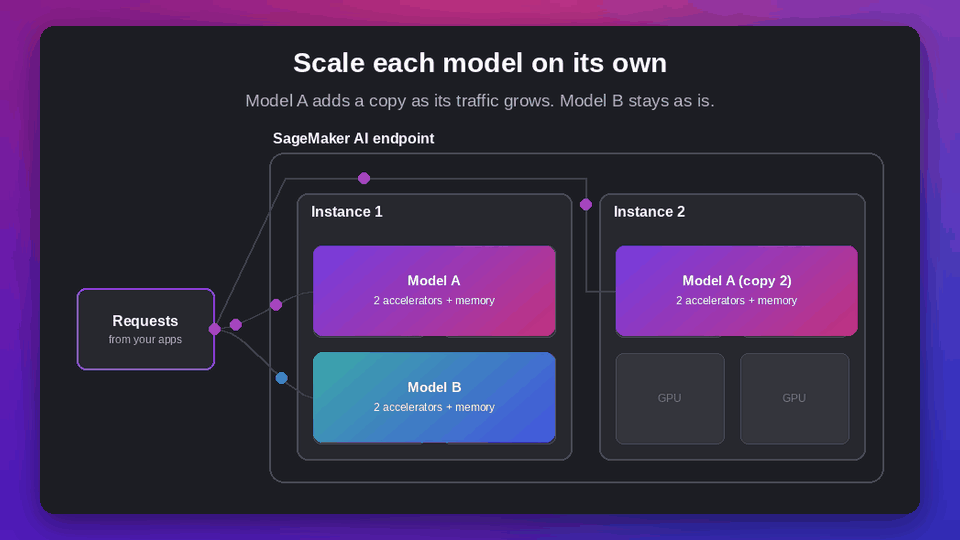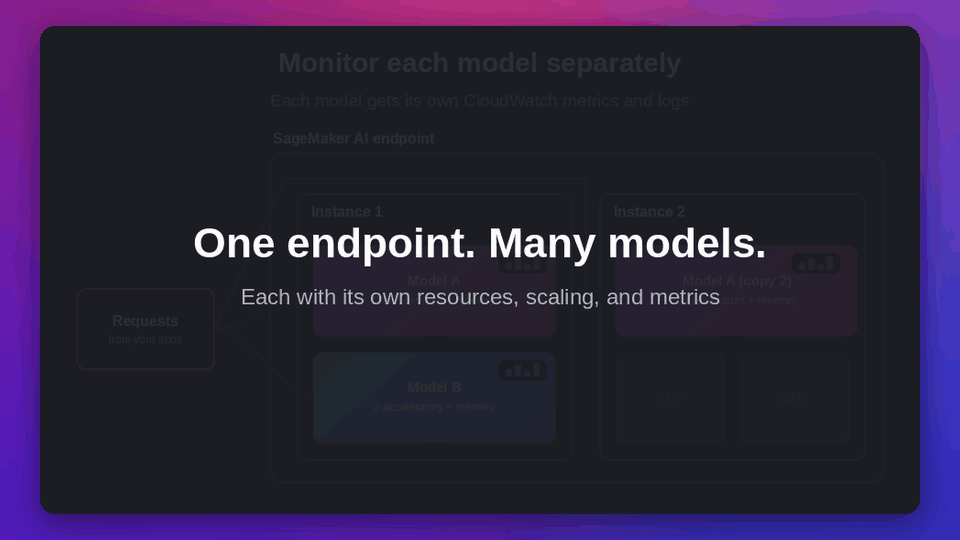
- Stop paying for idle GPUs by packing thousands of models onto one endpoint, with isolated compute, independent scaling, and scale-to-zero working together
- Cut costs by up to 40% and stop paying for duplicate infrastructure, as Task Governance unifies training and inference on one cluster
- Save up to 65% versus on-demand, as self-service capacity reservations lock in the GPUs you need
- Handle traffic spikes with 50% lower end-to-end scale-out latency, as container images and weights are cached locally, with no setup on managed endpoints
Control without compromise
Keep control of your infrastructure, with governance and observability built in.
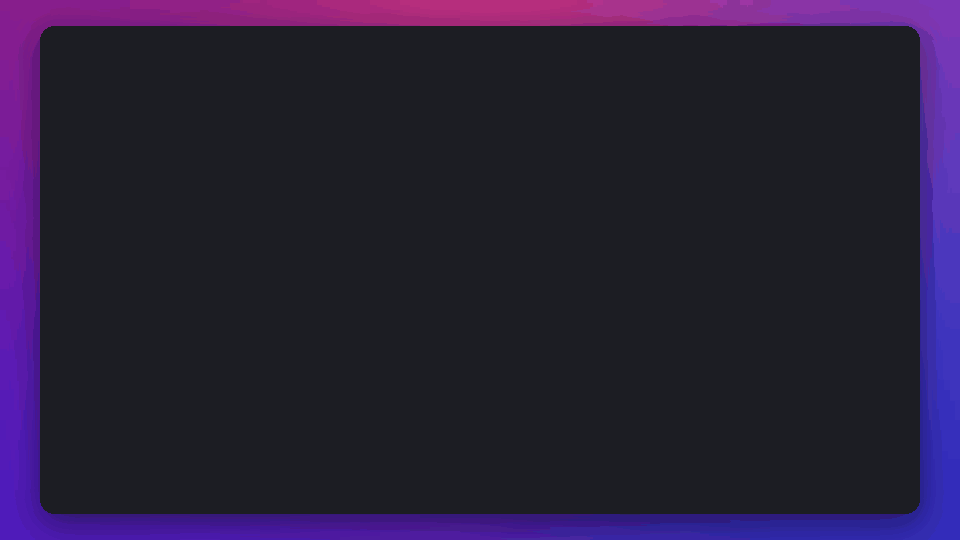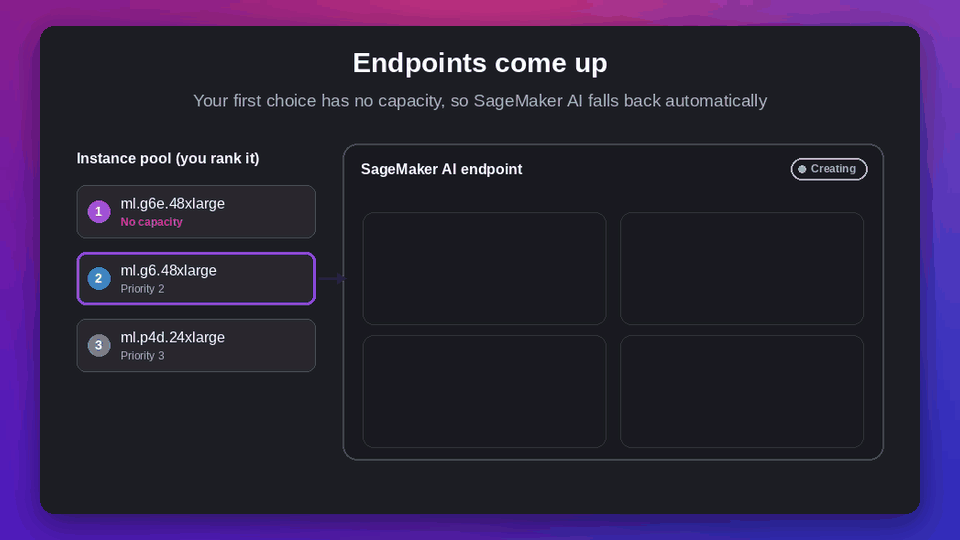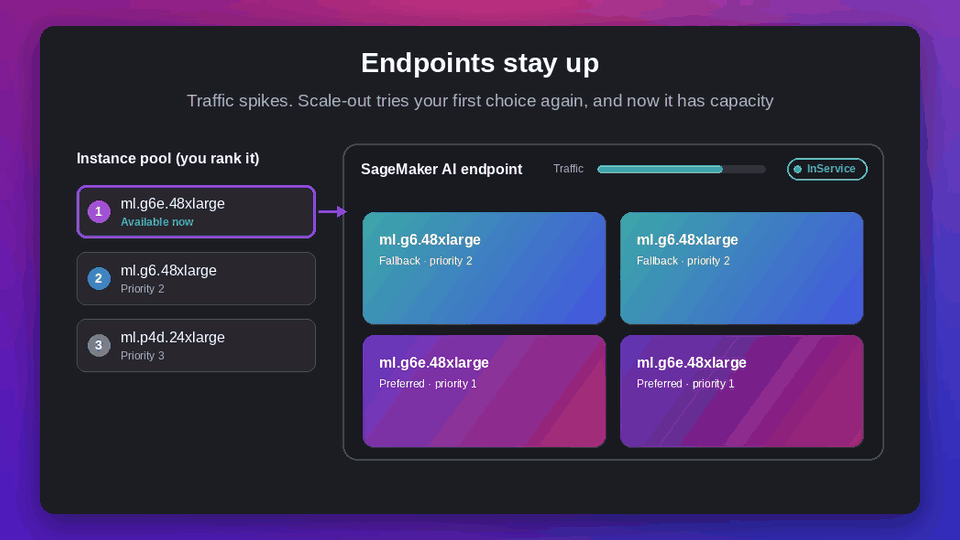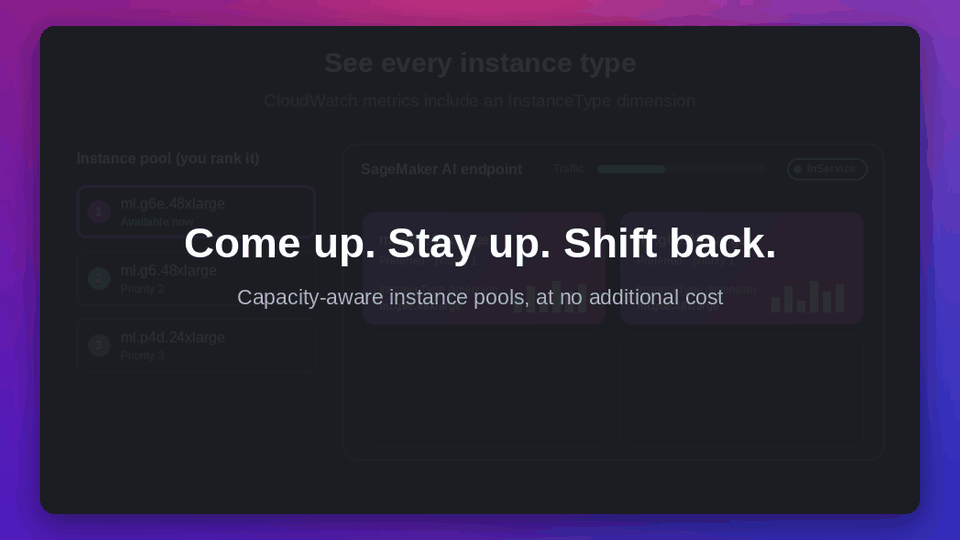
- Keep inference running when GPUs are scarce, as capacity-aware instance pools fall back to other instance types automatically and shift back to your preferred hardware as capacity frees up
- Route every request to the best-suited pod, as HyperPod Inference Gateway reads real-time GPU signals, with one EKS add-on and no application changes
- Stay inside your security boundaries, with VPC isolation, fine-grained IAM permissions, and support for SOC 2, HIPAA, and FedRAMP workloads
- Prove compliance with request and response logs captured to Amazon S3 at the endpoint, load balancer, and model pod, with no custom sidecars or code changes
- Spot and fix issues faster with your preferred tools, as observability is built in across model development and compute, from open source to managed (MLflow, Grafana, Prometheus, CloudWatch)
Proven in production. Chosen by leaders.
Salesforce packs its CodeGen models onto shared GPUs with inference components, achieving up to an 8x reduction in deployment and infrastructure costs.
Optimizing Salesforce’s model endpoints with Amazon SageMaker AI inference components
Razorpay trained Vulcan on about 3 trillion data points across 4 billion payments with Amazon SageMaker AI, lifting payment success rates by 8 to 10%.
Razorpay launches Vulcan, India’s first AI payments foundation model
TBC’s optimized text-to-video model delivers 5x faster generation at 80% lower inference cost, and will be deployable through Amazon SageMaker AI.
The Biological Computing Co. partners with AWS to bring the world’s first neuron-derived AI video model to market
By using Siemens Industrial AI built on Industrial Edge and AWS, we’ve experienced a rapid improvement in the automation of our ML pipeline
Marvin Herchenbach, Process Engineer, Siemens Electronics Factory Erlangen
Start with serverless. Step up to dedicated inference when the workload demands.
Every path connects privately to your VPC. Choose the level of control your team needs.
Serverless Endpoints
Pay per token, no infrastructure to manage
- Access hundreds of top foundation models (FMs) to power your applications, and swap them in and out without rewriting code
- Pay only for the tokens you use, with no idle GPUs and no upfront commitments
- Built-in guardrails, RAG, and agent orchestration for production-ready generative AI applications
- Automatic scaling that absorbs traffic spikes without manual intervention
Managed Endpoints
Dedicated infrastructure, deploy in hours
- Multi-model packing with isolated compute, independent scaling, and scale-to-zero
- OpenAI-compatible APIs for drop-in LLM serving
- Automated recommendations across 250+ instance types
- No Kubernetes expertise required
HyperPod Inference
Kubernetes-native control, unified training and inference
- Run training and inference on one cluster, as Task Governance shifts GPUs to your highest-priority work automatically
- Kubernetes-native on Amazon EKS: kubectl, CRDs, Helm, and Ray Serve
- Tiered KV cache and intelligent routing reduce latency by up to 40% for long-context and multi-turn workloads
- Disaggregated prefill and decode for consistent latency under mixed traffic
The teams shipping fastest run on dedicated infrastructure.
Up to 8x lower deployment and infrastructure costs at Salesforce, packing models onto shared GPUs with inference compone
instance types auto-benchmarked for cost, latency, or throughput. Weeks of manual testing, done in hours
Common questions about SageMaker Inference
Questions
Open allChoose managed endpoints when you want to deploy in hours with no Kubernetes expertise required. Choose HyperPod when you need Kubernetes-native control, want to run training and inference on one cluster with priority-based preemption, or want standard Kubernetes tooling on EKS.
Multi-model packing with scale-to-zero reduces costs. Task Governance on HyperPod unifies training and inference clusters, cutting costs by up to 40%.
Any model. Choose from 1,000+ pre-optimized models in JumpStart, or bring your own in any container. Built-in runtimes include vLLM, SGLang, and TensorRT-LLM.
Define up to five instance types in priority order. SageMaker falls back through the list during creation, scale-out, and scale-in, and self-optimizes toward preferred hardware as capacity becomes available.
SOC 2, HIPAA, FedRAMP Moderate + High (GovCloud), ISO 27001, and PCI-DSS across 30+ regions. All inference runs on single-tenant dedicated instances that connect privately to your VPC.
Start deploying models on SageMaker AI
Deploy an open source model on dedicated infrastructure and a production endpoint is live in hours. You own the weights, control the runtime, and see exactly what every GPU hour costs.