Containers

Author: Vara Bonthu
Vara Bonthu is a dedicated technology professional and Worldwide Tech Leader for Data on EKS, specializing in assisting AWS customers ranging from strategic accounts to diverse organizations. He is passionate about open-source technologies, Data Analytics, AI/ML, and Kubernetes, and boasts an extensive background in development, DevOps, and architecture. Vara's primary focus is on building highly scalable Data and AI/ML solutions on Kubernetes platforms, helping customers harness the full potential of cutting-edge technology for their data-driven pursuits.
Scaling StarRocks on Amazon EKS with KEDA and Karpenter for enterprise OLAP workloads
Financial analytics at enterprise scale is unforgiving. Queries must return in seconds, not minutes. Thousands of finance professionals need concurrent access during monthly close cycles. And when data volumes grow from hundreds of gigabytes to terabytes, spanning billions of records, the infrastructure underneath must scale without forcing engineers to choose between performance and cost. This […]
Unlocking next-generation AI performance with Dynamic Resource Allocation on Amazon EKS and Amazon EC2 P6e-GB200
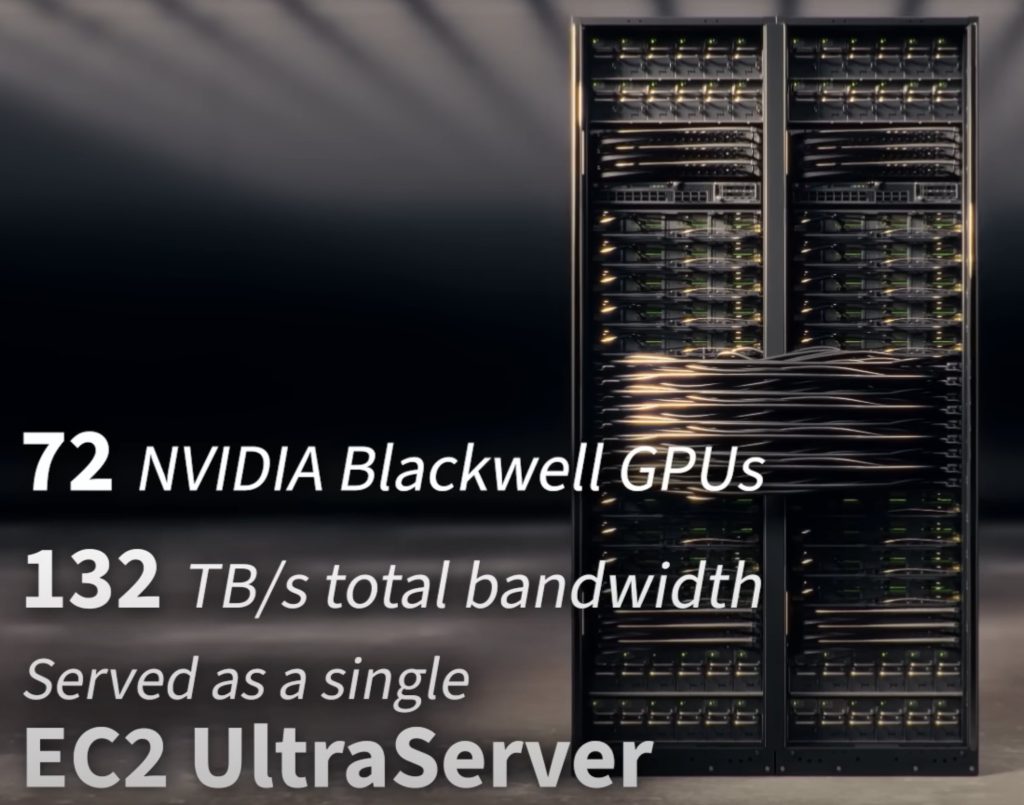
In this post, we explore how Amazon EC2 P6e-GB200 UltraServers are transforming distributed AI workload through seamless Kubernetes integration, featuring NVIDIA GB200 Grace Blackwell architecture that enables memory-coherent domains of up to 72 GPUs. The post demonstrates how Dynamic Resource Allocation (DRA) on Amazon EKS enables sophisticated GPU topology management and cross-node GPU communication through IMEX channels, making it possible to efficiently train and deploy trillion-parameter AI models at scale.

Inside Pinterest’s Custom Spark Job logging and monitoring on Amazon EKS: Using AWS for Fluent Bit, Amazon S3, and ADOT
In Part 1, we explored Moka’s high-level design and logging infrastructure, showcasing how AWS for Fluent Bit, Amazon S3, and a robust logging framework make sure of operational visibility and facilitate issue resolution. For more details, read part 1 here. Introduction As we transition to the second part of our series, our focus shifts to […]

Inside Pinterest’s Custom Spark Job logging and monitoring on Amazon EKS: Using AWS for Fluent Bit, Amazon S3, and ADOT
This is Part 1 of the blog post. Introduction Pinterest is a visual search and curation platform focused on inspiring users to create a life they love. Critical to the service are data insights, recommendations and machine learning (ML) models that are produced by synthesizing insights provided by the over 500 million monthly active users […]

Run Spark-RAPIDS ML workloads with GPUs on Amazon EMR on EKS
Introduction Apache Spark revolutionized big data processing with its distributed computing capabilities, which enabled efficient data processing at scale. It offers the flexibility to run on traditional Central Processing Unit (CPUs) as well as specialized Graphic Processing Units (GPUs), which provides distinct advantages for various workloads. As the demand for faster and more efficient machine […]