Migrating from Apache Hudi-based data lake to Apache Iceberg-based data lake
A cloud data lake is a scalable, low-cost place to store data from many different sources. Over the years, data lakes built on Amazon Simple Storage Service (Amazon S3) have become a common home for enterprise data, used by teams who query it for analytics and machine learning. However, data lakes have historically made it hard to update and delete records, keep transactions isolated, and handle concurrent changes safely. Open table formats such as Apache Hudi, Delta Lake, and Apache Iceberg were created to solve these problems. They add ACID transactions and row-level updates and delete, along with snapshot history and schema enforcement that make data lakes easier to audit and govern.
As organizations’ data architectures mature and evolve, the need to migrate between these table formats becomes increasingly common. This transition is often driven by changing requirements, performance considerations, or the desire to use newer features. Among these migrations, the shift from Apache Hudi to Apache Iceberg has gained particular attention, as organizations seek to capitalize on Iceberg’s modern architecture and advanced capabilities.
In this post, we show how to convert Apache Hudi tables to Apache Iceberg, using a Jupyter notebook running on AWS Glue 5.1 interactive sessions.
Benefits of migration to Iceberg
Enhanced partition evolution
Iceberg supports dynamic changes to partitioning schemes without requiring complete data rewrites. This capability is valuable in evolving data environments where query patterns change over time. You can adjust your partitioning strategy to optimize performance, reducing the operational overhead traditionally associated with such changes. Your data lake can adapt to changing business requirements without costly reorganization efforts.
Hidden partitioning
In addition to standard partitioning on an existing column, Iceberg supports hidden partitioning, which decouples the physical partition layout from the columns that queries filter on. The table specification declares a partition transform, which is a rule that tells Iceberg how to derive the partition value from a source column, such as a time bucket or a hash of the column value. The transform is defined once at the table level, and Iceberg applies it automatically on every write. This removes a long-standing source of friction on both sides of the table: writers no longer need to extract and maintain a separate partition column alongside the real one at ingestion time, and queries no longer need to carry an extra predicate on that derived column to get good performance.
Openness with the Iceberg REST Catalog
The Iceberg REST Catalog specification defines a standard HTTP protocol for catalog operations. Any engine that speaks the protocol can talk to any catalog that implements it, without a catalog-specific client library or implementation JAR on the class path. Integration moves from a code and dependency problem to a configuration problem, making Iceberg a strong fit for multi-engine data architectures.
Deep integration with AWS services
Iceberg has native integration across the AWS analytics ecosystem. Amazon Athena, Amazon Redshift, Amazon EMR, and AWS Glue all read and write Iceberg tables directly. The AWS Glue Data Catalog provides catalog and metadata management for these tables, and Amazon SageMaker builds on the same open Lakehouse foundation, letting analytics and artificial intelligence and machine learning (AI/ML) workloads share a single copy of data across Amazon S3 data lakes (including Amazon S3 Tables), with SageMaker Feature Store supporting an Iceberg offline store for faster training dataset extraction. On the ingestion side, Amazon Data Firehose delivers data into Iceberg tables from sources such as Direct PUT, Amazon Kinesis Data Streams, Amazon Managed Streaming for Apache Kafka (Amazon MSK), Amazon CloudWatch Logs, and AWS IoT, with optional on-the-fly record transformation by using AWS Lambda. No-code Streaming Tables map a single Kinesis Data Streams stream or a single Amazon MSK (Express brokers) Kafka topic to a single Amazon S3 Tables Iceberg table, with the target table auto-created and partitioning configured on the delivery channel.
AWS managed features
AWS provides managed capabilities specifically designed for Iceberg. These managed features reduce operational overhead while maintaining performance and cost efficiency, so teams can focus on deriving insights rather than managing infrastructure.
AWS Glue Iceberg table optimizer – Automated compaction, snapshot management, and orphan file cleanup without manual intervention on Iceberg tables in General S3 buckets.
Amazon S3 Tables – Fully managed Iceberg tables with automatic optimization and maintenance.
Zero-ETL integration – Managed, incremental replication from Amazon DynamoDB and third-party enterprise applications such as Salesforce, SAP, ServiceNow, and Zendesk into Iceberg tables in Amazon S3 (self-managed or Amazon S3 Tables), with no custom pipeline or connector code to maintain. Source changes are applied incrementally, so the target stays in sync without full reloads.
Iceberg materialized views – SQL-defined views materialized as native Iceberg tables, refreshed on an automatic schedule and incrementally when the source tables allow it, with change detection handled for you. Well suited to consumption-layer tables that feed dashboards, APIs, and downstream pipelines, since the work shifts from query time to the managed refresh.
These benefits make Apache Iceberg a strong choice for modern data lake implementations, offering advantages in performance, manageability, and scalability compared to traditional table formats.
In the context of migrating data to Apache Iceberg, two primary approaches exist: in-place migration and full table migration. We previously covered both in the blog post “Migrate an existing data lake to a transactional data lake using Apache Iceberg” which walks through the methodology for traditional Hive-style tables, meaning partitioned Apache Parquet, Apache ORC, or Apache Avro datasets registered in a Hive-compatible catalog. The same two approaches apply when the starting point is an Apache Hudi data lake, which comes in two flavors, Copy-on-Write (CoW) and Merge-on-Read (MoR).
In-place migration
This approach generates fresh Iceberg metadata on top of the existing data files of the source table, without rewriting the data itself. The Parquet files of a Hive, Hudi, or Delta Lake table stay in place, and a new or existing Iceberg table is pointed at them with its own metadata layer. The main advantage is cost and speed: no data rewrite, so the migration is fast and cheap on both compute and storage. The main limitation is that the Iceberg table inherits the source table’s schema, partitioning, and physical file shape (file sizes, row groups, sort order), and none of these can be changed during the migration itself.
Full table migration
In this approach, the data itself is rewritten into a new Iceberg table, typically using a writeTo() call or a CREATE TABLE AS SELECT (CTAS) statement. It works for any source an engine can read from (Hive, Hudi, Delta Lake, relational databases, and others), and because the data is being rewritten anyway, the migration step is also where you can reshape it: change the schema, apply Iceberg hidden partitioning, resort the data for pruning, and target larger file sizes than the source has. The trade-offs are cost, time, and storage: higher compute spend, longer migration, and the dataset is effectively stored twice (source and target) until the migration completes, and the source is retired. For large historical tables, a single CTAS is usually impractical, so the common pattern is to seed the table with a small CTAS and then run INSERT INTO ... SELECT partition by partition, parallelizing and checkpointing across batches.
In this post we work through both approaches end-to-end. We first create a sample Hudi event table in each flavor, CoW and MoR, then migrate them in place to Iceberg using two techniques, the Spark Iceberg add_files procedure and the Apache XTable sync tool, covering the considerations and prerequisites of each. Finally, we walk through the full table migration path, where the source data is rewritten into a new Iceberg table from scratch.
Solution overview
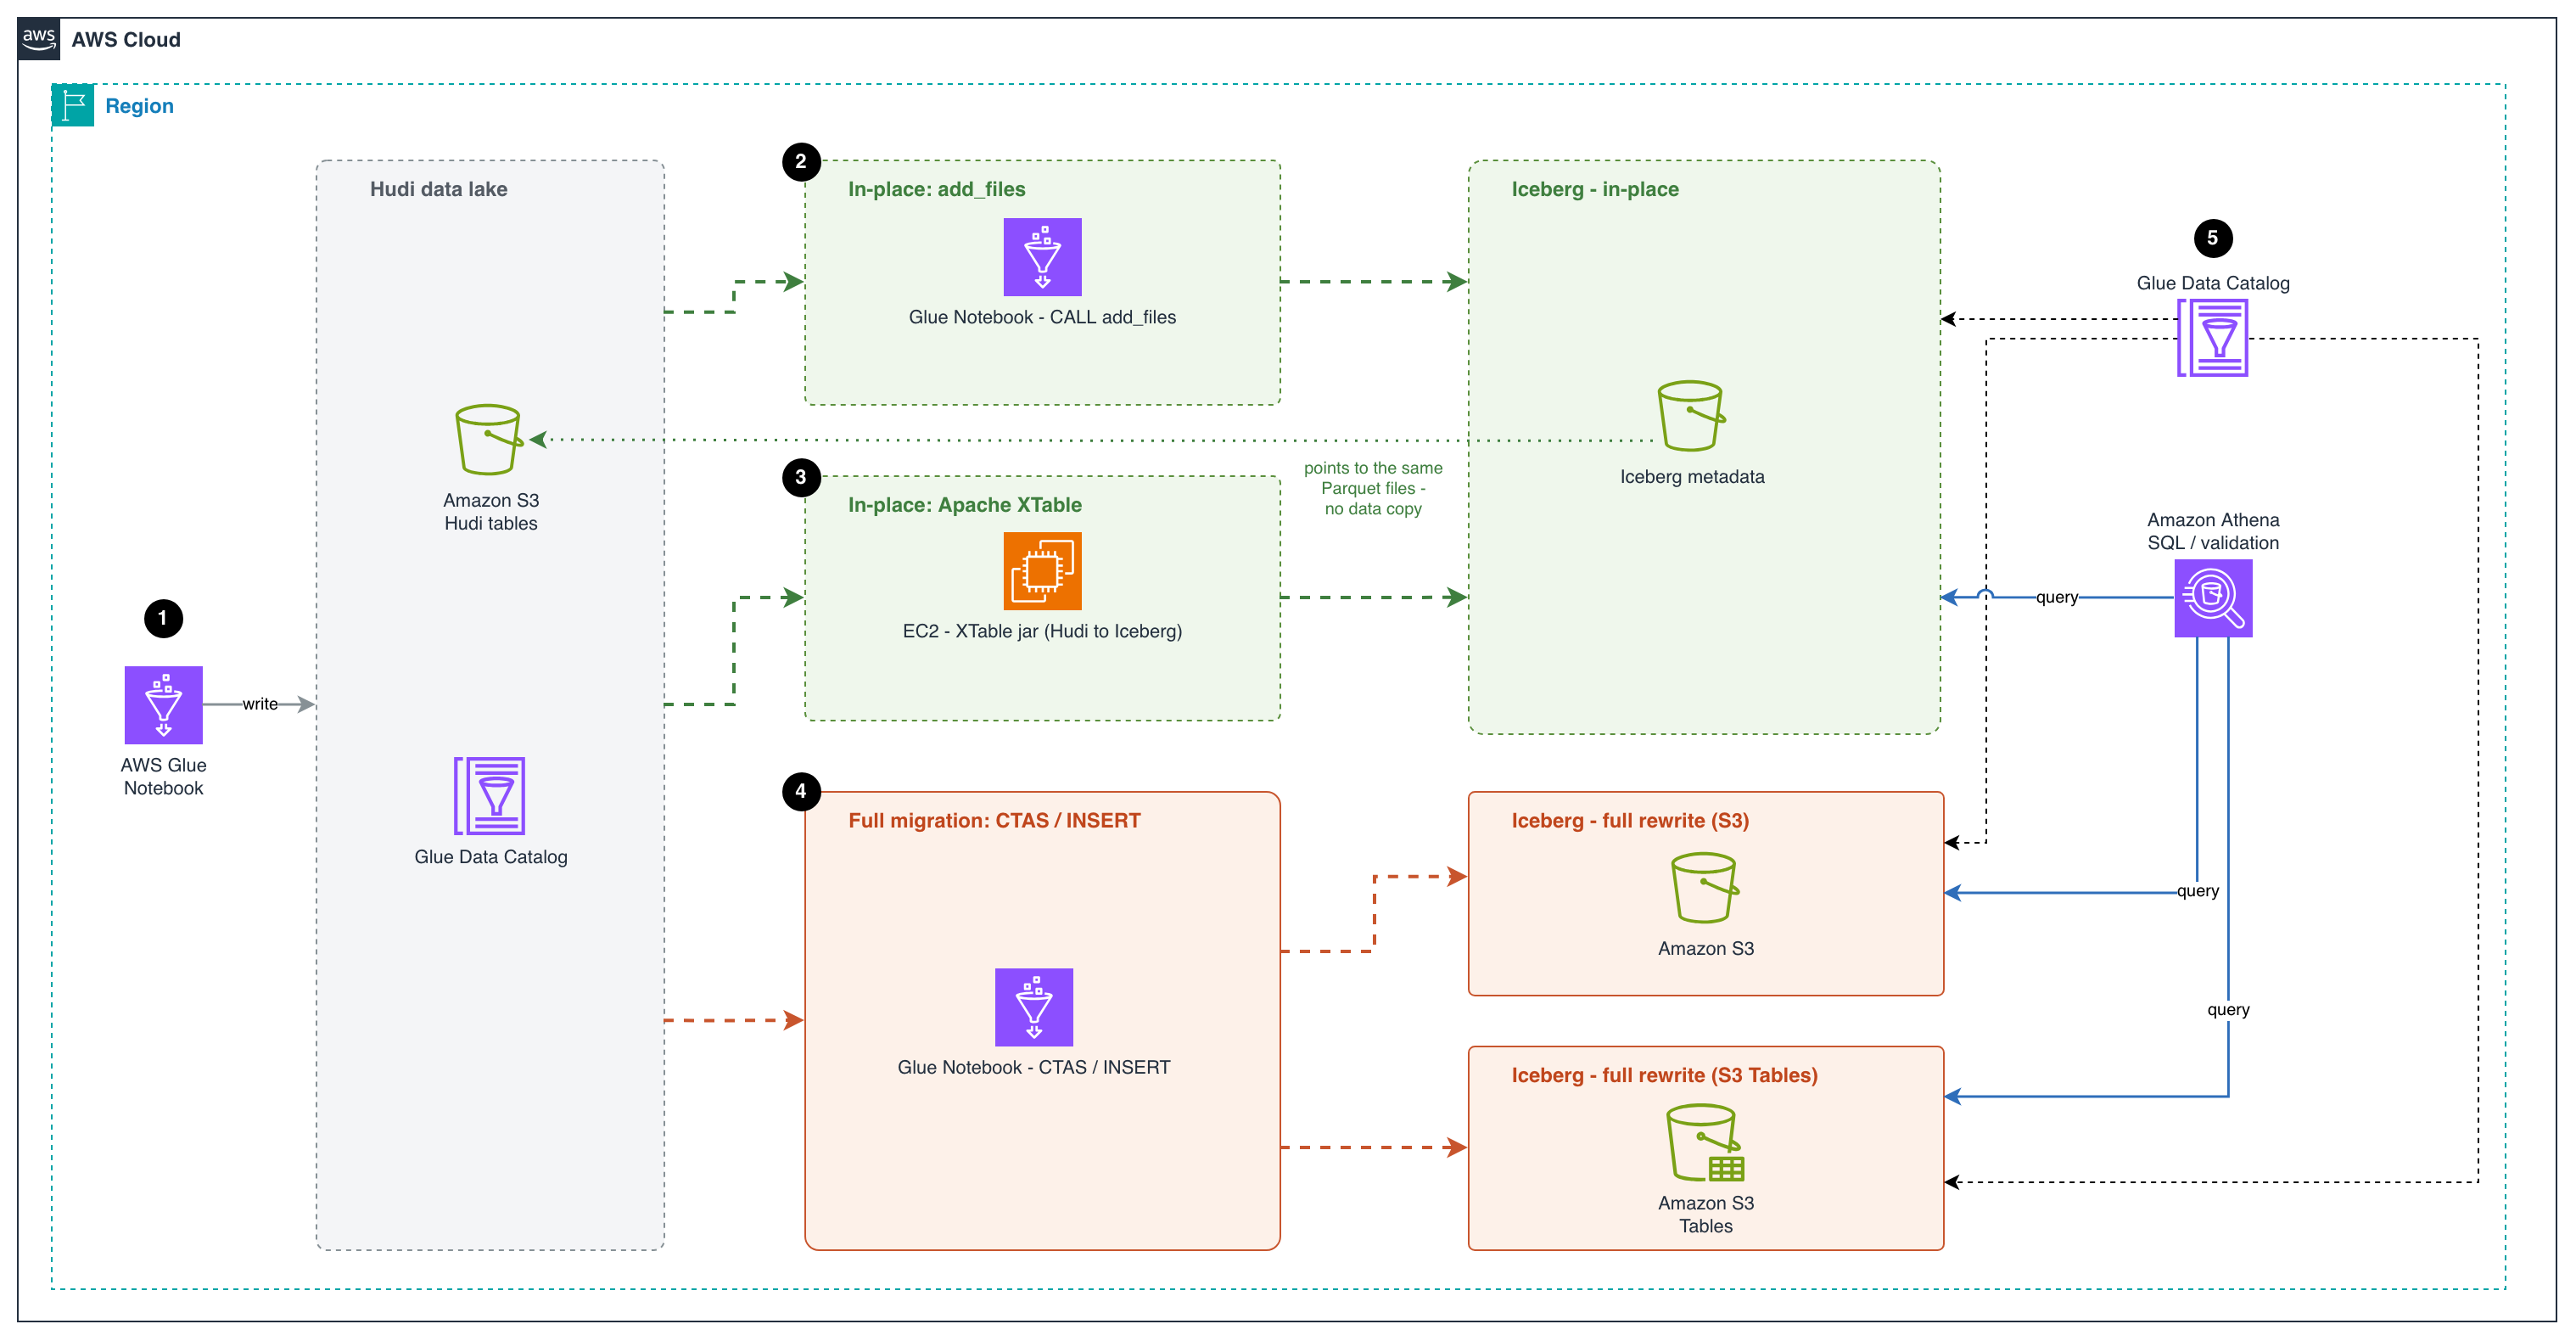
The following diagram illustrates the architecture that you implement through this post.
Figure 1: Migration architecture showing the in-place paths (add_files and Apache XTable) and the full-table paths (CTAS and INSERT) to Amazon S3 and Amazon S3 Tables, all registered in the AWS Glue Data Catalog and queried with Amazon Athena
The workflow consists of the following steps:
An AWS Glue notebook writes the source data as Apache Hudi tables to an Amazon S3 bucket and registers them in the AWS Glue Data Catalog. This creates the existing Hudi data lake that the migration starts from.
The first in-place migration approach uses an AWS Glue notebook to run the Apache Iceberg add_files procedure. The procedure creates Iceberg metadata on top of the Parquet data files already in the Hudi table. The new Iceberg metadata points to the same Parquet files, so no data is copied or rewritten. This makes it a fast, low-cost migration path.
The second in-place migration approach runs Apache XTable on an Amazon Elastic Compute Cloud (Amazon EC2) instance to convert the Hudi table metadata into Iceberg metadata. XTable reads the Hudi commit timeline and creates matching Iceberg metadata that points to the same Parquet files. Both table formats can then share a single copy of the data.
For a full migration, an AWS Glue notebook uses CREATE TABLE AS SELECT (CTAS) or INSERT INTO statements to read the Hudi data and rewrite it as new Iceberg tables. The tables can go in a general purpose S3 bucket or in Amazon S3 Tables. This approach fully separates the new tables from the Hudi source. S3 Tables also handle table maintenance for you, such as compaction and snapshot management.
The AWS Glue Data Catalog registers the Iceberg tables from all three approaches. Users can then use Amazon Athena, a serverless query service, to run SQL queries on these tables and validate the migrated data. Athena enables interactive SQL-based exploration of data directly in Amazon S3 without the need for complex infrastructure management.
Prerequisites
Before getting started, make sure you have the following:
An AWS account with a role that has sufficient access to provision the required resources.
Sign in to the AWS Management Console and open the AWS Glue console.
In the Region selector (top right), choose your preferred working Region.
Choose ETL Jobs in the left pane.
Choose Notebook under Author using an interactive code notebook, select Start fresh, choose your IAM role, and choose Create notebook.
After a minute, the Jupyter notebook editor appears. Clear all the default cells.
Create Hudi Copy-on-Write (CoW) and Merge-on-Read (MoR) sample event tables
This notebook creates Hudi tables using both Copy-on-Write (CoW) and Merge-on-Read (MoR) table types with sample events. We perform inserts, updates, and deletes, then inspect the underlying file structures to understand the key differences:
CoW: an update or delete fully rewrites every base Parquet file that contains an impacted row, producing a new file slice in the file group. Reads are cheap, and writes amplify with the fraction of files touched.
MoR: an update or delete is appended to an Avro log file alongside the base file instead of rewriting the base, and base + logs are merged at read time (or compacted into a new base file later). Cheaper writes. Costlier reads until compaction.
Execute the first cell with the following configuration to set up the Spark session with Hudi and Iceberg support:
Initialize the session and configuration. Update the bucket_name, db_name and region variables with your configurations. Reusable helper – list_table_files(table_name, label="", verbose=False) renders a table’s S3 layout as a directory tree so you can SEE how CLEAN, COMPACT and add_files change the files underneath. It is reused before/after each of those steps instead of re-coding the listing.
Code:
# ──────────────────────────────────────────────
# Source Hudi tables
# ──────────────────────────────────────────────
hudi_events_cow_table = "events_hudi_cow" # Copy-on-Write source
hudi_events_mor_table = "events_hudi_mor" # Merge-on-Read source
# ──────────────────────────────────────────────
# In-place migration targets (add_files/xtable)
# ──────────────────────────────────────────────
iceberg_cow_inplace = "events_iceberg_cow_inplace"
iceberg_mor_inplace = "events_iceberg_mor_inplace"
iceberg_cow_xtable = "events_hudi_cow_iceberg_xtable"
iceberg_mor_xtable = "events_hudi_mor_iceberg_xtable"
# ──────────────────────────────────────────────
# Full table (shadow) migration targets
# ──────────────────────────────────────────────
iceberg_cow_full_ctas = "events_iceberg_cow_full_ctas"
iceberg_cow_full_create_insert = "events_iceberg_cow_full_create_insert"
iceberg_mor_full_ctas = "events_iceberg_mor_full_ctas"
iceberg_mor_full_create_insert = "events_iceberg_mor_full_create_insert"
# ──────────────────────────────────────────────
# Infrastructure
# ──────────────────────────────────────────────
bucket_name = "demoblogiceberg-bdb5001" # S3 bucket for data
db_name = "hudi_to_iceberg_blog" # Glue Data Catalog database
region = "us-east-1"
# Create the Glue Data Catalog database
spark.sql(f"""
CREATE DATABASE IF NOT EXISTS {db_name}
LOCATION 's3://{bucket_name}/{db_name}'
""")
# Reusable helper —list_table_files()(S3 layout tree)
import boto3
s3 = boto3.client('s3', region_name=region)
# File/folder annotations keyed by classifier result
_NOTES = {
"hoodie_dir": "<-- Hudi metadata (timeline, schema, indexes)",
"hoodie_mdt": "<-- Hudi metadata table (internal index & stats, MoR)",
"hoodie_files": "<-- file listing index",
"hoodie_cstats":"<-- column-level min/max/null stats",
"hoodie_ridx": "<-- record-key -> file-group mapping",
"ice_meta_dir": "<-- Iceberg metadata layer (metadata.json, manifest lists, manifests)",
"ice_data_dir": "<-- Iceberg data layer (base Parquet files)",
"base": "<-- base Parquet file",
"log": "<-- Hudi delta log file (MoR update, uncompacted)",
"part_meta": "<-- Hudi partition marker",
"metadata_json":"<-- Iceberg table metadata (schema, snapshots)",
"manifest_list":"<-- Iceberg manifest list (snapshot -> manifests)",
"manifest": "<-- Iceberg manifest (lists data files)",
"props": "<-- table configuration & schema",
}
# Fixed-path annotations for metadata directories
_DIR_KIND = {
".hoodie": "hoodie_dir", ".hoodie/metadata": "hoodie_mdt",
".hoodie/metadata/files": "hoodie_files",
".hoodie/metadata/column_stats": "hoodie_cstats",
".hoodie/metadata/record_index": "hoodie_ridx",
"metadata": "ice_meta_dir", "data": "ice_data_dir",
}
def _fmt_size(n):
"""Human-readable byte size."""
for u in ("B", "KB", "MB", "GB", "TB"):
if n < 1024 or u == "TB":
return f"{n:,.0f} {u}" if u == "B" else f"{n:,.1f} {u}"
n /= 1024.0
def _leaf_kind(name):
"""Classify a leaf file by name -> annotation key / count bucket."""
if ".log." in name: return "log"
if name.startswith(".hoodie_partition_metadata"): return "part_meta"
if name == "hoodie.properties": return "props"
if name.endswith(".metadata.json"): return "metadata_json"
if name.startswith("snap-") and name.endswith(".avro"): return "manifest_list"
if name.endswith(".avro"): return "manifest"
if name.endswith(".parquet"): return "base"
return ""
def list_table_files(table_name, label="", verbose=False, max_depth=2, max_children=2):
"""Render a Hudi/Iceberg table's S3 layout as an annotated directory tree.
Teaching view for CLEAN/COMPACT/add_files: multiple base files in a partition
= stale file slices; .log.* = uncompacted MoR updates. The large Hudi .hoodie/
is summarized (depth/width capped); Iceberg metadata/ and data partitions show
in full. verbose=True expands everything.
"""
prefix = f"{db_name}/{table_name}/"
header = f"s3://{bucket_name}/{prefix}"
if label:
header += f" [{label}]"
print(header)
in_meta = lambda p: (p.split("/", 1)[0] if p else "") in (".hoodie", "metadata")
capped_meta = lambda p: (p.split("/", 1)[0] if p else "") == ".hoodie"
# ---- gather objects into a nested tree + tally honest counts -----------
root = {"d": {}, "f": []}
n_base = n_log = n_meta = n_other = 0
s_base = s_log = s_meta = 0
has_hudi = has_ice = False
for page in s3.get_paginator("list_objects_v2").paginate(Bucket=bucket_name, Prefix=prefix):
for obj in page.get("Contents", []):
key = obj["Key"].replace(prefix, "")
size = obj["Size"]
if key == "" or key.endswith("/"):
continue # S3 directory marker
parts = key.split("/")
fname, top = parts[-1], parts[0]
if top == ".hoodie": has_hudi = True
if top == "metadata": has_ice = True
# files inside a metadata folder count ONLY as metadata
if top in (".hoodie", "metadata"):
n_meta += 1; s_meta += size
elif ".log." in fname:
n_log += 1; s_log += size
elif fname.endswith(".parquet"):
n_base += 1; s_base += size
elif fname.startswith(".hoodie"):
n_meta += 1; s_meta += size; has_hudi = True
else:
n_other += 1
node = root
for part in parts[:-1]:
node = node["d"].setdefault(part, {"d": {}, "f": []})
node["f"].append((fname, size))
# ---- helpers -----------------------------------------------------------
def count_all(node):
return len(node["f"]) + sum(count_all(c) for c in node["d"].values())
def collapse(node, name, rel):
"""Merge single-child, file-less dir chains (year=/month=/day=)."""
while (len(node["d"]) == 1 and not node["f"] and not in_meta(rel)):
cname, child = next(iter(node["d"].items()))
crel = f"{rel}/{cname}"
if in_meta(crel): break
name, rel, node = f"{name}/{cname}", crel, child
return name, rel, node
def line(indent, branch, text, note, width):
s = f"{indent}{branch}{text}"
return f"{s:<{width}} {note}" if note else s
def render(node, rel, indent, depth):
entries = ([("d", n, c) for n, c in sorted(node["d"].items())]
+ [("f", n, sz) for n, sz in sorted(node["f"], key=lambda f: (".log." in f[0], f[0]))])
cap = (not verbose) and capped_meta(rel) and len(entries) > max_children
shown = entries[:max_children] if cap else entries
hidden = len(entries) - len(shown)
for i, item in enumerate(shown):
last = (i == len(shown) - 1) and hidden == 0
branch = "└── " if last else "├── "
sub = indent + (" " if last else "│ ")
if item[0] == "d":
_, name, child = item
disp, erel, enode = collapse(child, name, f"{rel}/{name}" if rel else name)
note = _NOTES.get(_DIR_KIND.get(erel, ""), "")
cnt = f" ({count_all(enode)} obj)" if (in_meta(erel) or erel in _DIR_KIND) else ""
print(line(indent, branch, f"{disp}/{cnt}", note, 60))
if (not verbose) and capped_meta(erel) and depth + 1 > max_depth:
inner = count_all(enode)
if inner:
print(f"{sub}└── … ({inner} objects, use verbose=True)")
else:
render(enode, erel, sub, depth + 1)
else:
_, name, size = item
note = _NOTES.get(_leaf_kind(name), "")
print(line(indent, branch, f"{name} ({_fmt_size(size)})", note, 72))
if hidden:
print(f"{indent}└── … (+{hidden} more)")
render(root, "", "", 0)
# ---- per-partition slice note (Hudi concept; skip metadata & Iceberg data/) ----
def slices(node, rel):
top = rel.split("/", 1)[0] if rel else ""
if top in (".hoodie", "metadata", "data"):
return
nb = sum(1 for f, _ in node["f"] if f.endswith(".parquet"))
nl = sum(1 for f, _ in node["f"] if ".log." in f)
if nb > 1:
print(f" note: {rel}/ has {nb} base files -> multiple file slices (stale versions)")
elif nb == 1 and nl:
print(f" note: {rel}/ has 1 base + {nl} log file(s) -> uncompacted MoR updates")
for n, c in node["d"].items():
slices(c, f"{rel}/{n}" if rel else n)
slices(root, "")
# ---- in-place migration note -------------------------------------------
if has_ice and "data" not in root["d"] and n_base == 0:
print(" note: Iceberg metadata/ present but no local data/ folder")
print(" -> in-place migration: data files remain registered in place at the source (Hudi) location; no data copied")
# ---- summary -----------------------------------------------------------
total = n_base + n_log + n_meta + n_other
print(
f"SUMMARY: {n_base} base · {n_log} log · {n_meta} meta"
+ (f" · {n_other} other" if n_other else "")
+ f" · {total} files · {_fmt_size(s_base + s_log + s_meta)}"
)
print(f" .hoodie/: {'present' if has_hudi else 'none'} metadata/ (Iceberg): {'present' if has_ice else 'none'}")
print()
Sample event data
We use a website clickstream events dataset, partitioned by year/month/day – a realistic pattern for event-driven architectures.
Note: In this example, we create the table with a preCombineField, which flips the default write operation of INSERT INTO from insert to upsert. You can override it explicitly with hoodie.spark.sql.insert.into.operation when you need a different behavior.
CoW table: create, upsert, and delete
We create a Hudi CoW table, insert records, apply an upsert, and delete a record, then inspect how the files change.
Create the Hudi CoW events table
Code:
spark.sql(f"""
CREATE TABLE {db_name}.{hudi_events_cow_table} (
event_id STRING,
user_id STRING,
event_type STRING,
event_timestamp TIMESTAMP,
page_url STRING,
year INT,
month INT,
day INT
)
USING HUDI
OPTIONS (
type = 'cow',
primaryKey = 'event_id',
preCombineField = 'event_timestamp'
)
PARTITIONED BY (year, month, day)
LOCATION 's3://{bucket_name}/{db_name}/{hudi_events_cow_table}/'
""")
print("=== COW Table (events_hudi_cow) ===")
spark.sql(f"SELECT event_id, user_id, event_type, event_timestamp, page_url, year, month, day FROM {db_name}.{hudi_events_cow_table} ORDER BY event_id").show(truncate=False)
print("\n=== MOR Table (events_hudi_mor) ===")
spark.sql(f"SELECT event_id, user_id, event_type, event_timestamp, page_url, year, month, day FROM {db_name}.{hudi_events_mor_table} ORDER BY event_id").show(truncate=False)
Migrate Hudi tables to Iceberg with in-place migration
In-place migration keeps the original Parquet data files where they are and only builds Iceberg metadata on top of them. There is no rewrite of the underlying data, which makes the migration fast and inexpensive even on large tables. Two tools cover the common cases on AWS:
add_files (Iceberg built-in procedure). A Spark procedure shipped with Apache Iceberg that registers existing Parquet files into an Iceberg table by writing the corresponding manifests, without rewriting the data. It runs as a Spark job in which the source table’s partitions are distributed across Spark tasks, so file listing and column-statistics gathering happen in parallel on the cluster.
Apache XTable (incubating). An open-source cross-format translation tool that can read the metadata of one lakehouse format (Hudi, Delta, or Iceberg) and write out the equivalent metadata for another, pointing at the same underlying Parquet files. XTable can run once to produce the initial Iceberg metadata, or run on a schedule to keep the Iceberg view continuously in sync with ongoing writes to the Hudi table.
Choosing between add_files and Apache XTable for in-place migration
When planning an in-place migration, it is important to understand the strengths of each approach:
add_files is best suited for a one-time migration. It registers existing Hudi Parquet files into an Iceberg table in a single operation. After the migration is complete, the source Hudi table and target Iceberg table are independent, and any subsequent changes to the Hudi table are not reflected in Iceberg.
Apache XTable supports both an initial one-time conversion and ongoing incremental synchronization. This makes it ideal for transition periods where you need to keep both the source Hudi tables and the target Iceberg tables in sync while downstream consumers gradually migrate to Iceberg. After all workloads have been cut over, you can stop the sync process and decommission the Hudi tables.
Important notes
add_files/XTable register existing Parquet files as-is, so they rely on the column names baked into each file. Added and dropped columns are safe, but if the source table was renamed any column during its lifecycle, files written before the rename still hold the old name and reads against the new name return NULL for them. For tables with a history of column renames, prefer a full migration instead.
Iceberg version and column statistics (in-place add_files / snapshot): In Iceberg 1.9.0 through 1.10.0, the add_files and snapshot procedures don’t generate column stats in the Iceberg metadata. The cause is a NameMapping loss in ParquetUtil.footerMetrics. Without those column-level lower/upper bounds and null counts, the migrated Iceberg table loses most of its file-skipping ability at query planning time, which translates into more Parquet files being inspected, higher scan volume, and slower queries, especially for selective filters on non-partition columns. The issue is fixed in the Iceberg 1.10.1 release (#14617). Affected runtimes are AWS Glue 5.1 and Amazon EMR 7.11–7.13. We recommend AWS Glue 6.0+ or Amazon EMR 7.14+ for production migrations.
Shared data files during in-place migration: With both approaches, the in-place migration doesn’t copy data. The resulting Iceberg table points to the same underlying Parquet files as the source Hudi table. This means that until you perform a full cutover to Iceberg, you must avoid destructive operations on the Iceberg table that could delete or modify the shared data files. Specifically:
Don’t drop the Iceberg table with the PURGE option.
Don’t run Iceberg maintenance tasks such as expire_snapshots or remove_orphan_files.
Running any of these before cutover can remove files that the source Hudi table still depends on, leading to data loss. Iceberg exposes a built-in guardrail against this: the gc.enabled table property. When set to false, Iceberg blocks the preceding destructive operations. How you apply this depends on which migration path you choose.
With add_files. Disable garbage collection immediately after the procedure finishes and keep it disabled until you have fully cut over to Iceberg.
Right after add_files:
spark.sql(f"""
ALTER TABLE {db_name}.{table_name}
SET TBLPROPERTIES ('gc.enabled' = 'false');
""")
After Hudi source is retired and the Iceberg table owns its own data, re-enable GC so maintenance can run normally:
spark.sql(f"""
ALTER TABLE {db_name}.{table_name}
SET TBLPROPERTIES ('gc.enabled' = 'true');
""")
With Apache XTable (incremental sync). The gc.enabled = false guardrail is only partially usable here, because XTable’s incremental sync needs GC to be enabled on the Iceberg table to operate normally. A practical pattern is:
Run the initial full XTable sync.
Temporarily set gc.enabled = false to run post-migration validation and consistency checks on the Iceberg table in a safe state.
Set gc.enabled = true again before starting incremental sync and leave it on for the duration of the sync period.
Because the automatic guardrail is off during incremental sync, the burden shifts to operational discipline: as long as XTable is syncing and data files are shared with the Hudi table, don’t run any Iceberg operation that can delete source data files (no DROP TABLE ... PURGE, no expire_snapshots, no remove_orphan_files, no manual object deletion against the shared S3 prefix). Treat the Iceberg table as read-only in terms of file lifecycle until cutover is complete, and Hudi is decommissioned, at which point normal Iceberg maintenance can resume.
Don’t enable the AWS Glue Data Catalog table optimizer before cutover.
Glue-managed Iceberg maintenance (compaction, snapshot retention, orphan file cleanup) will rewrite or delete the Parquet files that the source Hudi table still depends on. Verify that no catalog-level optimizer applies to the migrated table and leave table-level optimization off until cutover is complete.
Prerequisites for in-place migration with add_files. The add_files procedure registers every Parquet file it finds under the source location into the target Iceberg table, with no awareness of Hudi’s file-group versioning. If more than one file version of the same record is present at migration time, each version is registered as a separate row, and the Iceberg table will contain duplicates. The source Hudi table must therefore expose exactly one file version per record before add_files runs:
CoW tables: Run CLEAN to remove old file versions, keeping only the latest Parquet files.
MoR tables: Run COMPACTION (merge delta logs into base Parquet) + CLEAN before calling add_files, since add_files can only register base Parquet files and cannot process Hudi delta log files.
Option 1: Migrate Hudi tables to Iceberg with the add_files Spark procedure
This option uses the Iceberg add_files procedure to register the existing Hudi Parquet files into new Iceberg tables. Run it once per table, after preparing the Hudi table so that only the current file versions remain.
Migrate CoW to Iceberg
We create the target Iceberg table, prepare the Hudi source so that only the current file versions remain, register those files, and validate the result.
Create the target Iceberg table with the same schema
Code:
spark.sql(f"""
CREATE TABLE glue_iceberg.{db_name}.{iceberg_cow_inplace} (
event_id STRING,
user_id STRING,
event_type STRING,
event_timestamp TIMESTAMP,
page_url STRING,
year INT,
month INT,
day INT
)
USING iceberg
PARTITIONED BY (year, month, day)
LOCATION 's3://{bucket_name}/{db_name}/{iceberg_cow_inplace}/'
""")
Run Hudi CLEAN to keep only the latest file versions
Check files listing for the Hudi table before the CLEAN operation:
Code:
list_table_files(hudi_events_cow_table, "COW --- BEFORE CLEAN")
Output:
s3://demoblogiceberg-bdb5001/hudi_to_iceberg_blog/events_hudi_cow/ [COW — BEFORE CLEAN]
├── .hoodie/ (50 obj) <-- Hudi metadata (timeline, schema, indexes)
│ ├── .......trimmed
└── year=2024/month=4/
├── day=1/
│ ├── .hoodie_partition_metadata (96 B) <-- Hudi partition marker
│ ├── 7d187e9a.....20261011152509633.parquet (426.3 KB) <-- base Parquet file
│ └── 7d187e9a.....20261011152403779.parquet (426.4 KB) <-- base Parquet file
├── day=2/
│ ├── .hoodie_partition_metadata (96 B) <-- Hudi partition marker
│ └── e583fe17.....20261011152403779.parquet (426.4 KB) <-- base Parquet file
└── day=3/
├── .hoodie_partition_metadata (96 B) <-- Hudi partition marker
├── eedc1b38.....20261011152509633.parquet (426.3 KB) <-- base Parquet file
├── eedc1b38.....20261011152539102.parquet (426.2 KB) <-- base Parquet file
└── eedc1b38.....20261011152403779.parquet (426.4 KB) <-- base Parquet file
note: year=2024/month=4/day=1/ has 2 base files -> multiple file slices (stale versions)
note: year=2024/month=4/day=3/ has 3 base files -> multiple file slices (stale versions)
SUMMARY: 6 base · 0 log · 53 meta · 59 files · 2.8 MB
.hoodie/: present metadata/ (Iceberg): none
Run the CLEAN operation specifying to keep only the latest file slices:
We can see the Hudi and Iceberg tables reflect the same content:
Code:
print("Source: Hudi COW")
spark.sql(f"SELECT event_id, user_id, event_type, event_timestamp, page_url FROM {db_name}.{hudi_events_cow_table} ORDER BY event_id").show(truncate=False)
print("Target: Iceberg (in-place)")
spark.sql(f"SELECT event_id, user_id, event_type, event_timestamp, page_url FROM glue_iceberg.{db_name}.{iceberg_cow_inplace} ORDER BY event_id").show(truncate=False)
Trigger COMPACTION scheduling on the MoR table with the delta-commit and age thresholds set to their minimum, so any file slice with pending log files is included in the plan and merged back into its base Parquet file.
Execute the previously scheduled compaction plan to merge the pending log files into their base Parquet files. The REQUESTED instant produced by the schedule step transitions to COMPLETED, and the table is left with base Parquet files only.
Refresh the Hudi table to invalidate Spark’s cached metadata and file listings, so subsequent queries re-read the post-compaction state from the catalog and storage instead of returning stale pre-compaction results.
print("Source: Hudi MOR")
spark.sql(f"SELECT event_id, user_id, event_type, event_timestamp, page_url FROM {db_name}.{hudi_events_mor_table} ORDER BY event_id").show(truncate=False)
print("Target: Iceberg (in-place)")
spark.sql(f"SELECT event_id, user_id, event_type, event_timestamp, page_url FROM glue_iceberg.{db_name}.{iceberg_mor_inplace} ORDER BY event_id").show(truncate=False)
list_table_files(iceberg_mor_inplace, "MOR Iceberg --- AFTER add_files (note metadata/ folder)", verbose=True)
Output:
s3://demoblogiceberg-bdb5001/hudi_to_iceberg_blog/events_iceberg_mor_inplace/ [MOR Iceberg — AFTER add_files (note metadata/ folder)]
└── metadata/ (5 obj) <-- Iceberg metadata layer (metadata.json, manifest lists, manifests)
├── 00000.....metadata.json (1.3 KB) <-- Iceberg table metadata (schema, snapshots)
├── 00001.....metadata.json (2.0 KB) <-- Iceberg table metadata (schema, snapshots)
├── 00002.....metadata.json (3.0 KB) <-- Iceberg table metadata (schema, snapshots)
├── snap-5097.....avro (4.4 KB) <-- Iceberg manifest list (snapshot -> manifests)
└── stage-254...-manifest.....avro (6.7 KB) <-- Iceberg manifest (lists data files)
note: Iceberg metadata/ present but no local data/ folder
-> in-place migration: data files remain registered in place at the source (Hudi) location; no data copied
SUMMARY: 0 base · 0 log · 5 meta · 5 files · 17.4 KB
.hoodie/: none metadata/ (Iceberg): present
Option 2: Migrate Hudi tables to Iceberg with the Apache XTable sync tool
Apache XTable (Incubating) is an open-source interoperability layer that translates metadata between Apache Hudi, Apache Iceberg, and Delta Lake without copying data. Its sync utility supports both one-time conversion and ongoing incremental synchronization, enabling parallel access to source and target formats during migration. Because it ships as a self-contained Java process with no managed-service dependency, you can run it anywhere a JVM is available: a developer laptop for one-off conversions, an Amazon Elastic Container Service (Amazon ECS) or Amazon Elastic Kubernetes Service (Amazon EKS) container, or an AWS Lambda function, triggered on a schedule through Amazon EventBridge or on an event such as a new Hudi commit.
XTable’s sync utility does two things:
First run – performs the initial in-place migration of a Hudi table to Iceberg.
Subsequent runs – keep the Iceberg metadata in sync with the source table as it continues to receive writes.
Compile xtable-utilities following the instructions in the Apache XTable GitHub repository and copy xtable-utilities/target/xtable-utilities_2.12-0.5.0-SNAPSHOT-bundled.jar into the current working directory.
Migrate MoR to Iceberg
Note: When running the XTable sync tool on a MoR table, the utility only reads the base Parquet files and doesn’t process the delta log files. As a result, the generated Iceberg metadata reflects only the Hudi read-optimized view, meaning any recent updates or deletes stored in delta logs will be missing. To avoid data loss, always run compaction on the MoR table before executing the sync tool (for example, similar run_compaction commands as for the add_files example). Unlike add_files, however, there is no need to run CLEAN beforehand: XTable doesn’t scan the table location file by file, but builds the Iceberg manifests from Hudi’s own metadata, so it already knows which Parquet files belong to the current file slices and ignores superseded versions automatically.
Configure Apache XTables Configuration files.
Create the datasetConfig.yaml file containing indications about the dataset(s) to convert with the following content:
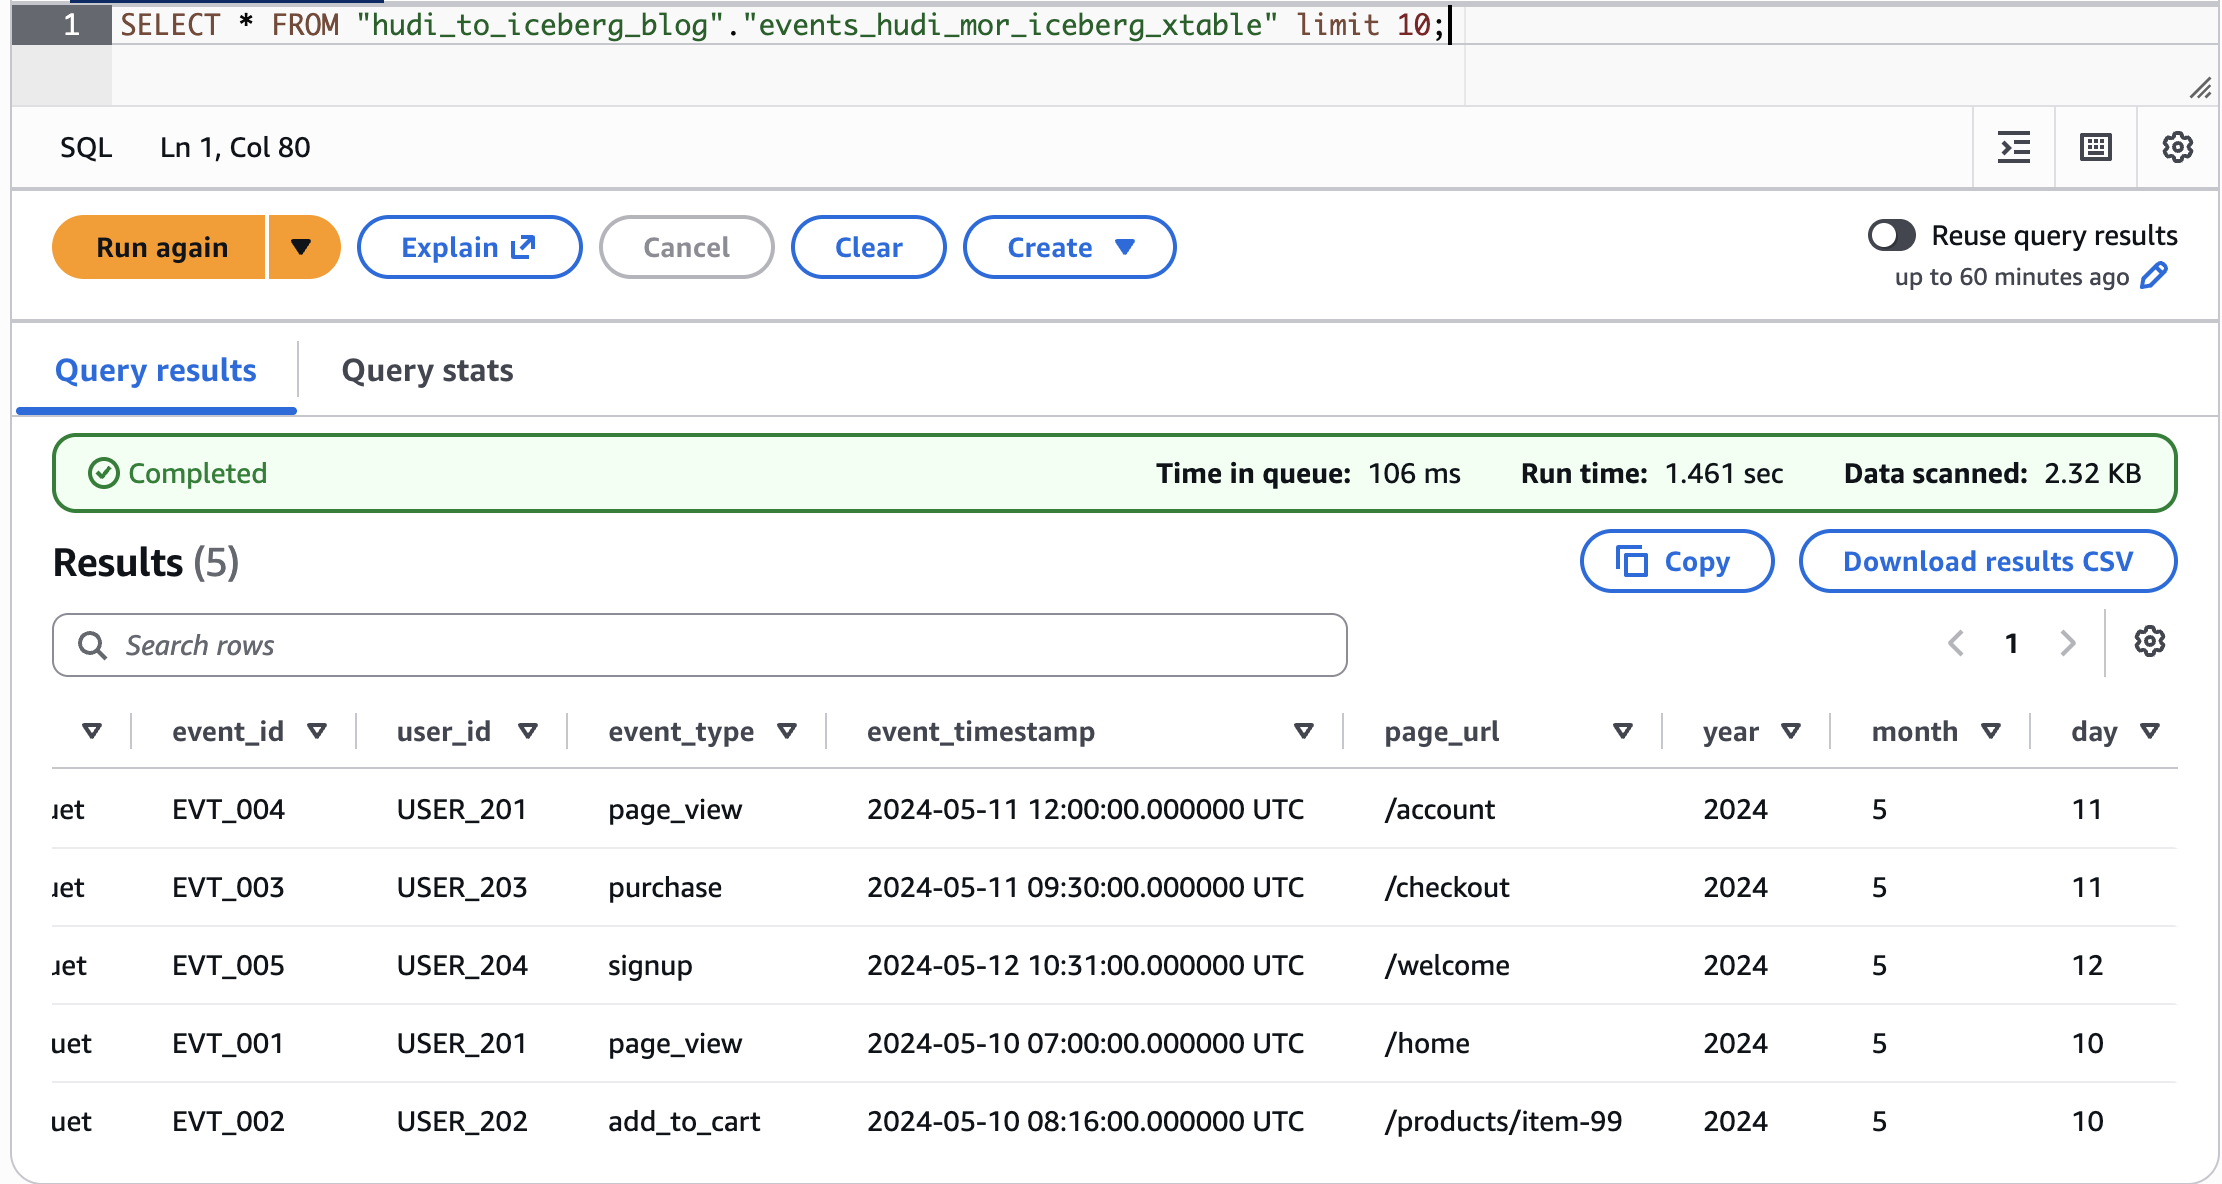
Figure 2: Validating the Apache XTable conversion by querying the migrated Iceberg table in Amazon Athena
Note: If you keep ingesting into the source Hudi table and want to keep the Iceberg table in sync, re-run the same conversion command. XTable automatically detects the previous execution and runs in incremental mode.
Migrate CoW to Iceberg
For the CoW table, update the datasetConfig.yaml with the CoW table path and name.
The glueDataCatalog.yaml, conversion command, and verification steps remain the same as described in the MOR example.
Migrate Hudi tables to Iceberg with full table migration
Full table migration (also called shadow migration) reads all data from Hudi and writes it into a brand-new Iceberg table. This approach:
Allows schema and partition evolution (for example, switching to Iceberg hidden partitioning).
Produces a clean Iceberg table with no Hudi metadata dependencies.
Requires additional storage (data is copied)
Two options are demonstrated:
Option A: CTAS – a single-statement CREATE TABLE ... AS SELECT.
Option B: CREATE + INSERT – explicit table creation followed by data insertion.
Note: When performing a full table migration, the process is the same regardless of whether your source is a Hudi CoW or MoR table. This is because Spark reads from the Hudi real-time view by default, which reflects the latest table state. For CoW tables, this means reading the current base Parquet files. For MoR tables, the real-time view automatically merges the base Parquet files with any pending delta log files, ensuring all recent inserts, updates, and deletes are captured. As a result, the migrated Iceberg table will contain a complete and up-to-date snapshot of your data, with no additional compaction or cleanup steps required before migration.
We have taken a Hudi CoW table example to demonstrate the migration from Hudi CoW table to Iceberg table.
Prepare the column list for migration
Filter out Hudi internal metadata columns (_hoodie_*) and explicit partition columns to use Iceberg hidden partitioning.
Code:
# Build column list excluding Hudi metadata and explicit partition columns
all_columns_cow = spark.sql(f"SELECT * FROM {db_name}.{hudi_events_cow_table} LIMIT 1").columns
non_hoodie_columns_cow = [col for col in all_columns_cow if not col.startswith("_hoodie")]
partition_cols = ['year', 'month', 'day']
data_columns_cow = [col for col in non_hoodie_columns_cow if col not in partition_cols]
columns_to_select_cow = ", ".join(data_columns_cow)
print(f"Columns for COW migration: {columns_to_select_cow}")
Output:
Columns for COW migration: event_id, user_id, event_type, event_timestamp, page_url
Migrate CoW to Iceberg (full table / shadow migration)
We show two full-migration options: a single-statement CTAS and an explicit CREATE followed by INSERT.
Option A: CTAS (CREATE TABLE AS SELECT)
Single statement that creates the Iceberg table and populates it in one step. Here we also adopt Iceberg hidden partitioning by days(event_timestamp) – no need for explicit year/month/day columns.
Code:
spark.sql(f"""
CREATE TABLE glue_iceberg.{db_name}.{iceberg_cow_full_ctas}
USING ICEBERG
PARTITIONED BY (days(event_timestamp))
LOCATION 's3://{bucket_name}/{db_name}/{iceberg_cow_full_ctas}/'
AS (SELECT {columns_to_select_cow} FROM {db_name}.{hudi_events_cow_table})
""")
Code:
# Verify CTAS migration
print("Iceberg COW (CTAS) - Full Migration")
spark.sql(f"SELECT * FROM glue_iceberg.{db_name}.{iceberg_cow_full_ctas} ORDER BY event_id").show(truncate=False)
Useful when you need more control over the target table schema or want to add table properties before loading data, such as sort order. It is also a good fit for very large source tables, because the load phase is a plain INSERT INTO that you can run partition by partition, giving you control over parallelism, resource usage, and resumability during the migration.
spark.sql(f"""
INSERT INTO glue_iceberg.{db_name}.{iceberg_cow_full_create_insert}
SELECT {columns_to_select_cow}
FROM {db_name}.{hudi_events_cow_table}
""")
Code:
# Verify CREATE + INSERT migration
print("Iceberg COW (CREATE+INSERT) - Full Migration")
spark.sql(f"SELECT * FROM glue_iceberg.{db_name}.{iceberg_cow_full_create_insert} ORDER BY event_id").show(truncate=False)
To avoid incurring future charges and to clean up unused roles and policies, delete the resources you created.
Clean up the S3 Tables tables and namespace (same Spark session configuration as for the S3 Tables section):
spark.sql(f"DROP TABLE IF EXISTS s3tablesbucket.{namespace_name}.{s3tables_cow_full} PURGE")
spark.sql(f"DROP NAMESPACE IF EXISTS s3tablesbucket.{namespace_name}")
Clean up the tables and namespace created in the general S3 bucket (same Spark session configuration as for the S3 General buckets section):
in_place_iceberg = [
    iceberg_cow_inplace,
    iceberg_mor_inplace,
    iceberg_cow_xtable,
    iceberg_mor_xtable,
]
for t in in_place_iceberg:
    spark.sql(f"DROP TABLE IF EXISTS glue_iceberg.{db_name}.{t}")

owned_iceberg = [
    iceberg_cow_full_ctas,
    iceberg_cow_full_create_insert,
    iceberg_mor_full_ctas,
    iceberg_mor_full_create_insert,
]
for t in owned_iceberg:
    spark.sql(f"DROP TABLE IF EXISTS glue_iceberg.{db_name}.{t}")

# --- Hudi tables ---
hudi_tables = [
    hudi_events_cow_table,
    hudi_events_mor_table,
]
for t in hudi_tables:
    spark.sql(f"DROP TABLE IF EXISTS {db_name}.{t}")

spark.sql(f"DROP DATABASE IF EXISTS {db_name} CASCADE")
On the Amazon S3 console, navigate to the database folder and delete it.
In the AWS Glue console, under ETL jobs, select the created notebook and choose Actions, Delete job(s).
In the IAM console, delete the role you created for the notebook.
Conclusion
This post outlined strategies for migrating Apache Hudi tables to Apache Iceberg on Amazon S3 and Amazon S3 Tables, enabling organizations to build a modern transactional data lake. Most of the migrations were performed from AWS Glue 5.1 notebooks with interactive sessions, with the exception of the Apache XTable path, which was executed as a standalone Java process from a local workstation to show that cross-format conversion doesn’t require a managed Spark environment and can run anywhere a JVM is available.
The migration process, whether through an in-place migration, a full table migration, or a combination of both, should be chosen based on a thorough analysis of the data architecture and the integration pipelines that read from and write to the table. Factors to weigh include performance requirements, cost, data freshness needs, and the acceptable downtime window during the cutover. The migration should follow well-defined phases that identify the data integration patterns and use cases in play, so the selected strategy aligns with the specific requirements of each table.
Note: Always run the migration end to end in a non-production environment first and validate the migrated Iceberg table against the source Hudi table before cutting production workloads over. We recommend preparing a validation runbook with queries that compare row counts per partition, aggregate values on key metrics, latest-record checks against the preCombine field, and sample point lookups on primary keys, and running it both immediately after the migration and again after each downstream pipeline is repointed at the Iceberg table. Keep the source Hudi table available until the validation runbook has passed on production traffic.