AWS Database Blog
Category: Amazon DynamoDB
Introducing ExtendDB: An open source DynamoDB-compatible adapter with pluggable storage backends
Today, we are announcing ExtendDB, an open source Amazon DynamoDB-compatible adapter with pluggable storage backends, released under the Apache 2.0 License. ExtendDB implements the DynamoDB wire protocol and ships with PostgreSQL as its first backend, so any AWS SDK, CLI, or tool that works with DynamoDB works with ExtendDB unchanged. In this post, we introduce ExtendDB, walk through getting started, and explain the architecture. This is a v0.1 release for development, testing, and experimentation.
Zero-downtime DynamoDB construct migration: from Table to TableV2 with cdk orphan
In this post, we show you how to use the new cdk orphan command to safely migrate a DynamoDB table from the Table construct to TableV2 with zero downtime. Your data stays intact, streams keep flowing, and your application remains available throughout the process.
Filter, transform, and load your DynamoDB table exports using AWS Glue
In this post, we show how you can load (import) an Amazon DynamoDB full or incremental table export into a second DynamoDB table with precise control over what gets loaded, at what write rate, and with the ability to observe the progress. This technique helps drive large-scale data migrations and synchronizations where you want maximum control.
AWS purpose-built database recovery: A guide to business continuity and disaster recovery strategies
This post addresses recovery challenges in multi-database architectures, focusing on both low-consistency and mission-critical scenarios. We explore practical strategies for implementing resilient recovery mechanisms across Amazon DynamoDB, Amazon Aurora, Amazon Neptune, Amazon OpenSearch Service, and other AWS database services.
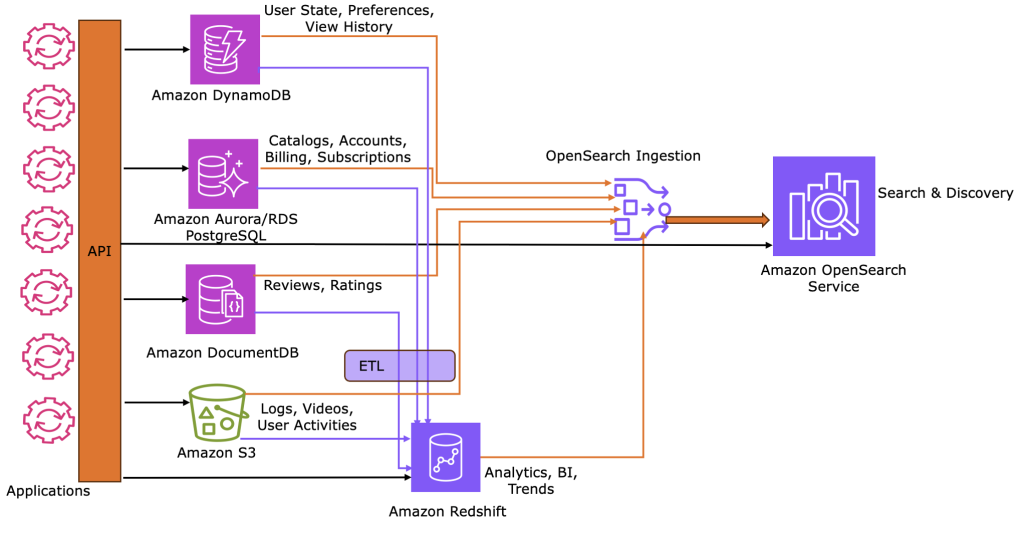
How to build unified JSON search solutions in AWS
Using a movie streaming reference architecture, this post shows how to implement and sync operational, analytical, and search JSON workloads across AWS services. This pattern provides a scalable blueprint for any use case requiring multi-modal JSON data capabilities.
Enabling nested transactions in Amazon DynamoDB using C#
In this post, I introduce a framework for managing atomicity, consistency, isolation, and durability (ACID) compliant transactions in Amazon DynamoDB using C#, featuring support for nested transactions. This capability allows you to implement sophisticated logic with finer control over data consistency and error handling within your .NET applications. With this nested transaction framework, you can isolate issues, allow for partial rollbacks, and build maintainable, modular workflows on top of the built-in transactional capabilities of DynamoDB.
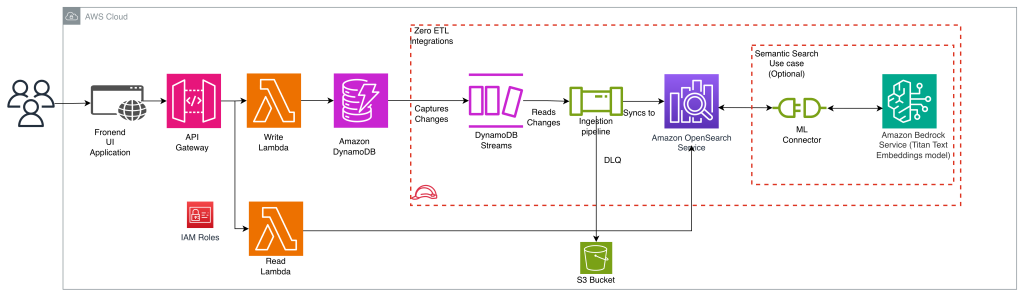
Implementing search on Amazon DynamoDB data using zero-ETL integration with Amazon OpenSearch service
In this post, we show you how to implement search on Amazon DynamoDB data using the zero-ETL integration with Amazon OpenSearch Service. You will learn how to add full-text search, fuzzy matching, and complex search queries to your application without building and maintaining data pipelines.
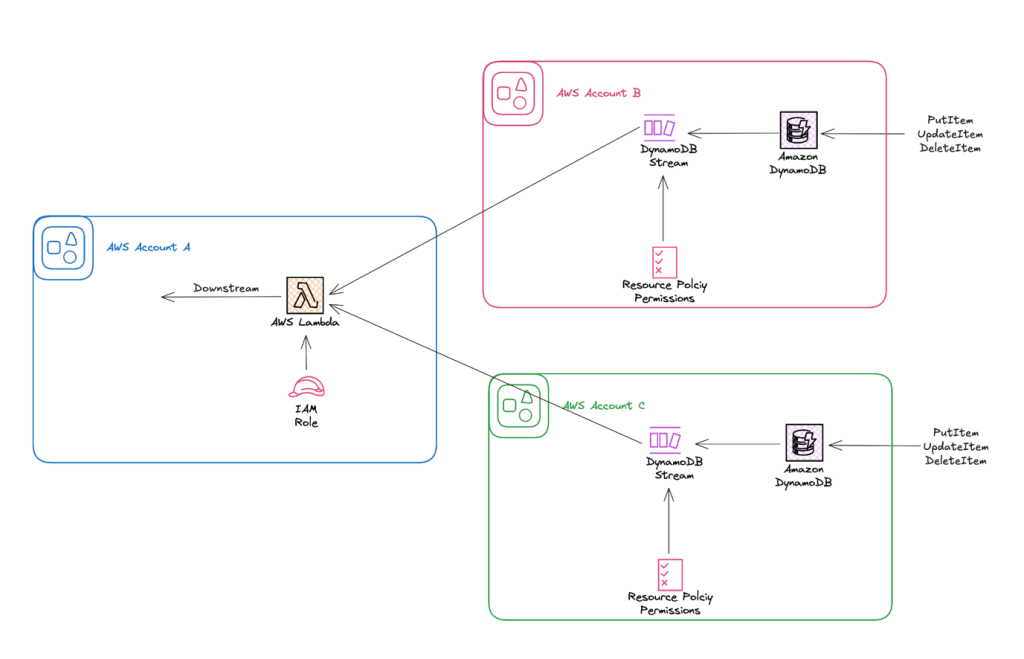
Simplify cross-account stream processing with AWS Lambda and Amazon DynamoDB
In this post, we explore how to use resource-based policies with DynamoDB Streams to enable cross-account Lambda consumption. We focus on a common pattern where application workloads live in isolated accounts, and stream processing happens in a centralized or analytics account.
New in Terraform: Manage global secondary index drift in Amazon DynamoDB
The new aws_dynamodb_global_secondary_index resource treats each GSI as an independent resource with its own lifecycle management. You can use this feature to make capacity adjustments for GSI and tables outside of Terraform. In this post, I demonstrate how to use Terraform’s new aws_dynamodb_global_secondary_index resource to manage GSI drift selectively. I walk you through the limitations of current approaches and guide you through implementing the solution.
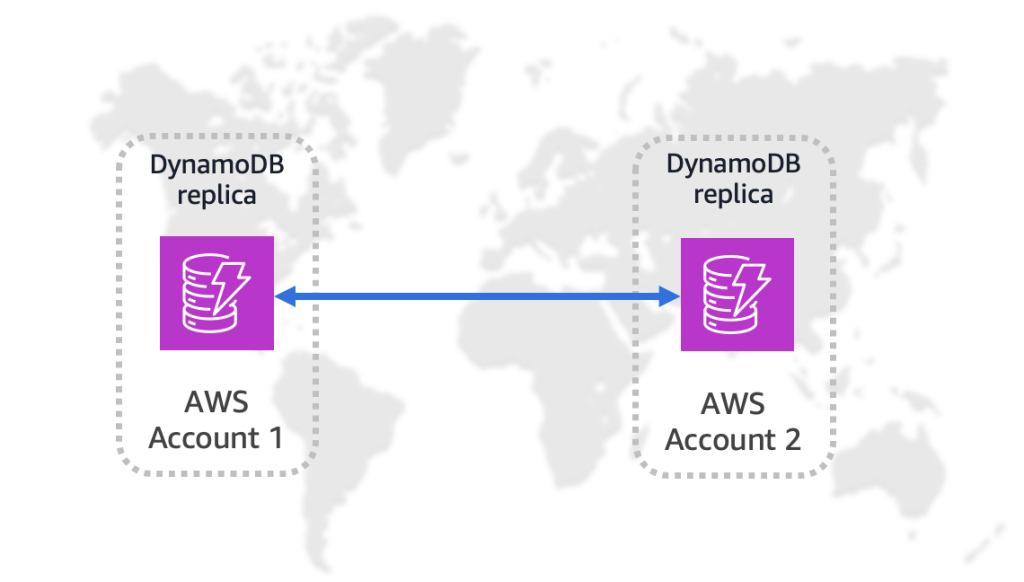
Amazon DynamoDB global tables now support replication across AWS accounts
Today, we’re announcing multi-account global tables for Amazon DynamoDB, which let you replicate DynamoDB table data across multiple AWS accounts and AWS Regions. This feature adds account-level isolation to global tables, so you can replicate DynamoDB table data across multiple AWS accounts and Regions for stronger isolation and resiliency. In this post, we show you how to create and configure a multi-account global table, and introduce use cases highlighting the value of using this feature.