AWS Storage Blog
Running diskless Apache Kafka with Amazon S3 Files
Apache Kafka usually stores its logs on local disk, which only works until the disk fills up. Local capacity is finite, which forces teams to constantly offload older log segments to long-term storage like Amazon Simple Storage Service (Amazon S3) and maintain custom tooling to move, track, and reclaim that data. This adds operational overhead unrelated to core streaming itself. With Amazon S3 Files, you mount an S3 file system backed by your Amazon S3 bucket and point Kafka’s log directories to it. Kafka writes to the S3 file system instead of to a local disk, so there is no volume to size, no manual offload, and no custom tooling to reclaim space. Active segments are served from the file system’s high-performance storage at low latency, and all your data stays in your S3 bucket, where you get the scalability, durability, and cost-effectiveness of S3. Kafka keeps the full file system semantics it expects, so no configuration changes are needed.
S3 Files is a shared file system that connects AWS compute services directly with data in Amazon S3. It provides fast, direct access to Amazon S3 data as files with full file system semantics and low-latency performance, without data leaving Amazon S3. That means file-based applications can access and work with Amazon S3 data as a file system. Kafka is a distributed event streaming solution that developers use to build real-time data pipelines and streaming applications. It continuously ingests, stores, and processes data in sequence, so multiple consuming applications can independently read the same stream as it arrives.
This post shows how to run diskless Kafka on S3 Files. It demonstrates a multi-Region architecture with cross-Region replication and shares the performance benchmarks observed during the test.
Solution benefits
This architecture improves storage resiliency while simplifying operations, minimizes downtime and recovery time by decoupling compute from storage, and provides file system compatibility using S3 Files. It offers the following key benefits:
- Increased durability and scalability – Storage scales independently of compute without the need for volume provisioning, storage capacity planning, and data snapshots. Amazon S3 persists the data with 99.999999999% durability, regardless of instance lifecycle.
- Decoupled compute and storage lifecycles – S3 Files decouples storage from compute by persisting data to an S3 bucket independently of the instance, so metadata survives a node crash or node replacement without restoration.
- Full file system semantics support – S3 Files provides the same file system semantics Kafka expects from a local disk. This means S3 Files supports file append, rename, and file locking through NFS natively, so migrating from local disks to S3 Files requires no changes to Kafka configuration or deployment.
Solution overview
The following diagram shows the architecture used to test Kafka performance using S3 Files as storage. The setup spans two AWS Regions: a producer Region (us-west-1) and a consumer Region (us-east-1). Each Region runs a three-broker Kafka cluster spread across three Availability Zones (one broker per Availability Zone), forming a KRaft quorum of three. Each Region is connected to its own S3 file system backed by a dedicated Regional S3 bucket, and the two Regions are connected privately with inter-Region Virtual Private Cloud (VPC) peering.
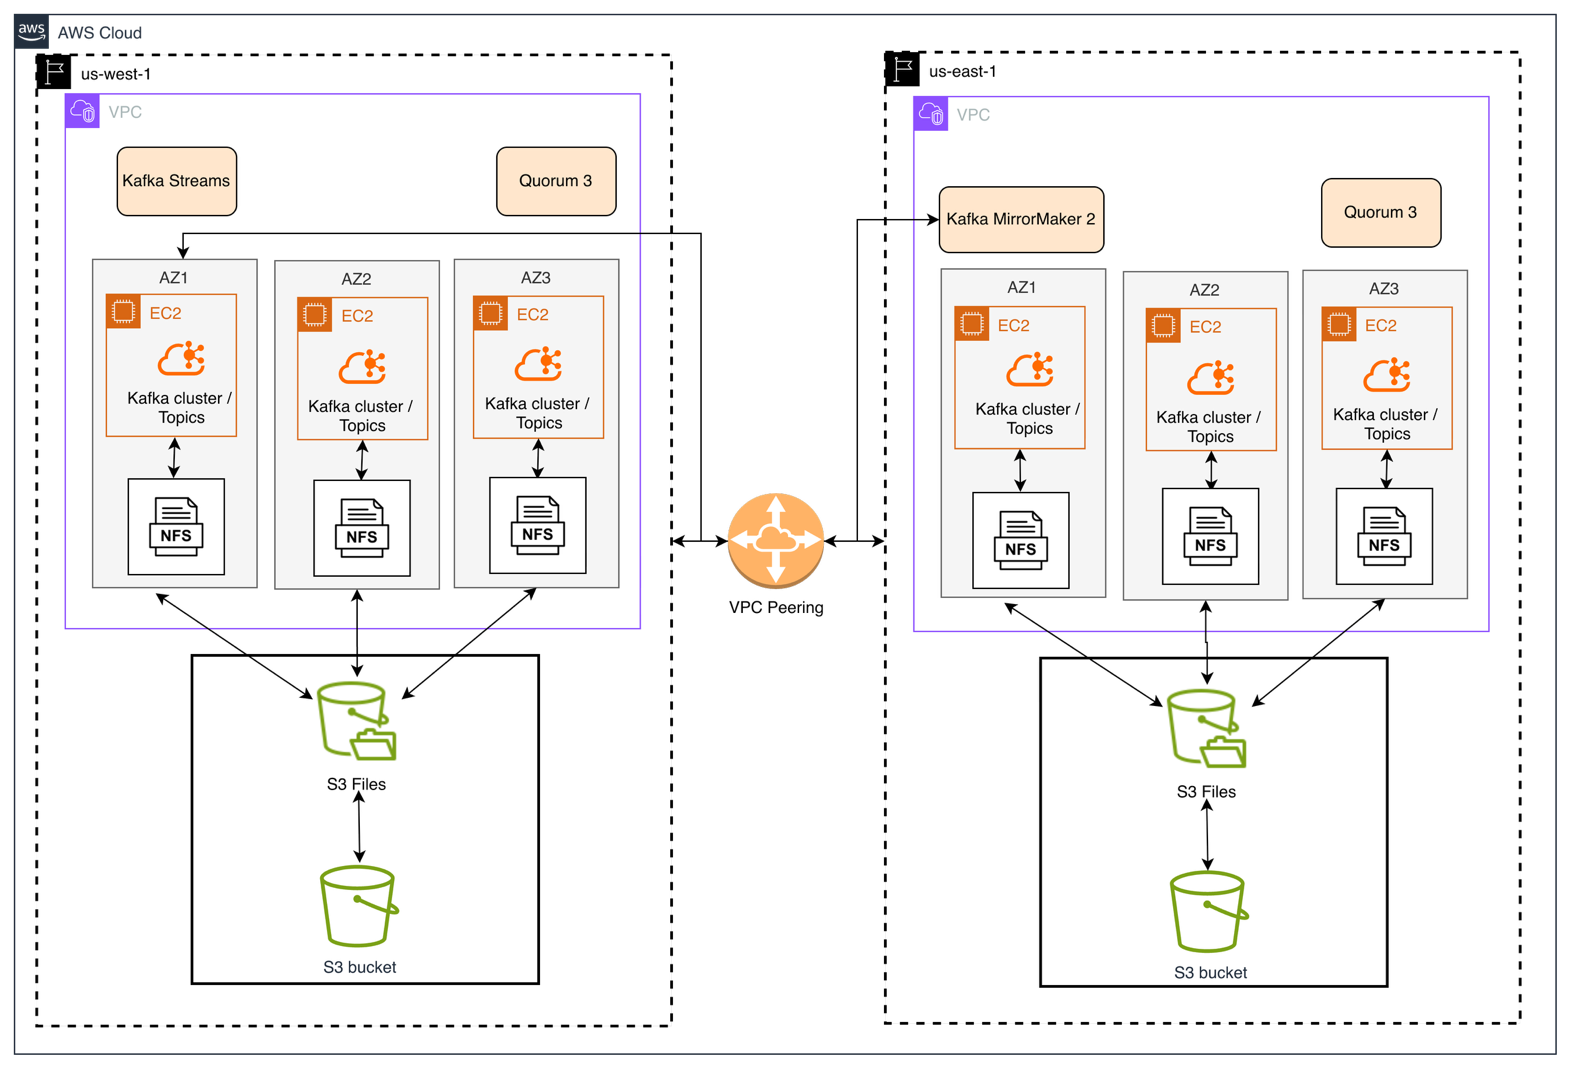
Figure 1: High-level architecture of multi-Region diskless Kafka with S3 Files
Setup details
In each Region, we deployed a three-node Kafka cluster (open-source Apache Kafka 3.7, KRaft mode) on Amazon Elastic Compute Cloud (Amazon EC2), with one broker per Availability Zone. Every broker runs as a combined broker and KRaft controller, forming a controller quorum of three that tolerates the loss of a single Availability Zone. All three brokers mount the same Regional S3 file system (backed by a single Regional S3 bucket) over NFS v4.2 through their Availability Zone-local mount target. Topics use a replication factor of three with min.insync.replicas=2. Because the shared file system already persists data durably in Amazon S3, this replication is for leader and compute availability and zonal failover, not additional storage durability.
The producer Region (us-west-1) also runs a Kafka Streams processor that enriches messages, plus the producer API and dashboard. The consumer Region (us-east-1) runs a MirrorMaker 2 instance for cross-Region replication and a consumer service that reads the replicated topics. A single inter-Region VPC peering connection links the two Regions, providing low-latency connectivity for a two-Region topology. AWS also offers AWS Transit Gateway, AWS PrivateLink, and AWS Site-to-Site VPN for larger or multi-Region topologies.
Production considerations
This architecture uses three brokers per Region across three Availability Zones to demonstrate a production-grade quorum and zonal failover. Kafka handles replication between these brokers natively, and each broker mounts the same Regional S3 file system through its Availability Zone local mount target. When a broker crashes or its Availability Zone becomes unavailable, a replacement instance in a healthy Availability Zone remounts the same file system, and Kafka’s built-in replication protocol fills in missed offsets directly from the current leader among the surviving brokers. Because the KRaft quorum is three, the cluster keeps its controller majority (two of three) through a single Availability Zone failure, so it continues to accept writes without manual intervention.
Write and read paths
There are two paths that describe how the solution sends and receives messages, a write path and a read path. The following diagrams illustrate the write and read paths when Kafka runs on S3 Files.
- Write path – When a producer sends a message, the Kafka broker appends it to the active segment file on the S3 file system. The write goes to the S3 file system and not directly to the S3 bucket, delivering low-latency acknowledgement (
acks=all) back to the producer. The broker continues appending messages to the active segment until Kafka’s segment rolling configuration gets triggered based on either time elapsed or log file size. After the segment rolls, the file becomes immutable, and after 60 seconds of write inactivity the S3 file system exports it to the underlying S3 bucket as a single, complete object.
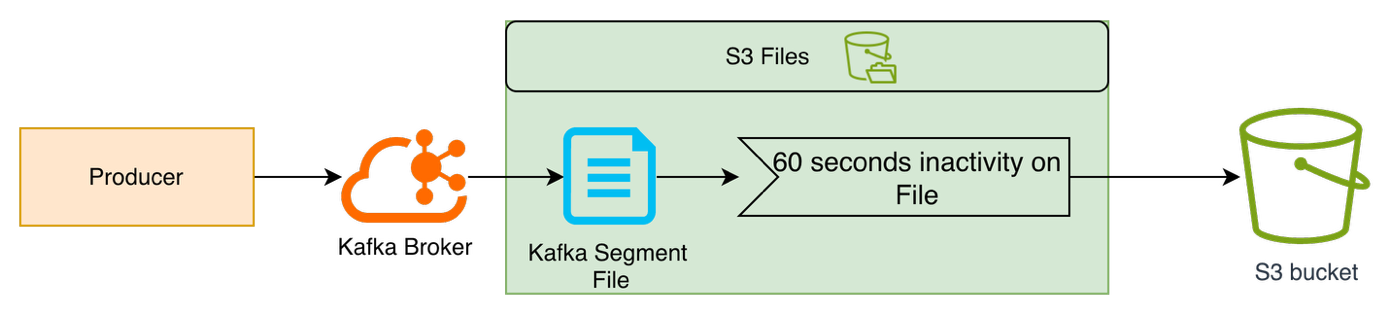
Figure 2: Write path
- Read path – When a consumer reads messages, the Kafka broker reads from the S3 file system. If the requested data is in the S3 Files cache (recent or active data), reads are served at millisecond latency. If the data has been evicted from S3 Files (older segments), S3 Files transparently fetches it from the S3 bucket back into cache. Kafka is unaware of this caching layer and reads and writes to the S3 file system.
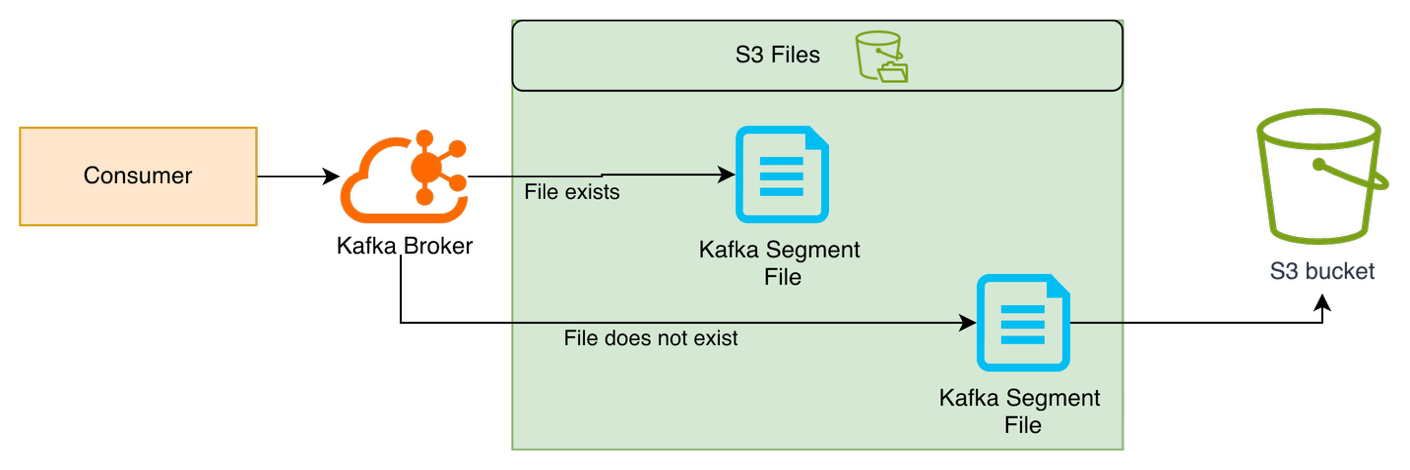
Figure 3: Read path
- KRaft metadata – Kafka’s cluster coordination metadata, broker membership, partition assignments, and consumer offsets are stored on S3 file system. KRaft checkpoints rely on atomic
rename()operations, which S3 Files supports natively.
The following steps show how to set up S3 Files as diskless storage for Kafka in one Region.
Prerequisites
Before setting up Kafka on S3 Files, make sure you have the following prerequisites:
- An AWS account with permissions to create and manage VPC, Amazon EC2, Amazon S3, AWS Identity and Access Management (IAM), and S3 Files resources.
- A VPC with a private subnet in the Region where Kafka will be deployed.
- Kafka (3.7, KRaft mode) already installed on your EC2 instance (for example, under
/opt/kafka), with Java installed. Installing Kafka is a prerequisite and is not covered in this post. - Cross-Region connectivity already configured if you are replicating across Regions, for example, inter-Region VPC peering between the producer and consumer Region VPCs. Setting up VPC peering is a prerequisite.
- An IAM role for the S3 Files service with permissions to read/write to the S3 bucket. S3 Files assumes this role (trust principal elasticfilesystem.amazonaws.com) to export closed segments to the bucket.
- Grant least-privilege bucket access: s3:ListBucket and s3:ListBucketVersions on the bucket, and s3:GetObject*, s3:PutObject*, s3:DeleteObject*, and s3:AbortMultipartUpload on its objects, scoped to the single bucket. For details, see How S3 Files works with IAM.
- An IAM instance profile for the EC2 instance with permissions to mount the S3 file system.
- An EC2 key pair for SSH access to the instance.
- AWS Command Line Interface (AWS CLI) v2 with the
s3filessubcommand installed.
Create S3 bucket
In this step, create an S3 bucket that will serve as the durable storage backend for Kafka data. The segment files and metadata that S3 Files exports will land in this bucket. Enable versioning so intermediate segment exports are preserved as non-current versions, which can later be cleaned up with lifecycle rules:
An S3 bucket now exists in the target Region with versioning enabled.
Create S3 file system
In this step, create an S3 file system linked to the bucket. This is the file system that Kafka reads and writes to. Make sure to specify an IAM role that grants S3 Files permission to read and write objects in the bucket:
Note the fileSystemId returned and wait for the file system to become available:
An S3 file system is now linked to the S3 bucket.
Mount S3 Files on EC2 instance
In this step, launch an EC2 instance running Amazon Linux 2023 and mount the S3 file system. After it’s mounted, the file system appears as a local directory that Kafka can read and write to. Make sure to configure auto-remount, so the file system survives instance reboots:
The S3 file system is now mounted at /mnt/kafka and persists across reboots.
Configure Kafka to use S3 Files
In this step, create the directory structure Kafka needs on the S3 Files mount and configure server.properties to point all storage at the mount. This configures Kafka’s commit logs, KRaft metadata, and consumer offsets to reside on S3 Files:
Use the following key configuration in server.properties:
Kafka is now configured to store data on the S3 file system with no local disk dependencies.
Format storage and start Kafka
In this step, generate a KRaft cluster ID, format the storage directories on S3 Files, and start the Kafka broker:
Kafka is now running on Amazon EC2 and using S3 Files. Commit logs, KRaft metadata, and consumer offsets are stored in S3 Files.
Performance
In this section, we discuss the performance observed during our test. The performance outcomes might differ in your use case depending on networking configuration and message size. This test was performed with 200 B and 10 KB message size.
Replication performance
During testing, the observed end-to-end latency for replication using MirrorMaker 2 from the producer in us-west-1 to the consumer in us-east-1 was as follows:
| Message size | Replication latency to us-east-1 |
| ~200 B | ~155 ms |
| ~10 KB | ~165 ms |
Kafka broker acknowledgement performance (includes write to S3 Files)
When a producer sends a message, the broker acknowledgement time is measured as the full round-trip performance. This duration covers the message traveling from the producer to the Kafka broker, the broker appending the message to the active segment file on the S3 file system, and the broker sending an acknowledgement back to the producer confirming the write. This metric captures the S3 Files write performance in addition to the network round trip between producer and broker.
During S3 Files write tests with acks=all, the tests showed the following broker acknowledgement performance.
| Message size | Average broker acknowledgement time |
| ~200 B | ~10 ms |
| ~10 KB | ~15 ms |
Kafka segment rolling and S3 Lifecycle Management
S3 Files automatically exports file system changes to the S3 bucket after 60 seconds of write inactivity. This happens independently of Kafka configurations. Understanding the S3 Files export trigger (write inactivity) is key to choosing the segment rolling strategy.
Kafka segment roll options control when an active partition file is closed and a new one is opened. This is configured at the broker or topic level based on size, time, or time-jitter. Kafka rolls the segment based on the configuration, making the segment inactive, and allowing S3 Files to export the file to the S3 bucket.
When a producer writes continuously (consistent throughput without long pauses), the segment stays active until it rolls on time or size, so S3 Files exports a single, clean version. When writes are intermittent (bursts of activity followed by silence), a burst followed by more than 60 seconds of inactivity before the segment rolls results in multiple versions being exported to Amazon S3. This is how intermittent writing accumulates multiple versions of the same segment in Amazon S3. The final version always contains the full segment data, which makes the older versions unnecessary for Kafka’s operation. Consider making an S3 Lifecycle rule to automatically expire non-current object versions after 1 day to manage storage costs. This retains the latest complete version of each segment while giving sufficient time for ongoing operations to complete and save on cost. For details on configuring a lifecycle, see Managing the lifecycle of objects.
Clean up
To avoid ongoing charges, clean up the resources created in this walkthrough:
- Stop the Kafka broker, then unmount the S3 file system and remove the mount point directory.
- Delete the S3 file system from the Amazon S3 Files console and wait for its status to show as deleted.
- Delete the S3 bucket (only if you don’t need the data). This permanently deletes all Kafka segment files and metadata.
- Terminate the EC2 instance from the Amazon EC2 console.
- Clean up networking resources created specifically for this test, such as the S3 Files VPC endpoint and any security group rules you added.
- Verify cleanup by confirming the file system is deleted, the bucket is empty or deleted, and the instance shows as terminated.
Conclusion
Running Kafka on S3 Files decouples storage from compute. When a broker crashes, the replacement instance mounts the same file system and resumes from the last valid offset, with no snapshot restores or manual intervention. Aligning your segment-rolling strategy with the S3 Files export trigger keeps this resilient and operationally straightforward at scale. To get started, see Working with Amazon S3 Files.