Amazon Kinesis Data Streams features
Why Kinesis Data Streams?
Amazon Kinesis Data Streams is a serverless data streaming service that ingests data once, fans it out to multiple consumer applications for real-time processing, and delivers the same data to data lakes for later analysis. Kinesis Data Streams can continuously capture gigabytes of data per second from hundreds of thousands of sources, such as website clickstreams, database event streams, financial transactions, social media feeds, IT logs, and location-tracking events. The collected data is available in milliseconds. Consumer applications read the stream for use cases such as dashboards, anomaly detection, and dynamic pricing, or receive the same records through queues for use cases such as microservices integration, order fulfillment, per-event inference, data enrichment, and search indexing.
Key Capabilities
Fully serverless
There are no servers to manage with Amazon Kinesis Data Streams. On demand modes automatically scale capacity when workload traffic increases, with no manual shard management required. Get started with a few clicks from the AWS Management Console.
Highly available and durable
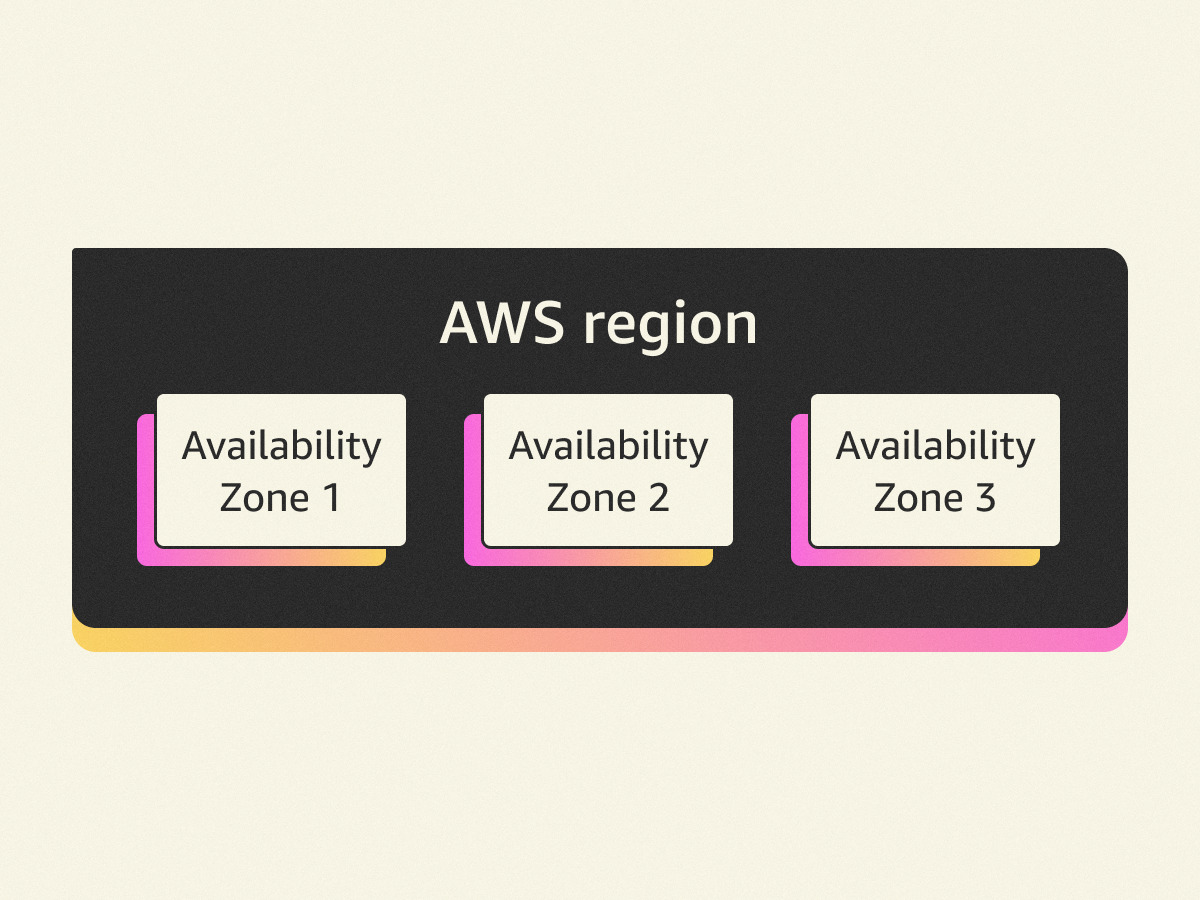
Streaming data is synchronously replicated across three Availability Zones in an AWS Region, with retention up to 365 days to provide multiple layers of data loss protection.
Low latency delivery
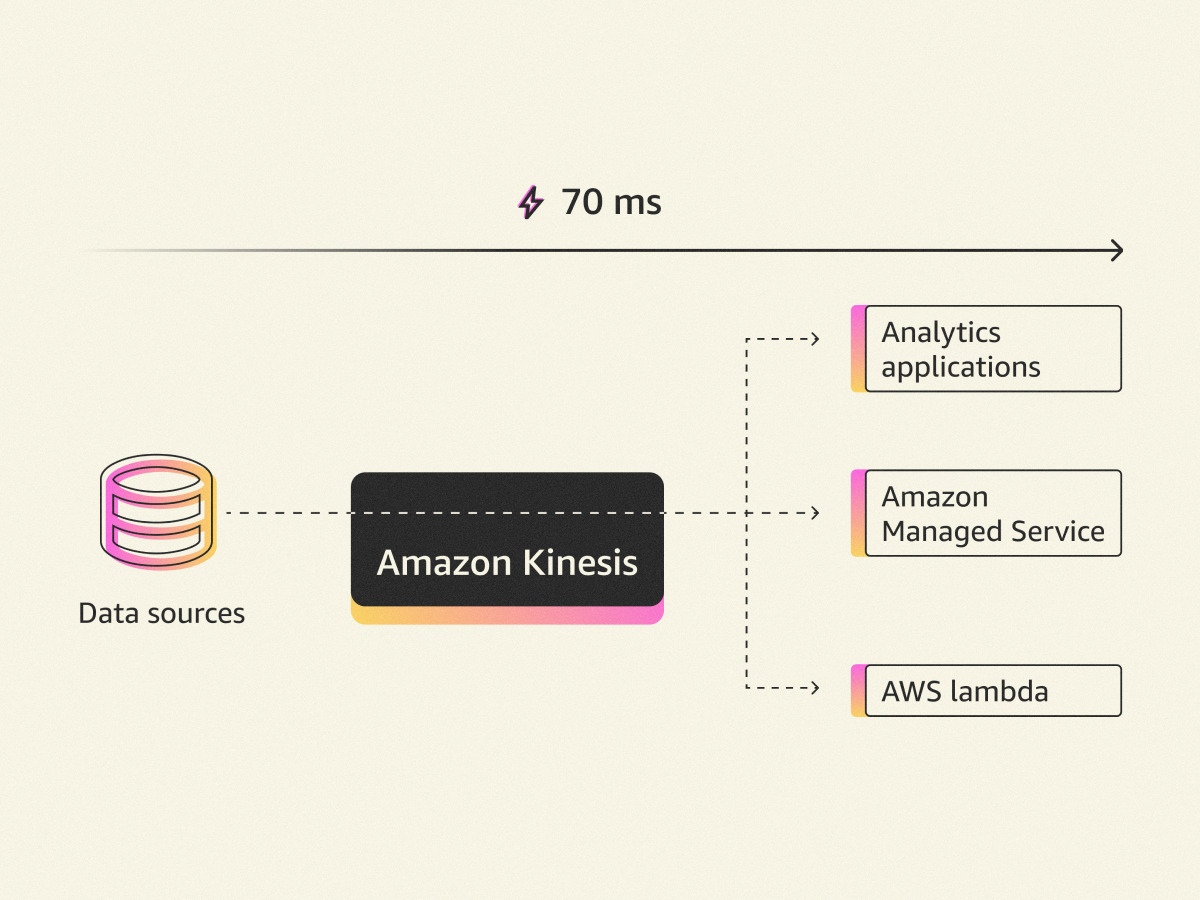
Make your streaming data available to multiple real time analytics applications, to Amazon Managed Service for Apache Flink, or to AWS Lambda within 70 milliseconds of being collected.
Flexible fan-out
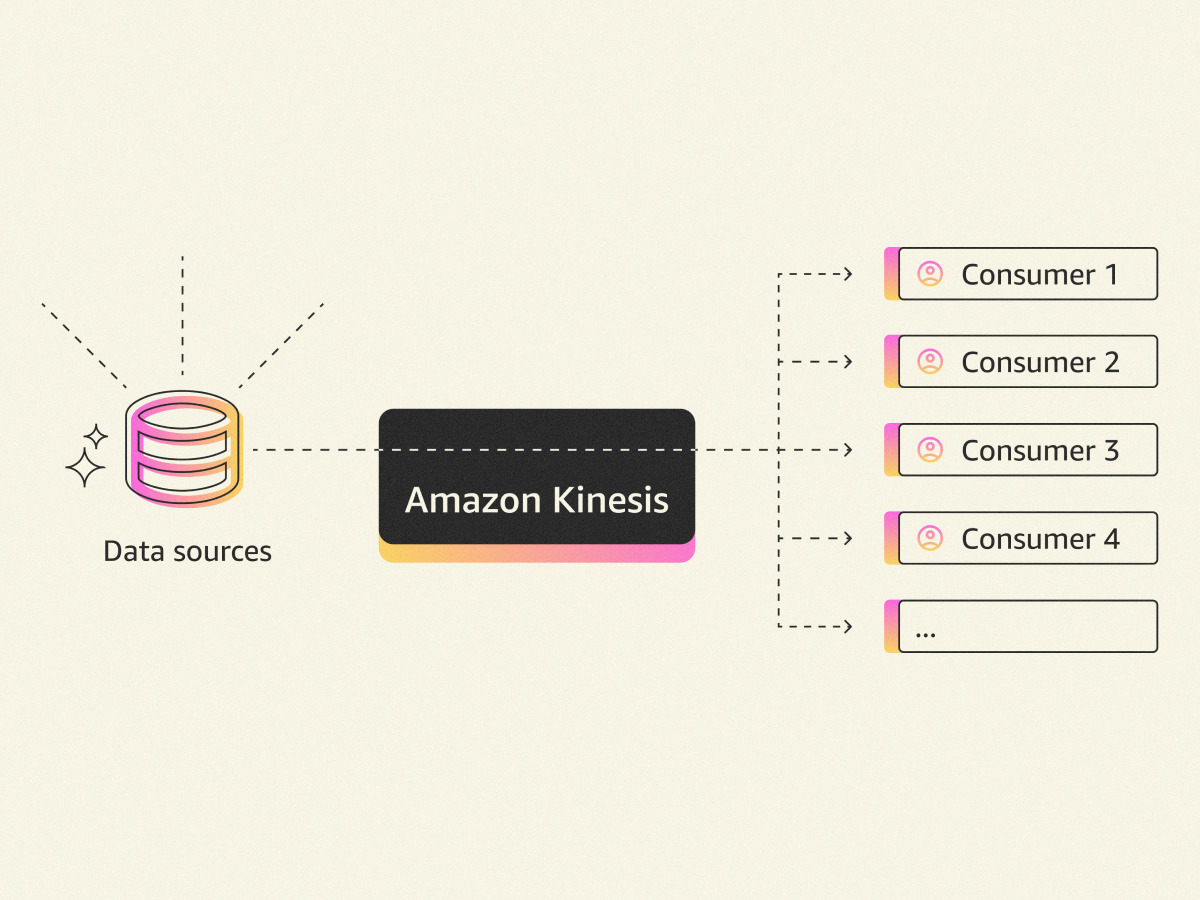
Multiple applications can consume the same Kinesis data stream at the same time. An enhanced fan-out stream consumer reads with dedicated throughput. A queue consumer receives records independently with acknowledgment, automatic redelivery, and built-in dead-letter handling, without managing shards, leases, or checkpoints. Enhanced fan-out consumers and queue consumers share the stream's registered consumer limit: 20 on On-demand Standard and 50 on On-demand Advantage.
Cost optimized capacity modes
On-demand Advantage offers discounted pricing, warm throughput, and up to 50 registered consumers on each stream when you commit to a 25 MB/s baseline across all On-demand streams in an AWS Region.
Built-in security
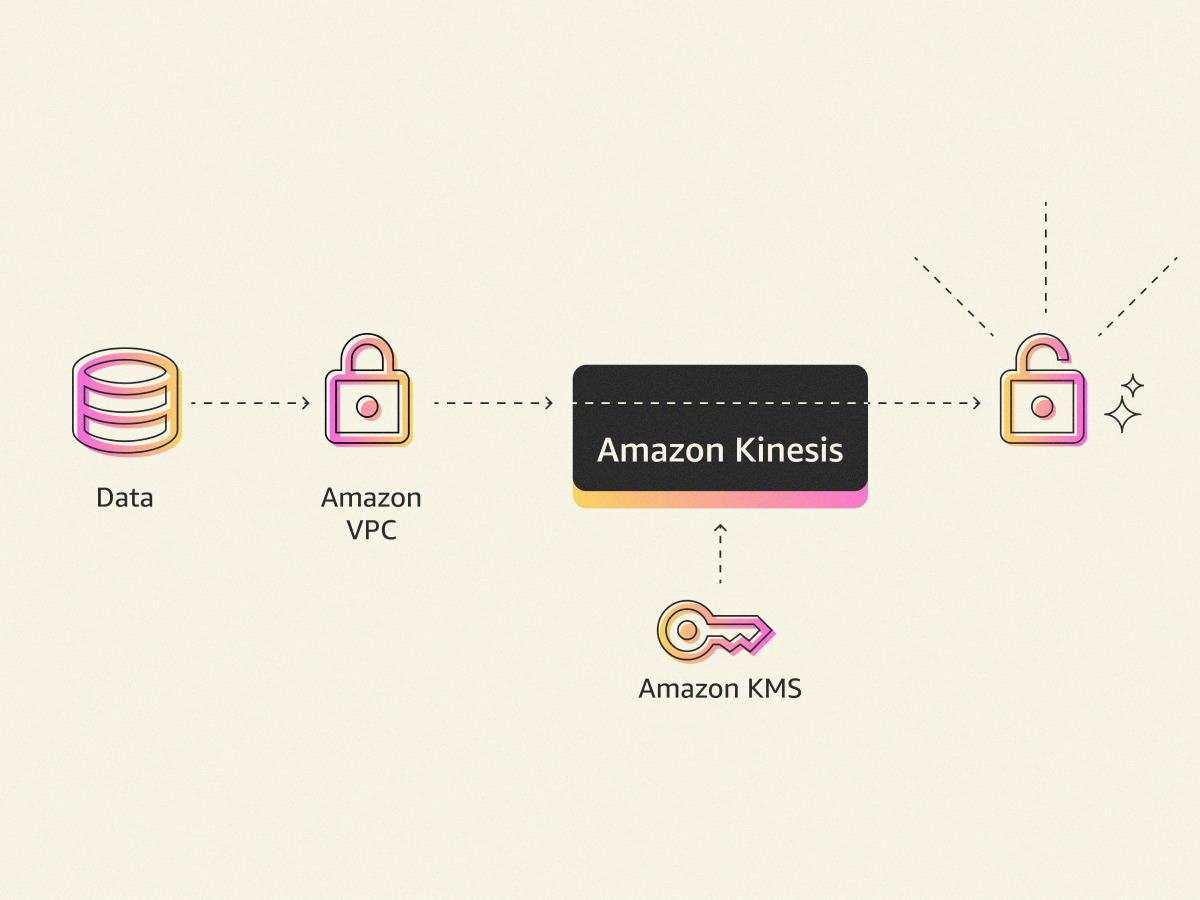
Encrypt sensitive data at rest using server side encryption and AWS Key Management Service (KMS) keys. Securely access your data via Amazon Virtual Private Cloud (VPC) to meet regulatory and compliance requirements.
Broad AWS integrations
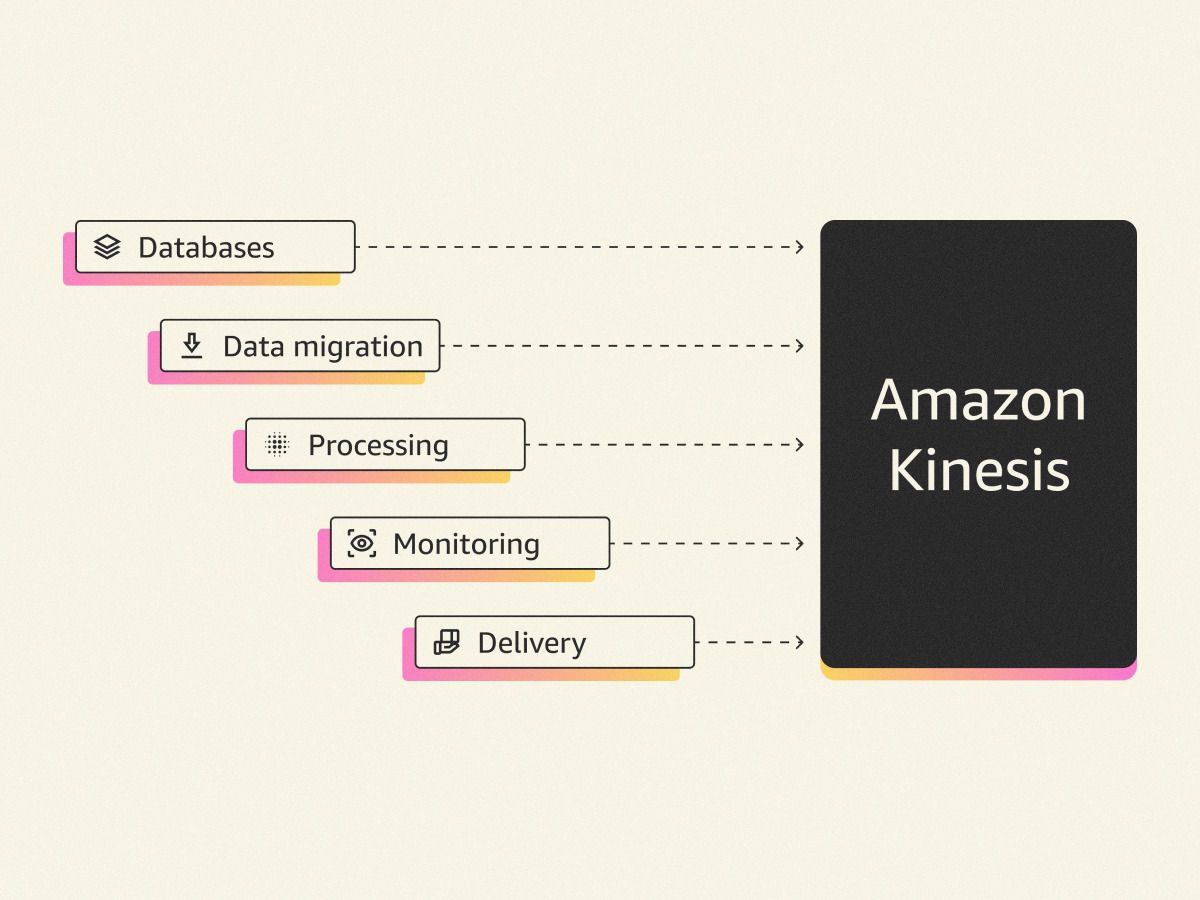
Connect with Amazon DynamoDB, Amazon Aurora, AWS Database Migration Service, Amazon CloudWatch, AWS Lambda, Amazon Managed Service for Apache Flink, and Amazon Kinesis Data Firehose to build complete applications quickly.
Queues
Receive records through a queue, powered by Amazon SQS, to process them independently.
A queue delivers records from an On-demand stream to a queue consumer and tracks the delivery state of each record. The queue consumer receives records, processes them, and acknowledges the ones it has processed. A record that isn't acknowledged before its visibility timeout expires is delivered again. Built-in dead-letter handling sets aside records that keep failing, so you can inspect and restore them. Use queue-level CloudWatch metrics to monitor received, acknowledged, visible, in-flight, and dead-letter records. Because the queue tracks progress, the queue consumer doesn't manage shards, leases, or checkpoints, and you can add consumer instances to process more records in parallel as your load changes. Your producers don't change, and your stream consumers keep reading the same records.
Data Delivery
Delivery to streaming tables in Iceberg format
Continuously materialize streaming data as queryable Apache Iceberg tables on Amazon S3 Tables with no ETL pipeline required.
Delivery to streaming tables continuously materializes stream records as Apache Iceberg tables on Amazon S3 Tables. Built in intelligent inline compaction eliminates small file proliferation and keeps query performance predictable without sacrificing data freshness. Query or transform data with any engine, including Apache Spark, Trino, Apache Flink, or Amazon Athena, for real time analytics directly on your streaming data.
Delivery to Amazon S3
Deliver streaming data in source format to S3 buckets for backup, archival, and downstream data processing.
Deliver streaming records directly to general purpose Amazon S3 buckets in the original source format. Use this capability for long term data retention, compliance archival, replay and reprocessing workflows, or as a staging layer for downstream batch processing pipelines. Combined with delivery to streaming tables, you can build a complete lakehouse architecture with real time queryable tables for analytics alongside full fidelity raw backup in S3.
Capacity Modes
On Demand Standard
Zero capacity planning. Stream data at any scale with pay per use pricing.
On Demand Standard removes the need to provision or manage throughput. Capacity scales automatically as workload traffic increases, with no manual shard management required. Data is synchronously replicated across three Availability Zones and available to consumers within 70 milliseconds. Ideal for unpredictable or spiky workloads where you want to pay only for the data you ingest and retrieve.
On Demand Advantage
Commit to a small baseline throughput for discounted pricing, unlimited fan out, and warm throughput across all streams.
On Demand Advantage provides automated capacity management with cost optimized pricing when you commit to a 25 MB/s data throughput baseline across all on demand streams in a region. Unlock unlimited enhanced fan out consumers, warm throughput for burst ready performance, and simplified billing based on total data throughput. If you ingest over 10 MB/s across all streams, fan out to more than two consumers, or use more than 50 streams, On Demand Advantage delivers the most cost effective experience.