AWS Storage Blog
How MIXI built natural language search over billions of photos with Amazon S3 Vectors
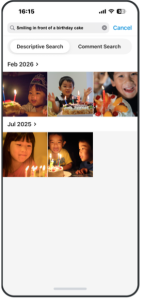
MIXI, Inc. operates FamilyAlbum, a service that approximately 30 million registered users rely on to share photos and videos with the people closest to them. As of January 2026, families have shared more than 20 billion photos and videos through the service. They can rediscover a specific precious moment — a baby’s first swim, an unforgettable birthday, a candid smile — and relive the emotion behind the memory. But delivering that experience at scale can be challenging. Helping 30 million users find one specific moment among more than 20 billion photos and videos means understanding what each image actually shows, then returning the right memory in an instant, at a cost that stays sustainable as the library grows by millions of items every day.
To solve for this, MIXI built descriptive search. Families type everyday words such as “baby,” “smile,” or “birthday cake,” and descriptive search surfaces the matching photos and videos. Tag and comment search can only match the text someone entered; descriptive search reads the image itself, so a memory stays discoverable even if no one ever labeled it. To deliver this solution across billions of media items, MIXI needed a vector search foundation: a place to store and query embeddings affordably, at scale, and fast enough to stay interactive.
MIXI built descriptive search on Amazon S3 Vectors, adopting it as their workload grew and cost efficiency at scale became the priority. With S3 Vectors, MIXI sees roughly 75% lower vector storage and management costs, consistent sub-1-second search, and simpler operations. In this post, we walk through that journey: how MIXI designed descriptive search, the framework it used to evaluate its options, and why S3 Vectors proved the right fit for this workload.
How descriptive photo search works
The idea is simple: represent both the image dataset and the user text queries as vectors (embeddings) in the same space, then find the images whose vectors are most similar to the text query. At upload time, every media item is converted into a vector in advance; at search time, the text query is converted into a vector, the system computes cosine similarity against the stored vectors, and the most similar images are returned.
MIXI embeds both images and text with clip-japanese-base, a Japanese-trained CLIP model published by LY Corporation. It delivers higher accuracy for Japanese queries than multilingual models such as SigLIP2, and its compact 512-dimensional output and lightweight architecture keep embedding costs down.

Figure 1: How natural language photo search works with CLIP embeddings and cosine similarity
Embeddings alone are not enough, though. You still need infrastructure to persist hundreds of millions of vectors and retrieve the most similar ones quickly — computing similarity against every item on every query is not viable at this scale. That is the role of a vector store, and choosing one is where MIXI’s journey began.
The three points that shaped the decision
Given the nature of MIXI’s FamilyAlbum service, three points became the yardstick against which every option was measured, both at launch and later:
- Large-scale vectors. The platform must hold hundreds of millions to billions of vectors while continuously ingesting vectors for new media.
- Sustainable cost. At this scale, standing up always-on provisioned infrastructure can get expensive fast. For a feature meant to grow to more users, overseas markets, and recommendation use cases, the cost structure must stay viable years out.
- Response time. Descriptive search is an online feature: users type a query and wait. The acceptance criterion was a response within 3 seconds.
When descriptive search launched, MIXI built its initial vector search implementation on provisioned infrastructure and tuned it aggressively to balance cost and performance, including sharding families across indexes, compressing vectors to shrink the memory footprint, and leaning on Amazon S3 for durability to run leaner. Provisioned infrastructure delivered fast, consistent sub-second search, and the design met FamilyAlbum’s latency and cost criteria through launch and its first period of growth. As MIXI looked ahead to scale to many more users, new markets, and recommendation use cases built on the same vector foundation, the economics of running always-on provisioned infrastructure became the real constraint. Because descriptive search could tolerate subsecond latency, MIXI had room to optimize for cost.
A new option arrives: Amazon S3 Vectors
In December 2025, Amazon S3 Vectors reached general availability and became available in the AWS Tokyo Region at the same time. It is a purpose-built vector store that offers the high durability of Amazon S3 with no shards to manage. Pricing is pay-per-use, search responses land within about 1 second, and it scales to 10,000 indexes per bucket, with up to 2 billion vectors per index. When MIXI re-evaluated these three points against it, S3 Vectors proved a better fit for FamilyAlbum’s descriptive search because the workload needed cost-effective k-NN search at massive scale.
Amazon S3 Vectors matched the shape of this workload. It is serverless, with no shards, nodes, or clusters to design, size, or operate, so MIXI could grow without carrying the operational overhead of a provisioned system. Its pricing is fully usage-based. MIXI pays only for the vectors it stores and the queries it runs, with no always-on instances billed by the hour, which directly answers the cost constraint that had emerged. And it scales to FamilyAlbum’s size natively, supporting up to 10,000 indexes per bucket and 2 billion vectors per index, enough room for billions of media items with no hand-designed sharding scheme to maintain.
Its query and write capabilities fit descriptive search well. S3 Vectors provides k-NN similarity search, which is exactly what descriptive search needs, with any additional logic handled in MIXI’s own application. It stores float32 vectors, and supports up to 1,000 PutVectors requests per second per index, or up to 2,500 vectors per second per index with batch writes, which suits MIXI’s ingest pattern. Descriptive search is simple similarity over billions of vectors, where cost efficiency and scale matter most, and S3 Vectors covers those needs directly.
Adapting the design for S3 Vectors
Index partitioning: MIXI distributes families across a set of indexes by hashing the family_id and using it as a routing key, so each query scans only the single index that holds the target family’s media. This keeps every search narrow and efficient as the number of families grows.

Figure 2: Architecture comparison: before and after adopting S3 Vectors
Batch PUT for cost optimization: To optimize ingest costs, S3 Vectors recommends inserting vectors in large batches. MIXI followed this guidance by batching its writes, accumulating vectors server-side and writing them together in a single request.

Figure 3: Batch PUT optimization to absorb S3 Vectors 128 KB minimum request charge for PutVectors
Running the migration: With batches of around 500 vectors, MIXI migrated billions of vectors for only a few tens of thousands of yen — an affordable one-time cost.
Production results
Using S3 Vectors delivered the following benefits for FamilyAlbum’s descriptive search:
- Cost — roughly 75% reduction in database management fees (at a constant request volume), plus lower operational and monitoring cost, shifting from fixed-plus-usage cost to fully usage-based.
- Performance — search responses within 1 second.
- Operations — freed from shard design, with simpler failure handling and consistent performance under variable load.
MIXI also handled two challenges beyond the vector store, both of which apply to any such foundation. The first is safety: as a service handling children’s photos, it detects inappropriate queries on the API server and returns zero results. The second is accuracy, which MIXI verified through internal testing and manual checks and controls with a cosine-similarity threshold.
Conclusion and next steps
Helping families reach memories they never labeled across billions of photos and videos is a hard data problem. For FamilyAlbum, Amazon S3 Vectors gave MIXI a foundation that scales affordably, stays fast, and is simpler to operate. New services create new options, and periodically re-evaluating a working architecture is a healthy practice.
To explore Amazon S3 Vectors for your own workload, visit the documentation page.