AWS Compute Blog
Category: Best Practices

Supporting AWS Graviton2 and x86 instance types in the same Auto Scaling group
This post is written by Tyler Lynch, Sr. Solutions Architect – EdTech, and Praneeth Tekula, Technical Account Manager. As customers seek performance improvements and to cost optimize their workloads, they are evaluating and adopting AWS Graviton2 based instances. This post provides instructions on how to configure your Amazon EC2 Auto Scaling group (ASG) to use […]
Operating Lambda: Building a solid security foundation – Part 2
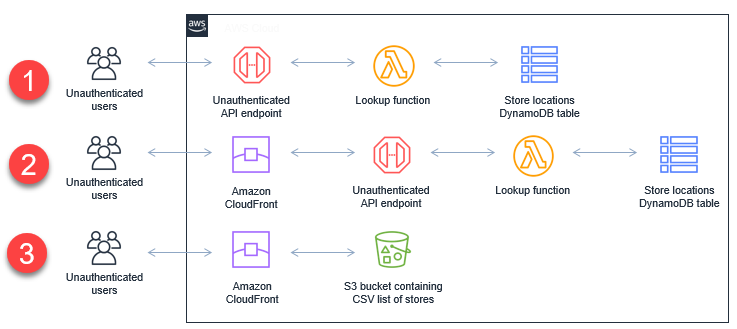
In this blog post, I explain how to secure workloads with public endpoints and the different authentication and authorization options available. I also show different approaches to exposing APIs publicly.

Operating Lambda: Building a solid security foundation – Part 1
This post explains the Lambda execution environment and how the service protects customer data. It covers important steps you should take to prevent data leakage between invocations and provides additional security resources to review.

Operating Lambda: Application design – Part 3
This post discusses choosing and managing runtimes, the effect on performance, and how you can use multiple runtimes within a single serverless application. It explains the networking model and whether a Lambda function must have access to a customer VPC or can run with the default VPC configuration. It also compares the different invocation modes for Lambda functions.
Operating Lambda: Application design – Scaling and concurrency: Part 2
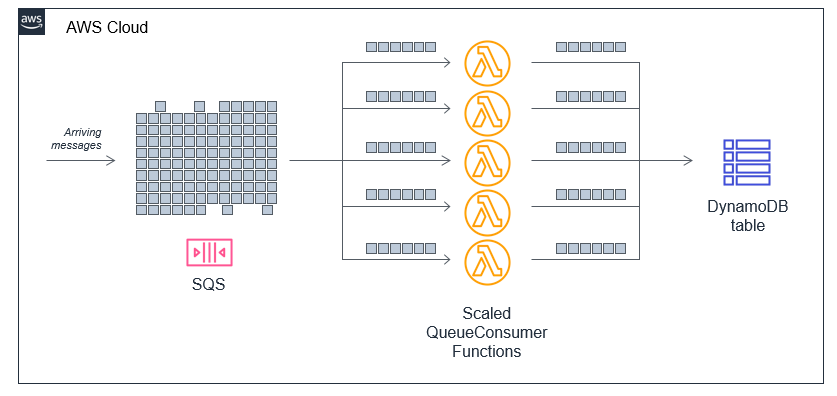
This post explains scaling and concurrency in Lambda and the different behaviors of on-demand and Provisioned Concurrency. It also shows how to use service integrations and asynchronous patterns in Lambda-based applications. Finally, I discuss how reserved concurrency works and how to use it in your application design.
Operating Lambda: Application design and Service Quotas – Part 1
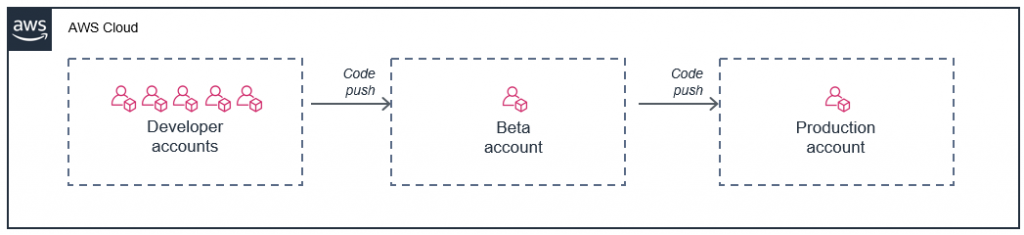
Lambda works with other AWS services to process and manage requests and data. This post explains how to understand and manage Service Quotas, when to request increases, and architecting with quotas in mind. It also explains how to control traffic for downstream server-based resources.

Running cost optimized Spark workloads on Kubernetes using EC2 Spot Instances
This post is written by Kinnar Sen, Senior Solutions Architect, EC2 Spot Apache Spark is an open-source, distributed processing system used for big data workloads. It provides API operations to perform multiple tasks such as streaming, extract transform load (ETL), query, machine learning (ML), and graph processing. Spark supports four different types of cluster managers (Spark standalone, Apache […]

Operating Lambda: Anti-patterns in event-driven architectures – Part 3
This post discusses anti-pattern in event-driven architectures using Lambda. I show some of the issues when using monolithic Lambda functions or using custom code to orchestrate workflows. I explain how to avoid recursive architectures that cause loops and why you should avoid functions calling functions.

How to monitor Windows and Linux servers and get internal performance metrics
This post was written by Dean Suzuki, Solution Architect Manager. Customers who run Windows or Linux instances on AWS frequently ask, “How do I know if my disks are almost full?” or “How do I know if my application is using all the available memory and is paging to disk?” This blog helps answer these […]
Operating Lambda: Design principles in event-driven architectures – Part 2
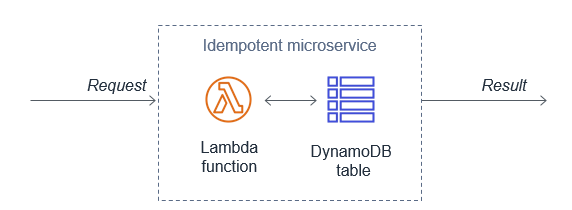
This post discusses the design principles that can help you develop well-architected serverless applications. I explain why using services instead of code can help improve your application’s agility and scalability. I also show how statelessness and function design also contribute to good application architecture.