AWS Architecture Blog
Category: Amazon RDS

How Meshify Built an Insurance-focused IoT Solution on AWS
The ability to analyze your Internet of Things (IoT) data can help you prevent loss, improve safety, boost productivity, and even develop an entirely new business model. This data is even more valuable, with the ever-increasing number of connected devices. Companies use Amazon Web Services (AWS) IoT services to build innovative solutions, including secure edge […]

Modernized Database Queuing using Amazon SQS and AWS Services
This blog post was last reviewed/updated August, 2022. The updated version shown below is based on working backwards from a customer need to ensure data consistency post migration, to a modernized microservice architecture. A queuing system is composed of producers and consumers. A producer enqueues messages (writes messages to a database) and a consumer dequeues […]

Migrating a Database Workflow to Modernized AWS Workflow Services
The relational database is a critical resource in application architecture. Enterprise organizations often use relational database management systems (RDBMS) to provide embedded workflow state management. But this can present problems, such as inefficient use of data storage and compute resources, performance issues, and decreased agility. Add to this the responsibility of managing workflow states through […]

Use a City Planning Analogy to Visualize and Create your Cloud Architecture
If you are new to creating cloud architectures, you might find it a daunting undertaking. However, there is an approach that can help you define a cloud architecture pattern by using a similar construct. In this blog post, I will show you how to envision your cloud architecture using this structured and simplified approach. Such […]

Disaster Recovery with AWS managed services, Part 1: Single Region
This 3-part blog series discusses disaster recovery (DR) strategies that you can implement to ensure your data is safe and that your workload stays available during a disaster. In Part I, we’ll discuss the single AWS Region/multi-Availability Zone (AZ) DR strategy. The strategy outlined in this blog post addresses how to integrate AWS managed services […]

Exploring Data Transfer Costs for AWS Managed Databases
When selecting managed database services in AWS, it’s important to understand how data transfer charges are calculated – whether it’s relational, key-value, document, in-memory, graph, time series, wide column, or ledger. This blog will outline the data transfer charges for several AWS managed database offerings to help you choose the most cost-effective setup for your […]

Offloading SQL for Amazon RDS using the Heimdall Proxy
Getting the maximum scale from your database often requires fine-tuning the application. This can increase time and incur cost – effort that could be used towards other strategic initiatives. The Heimdall Proxy was designed to intelligently manage SQL connections to help you get the most out of your database. In this blog post, we demonstrate […]

Migrate Resources Between AWS Accounts
Have you ever wondered how to move resources between Amazon Web Services (AWS) accounts? You can really view this as a migration of resources. Migrating resources from one AWS account to another may be desired or required due to your business needs. Following are a few scenarios where this may be of benefit: When you […]
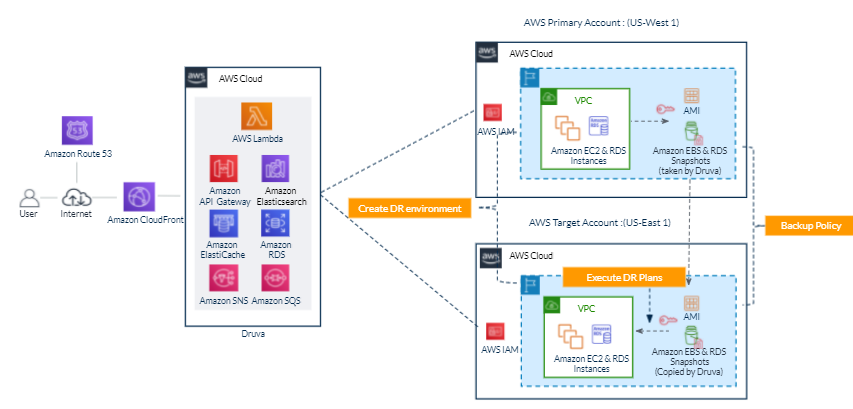
Field Notes: Automate Disaster Recovery for AWS Workloads with Druva
This post was co-written by Akshay Panchmukh, Product Manager, Druva and Girish Chanchlani, Sr Partner Solutions Architect, AWS. The Uptime Institute’s Annual Outage Analysis 2021 report estimated that 40% of outages or service interruptions in businesses cost between $100,000 and $1 million, while about 17% cost more than $1 million. To guard against this, it […]

Middleware-assisted Zero-downtime Live Database Migration to AWS
When trying to figure out how to refactor your applications to leverage AWS Managed Services, you have some decisions to make. You may have decided to move your storage layer to AWS before the computational layer. This may help with using advanced database features, in addition to reducing costs associated with writing and reading data. […]