Artificial Intelligence

Author: Mona Mona
Mixture-of-Experts kernel engineering on Amazon SageMaker AI
AWS engineers share kernel optimizations for fused Mixture-of-Experts (MoE) models on Amazon SageMaker AI: Swap-AB for WGMMA utilization, Triton backend routing for FP8 quantization, and eliminating Triton JIT recompilation. Together they deliver up to 10% higher throughput and up to 9% faster Time to First Token on H200 GPUs.
New agent skill: Amazon SageMaker optimized generative AI inference for your coding agent
Amazon SageMaker optimized generative AI inference introduces the aws-ai-ml skill through the Agent Toolkit for AWS, giving coding agents like Kiro, Claude Code, and Codex deep expertise in inference optimization and benchmarking. Describe what you want, and your agent generates executable SageMaker Python SDK v3 code to benchmark, recommend, and compare deployments.
Right-size generative AI endpoints with concurrency sweeps on Amazon SageMaker AI
Concurrency sweeps help you right-size a generative AI endpoint on Amazon SageMaker AI by systematically benchmarking it at increasing load levels. This post walks through deploying a model, running automated concurrency sweeps with the CreateAIBenchmarkJob API, and using the results to make data-driven capacity decisions about fleet size.
Amazon SageMaker Feature Store introduces UpdateRecord for feature-level writes
Amazon SageMaker Feature Store now supports feature-level writes. With the new UpdateRecord API, you can update one or more feature values in a single call without reading or rewriting the entire record. It is available for both the Standard (Amazon DynamoDB) and In-Memory (Amazon ElastiCache) online store tiers.
Benchmarking small LLM inference on SageMaker AI: G7 vs G5 and G6
Benchmark two 30B Mixture-of-Experts models, Qwen3-Coder-30B and NVIDIA Nemotron-3-Nano-30B, across G5, G6, G6e, and G7 GPU instances on Amazon SageMaker AI. Compare throughput, latency, and cost-per-token, and see how G7’s NVIDIA Blackwell GPUs deliver measurable price-performance gains for real-time LLM inference.
Streaming benchmark and recommendation results to MLflow with Amazon SageMaker AI
In this post, you learn how to use the new MLflow integration with Amazon SageMaker AI optimized inference recommendation jobs and Amazon SageMaker AI benchmark jobs to automatically stream experiment data into a unified tracking interface. This integration streams metrics, parameters, and charts into your serverless Amazon SageMaker MLflow App in real time and you get a unified experiment tracking experience.
Introducing container caching in Amazon SageMaker AI for faster model scaling
Today, we’re excited to announce container image caching for Amazon SageMaker AI inference, the next major advancement in our faster scaling optimization journey. This speeds up end-to-end latency by up to 2x for generative AI models during scale-out events.
Amazon SageMaker AI now supports optimized generative AI inference recommendations
Today, Amazon SageMaker AI supports optimized generative AI inference recommendations. By delivering validated, optimal deployment configurations with performance metrics, Amazon SageMaker AI keeps your model developers focused on building accurate models, not managing infrastructure.
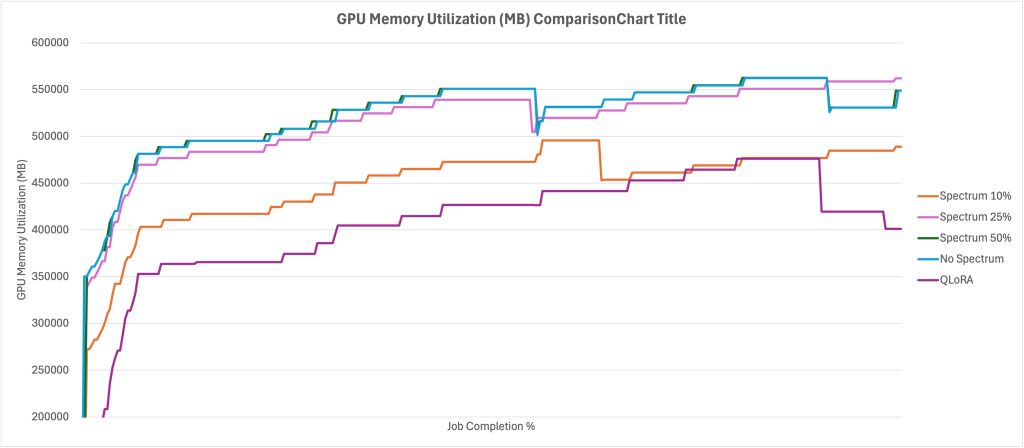
Using Spectrum fine-tuning to improve FM training efficiency on Amazon SageMaker AI
In this post you will learn how to use Spectrum to optimize resource use and shorten training times without sacrificing quality, as well as how to implement Spectrum fine-tuning with Amazon SageMaker AI training jobs. We will also discuss the tradeoff between QLoRA and Spectrum fine-tuning, showing that while QLoRA is more resource efficient, Spectrum results in higher performance overall.
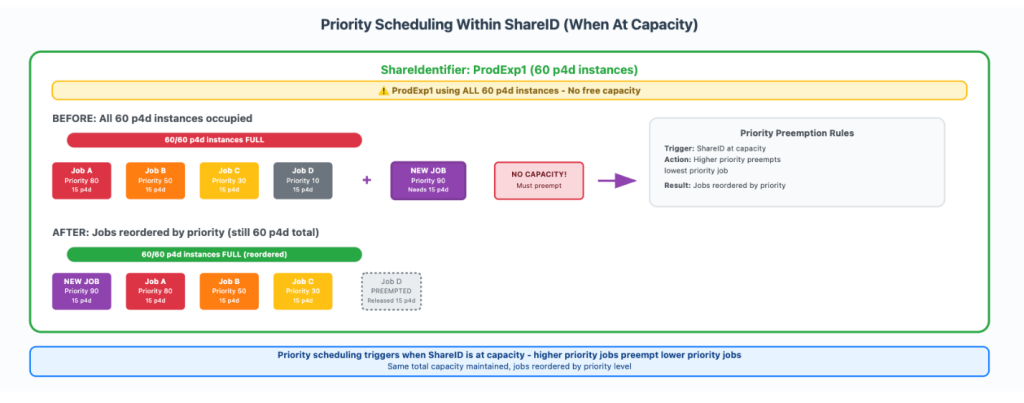
How Amazon Search increased ML training twofold using AWS Batch for Amazon SageMaker Training jobs
In this post, we show you how Amazon Search optimized GPU instance utilization by leveraging AWS Batch for SageMaker Training jobs. This managed solution enabled us to orchestrate machine learning (ML) training workloads on GPU-accelerated instance families like P5, P4, and others. We will also provide a step-by-step walkthrough of the use case implementation.