AWS Architecture Blog
Category: Database
How CSIRO built scalable, cost-optimized genomic variant querying on AWS
Learn how researchers at CSIRO, Australia’s national science agency, built Serverless Beacon (sBeacon), a scalable serverless solution for securely querying genomic variant data on AWS. sBeacon implements the GA4GH Beacon standard using Amazon S3, AWS Lambda, Amazon DynamoDB, and Amazon Athena to support production-scale clinical and research applications.
Building resilient real-time streaming workers with Amazon DynamoDB leases
Real-time streaming workers that hold hundreds of persistent WebSocket connections lose data when a worker fails. Learn how to build a WebSocket fleet management system on Amazon ECS and AWS Fargate that uses Amazon DynamoDB conditional writes as a distributed lease to track ownership, fail over automatically, and deploy with low downtime.
Build a unified AI agent architecture with DynamoDB and Bedrock
With native vector search in Amazon DynamoDB, you can store vector embeddings alongside your operational data in a single table. This post shows how to build a unified AI agent architecture where an Amazon Bedrock agent uses one DynamoDB table for both structured lookups and semantic search, with a DynamoDB Streams pipeline that keeps embeddings in sync.
Consistency is the new latency: AI at the data layer
As AI agents move from chatbots to taking action, their reliability depends on the consistency of the data layer beneath them. This post examines how replication lag poisons an agent’s context and shows how to match Amazon Aurora, Amazon DynamoDB, and Amazon Keyspaces replication models to each task’s consistency requirements.
Eclipse Dataspace Components on AWS: Cost optimization strategies
When you deploy Eclipse Dataspace Components (EDC) connectors on AWS, one of the first challenges you face is predicting and controlling the cost of the required infrastructure. Without clear benchmarks, it is difficult to make informed decisions about workload sizing, environment configuration, and long-term investment. Part 1 of this 3-part blog series covered the fundamentals […]
Eclipse Dataspace Components on AWS: Architecture patterns in production
Running Eclipse Dataspace Components (EDC) connectors in production on AWS requires deliberate architecture decisions around isolation, managed services, and security layering. In Part 1 of this series, we covered the fundamentals of data space architectures and EDC per the International Data Space Association’s (IDSA) standards. If you are new to EDC, we recommend starting there. […]
Eclipse Dataspace Components on AWS: Data sharing fundamentals
This three-part blog series guides you through implementing Eclipse Dataspace Components (EDC) on AWS, from foundational concept to production deployment. Part 1 establishes the theoretical foundation with IDSA standards, the Dataspace Protocol (DSP), and core EDC architecture. Part 2 provides production-ready AWS deployment patterns using services like Amazon Elastic Container Service (Amazon ECS), Amazon Aurora, […]
Building highly available Oracle databases with Amazon FSx for NetApp ONTAP
This post shows how to build a highly available Oracle database architecture using FSxN shared storage, Auto Scaling groups with dynamic AMI updates, and serverless orchestration to help reduce recovery times with current configurations.
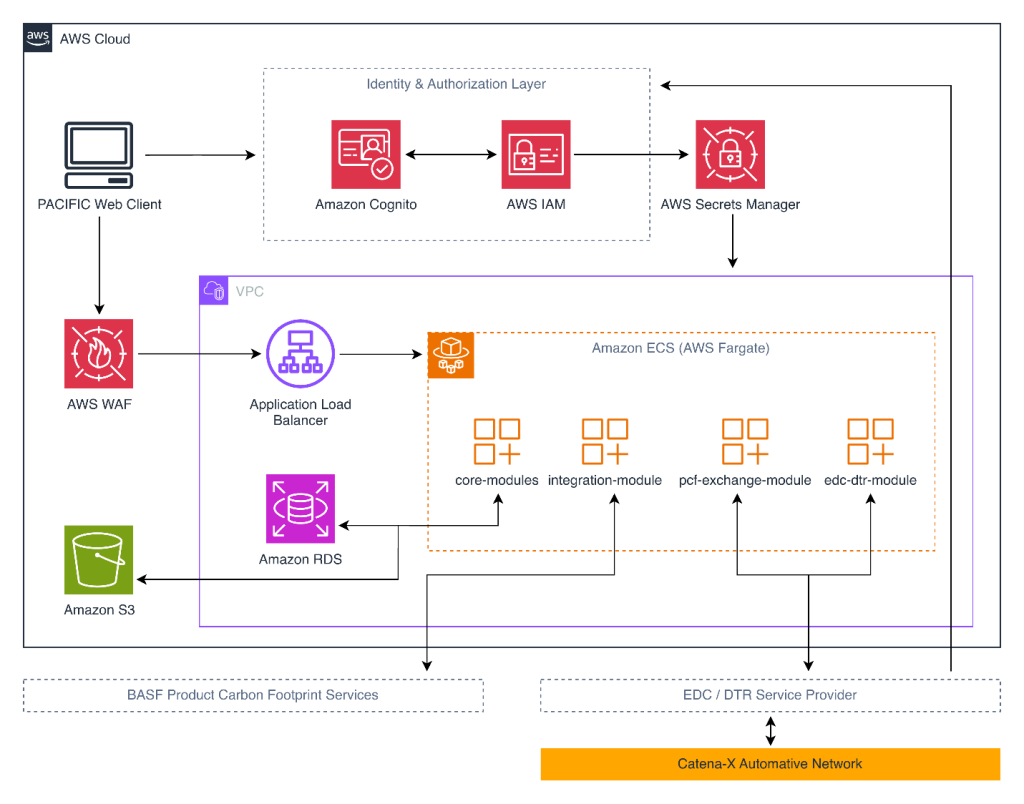
PACIFIC enables multi-tenant, sovereign product carbon footprint exchange on the Catena-X data space using AWS
This post explores how PACIFIC enables multi-tenant, sovereign PCF exchange on the Catena-X data space using Amazon Elastic Container Service (Amazon ECS) on AWS Fargate, Amazon Cognito, and AWS Identity and Access Management (IAM) to deliver measurable environmental impact and competitive advantage in a carbon-conscious marketplace.
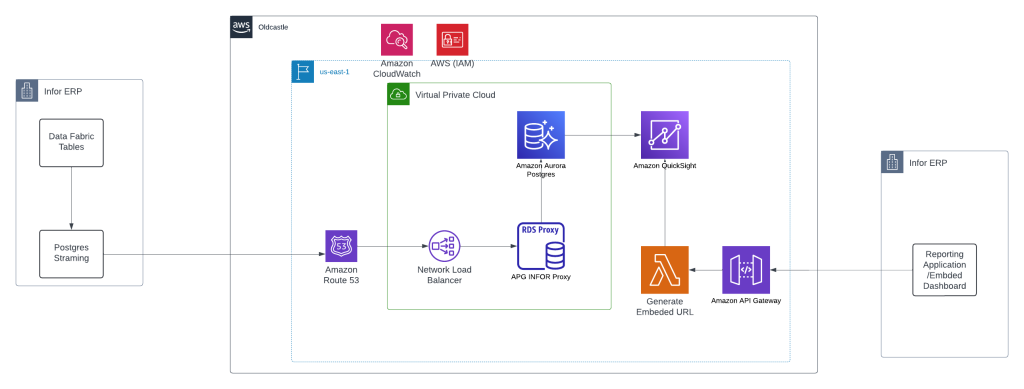
Real-time analytics: Oldcastle integrates Infor with Amazon Aurora and Amazon Quick Sight
This post explores how Oldcastle used AWS services to transform their analytics and AI capabilities by integrating Infor ERP with Amazon Aurora and Amazon Quick Sight. We discuss how they overcame the limitations of traditional cloud ERP reporting to deploy real-time dashboards and build a scalable analytics system. This practical, enterprise-grade approach offers a blueprint that organizations can adapt when extending ERP capabilities with cloud-native analytics and AI.