Artificial Intelligence
Introducing Kimi K3.1 Pro on Amazon Bedrock
Kimi K3.1 Pro Highspeed from Moonshot AI is now available on Amazon Bedrock. Part of Moonshot AI’s new K3.1 series, it’s a post-trained version of Kimi K3 with the same 3T-class open-weight architecture and 1-million-token context window, trained with substantially more post-training compute. According to Moonshot AI, that extra training targets long-horizon agentic work and fewer factual errors. It also improves professional tasks such as financial modeling and office documents, and coding for game engines, 3D scenes, and computer-aided design (CAD) scripts. Kimi K3.1 Pro Highspeed generates output tokens at a higher rate and Moonshot AI reports 2–3 times the speed of Kimi K3.1 Pro.
Kimi K3.1 Pro Highspeed uses the same endpoint, APIs, and features as Kimi K3 on Amazon Bedrock. If you already build with Kimi K3, you can try it by changing the model ID in your existing code.
Kimi K3.1 Pro Highspeed supports tool calling, structured output, configurable reasoning, image input, and streaming. You can adopt Kimi K3.1 Pro Highspeed without changing your security posture. Your data is processed within the AWS data boundary, isn’t shared with Moonshot AI, and isn’t used to train the model. Zero data retention is always enabled for inference requests, and with zero operator access, AWS operators can’t view your prompts and completions during inference.
In this post, we show you how to get started with Kimi K3.1 Pro Highspeed on Amazon Bedrock. We also cover how to lower costs with the Flex tier, explicit prompt caching for repeated context, and how to use the model as a coding assistant in OpenCode.
Get started with Kimi K3.1 Pro Highspeed on Amazon Bedrock
To try the model without writing code, open the Amazon Bedrock console, choose Test, then Playground, and select Kimi K3.1.
From code, Kimi K3.1 Pro Highspeed is available on the bedrock-runtime endpoint through the OpenAI-compatible Chat Completions and Responses APIs, and through the Amazon Bedrock Converse and Invoke APIs. We recommend the Chat Completions API. You reach the model through cross-Region inference profiles:
global.moonshotai.kimi-k3.1routes requests to any supported commercial AWS Region, and costs less per token than the geographic profiles. We recommend it for most workloads.us.moonshotai.kimi-k3.1keeps processing within US Regions, andin.moonshotai.kimi-k3.1keeps it within India Regions, for workloads with data residency requirements.
Prerequisites
To follow the examples, you need:
- An AWS account with access to Amazon Bedrock.
- Python 3.11 or later, with the OpenAI SDK, aws-bedrock-token-generator, and boto3 installed (
pip install -U openai aws-bedrock-token-generator boto3). - An AWS Identity and Access Management (IAM) identity allowed to call
bedrock:InvokeModelandbedrock:InvokeModelWithResponseStreamon the Kimi K3.1 Pro Highspeed inference profiles. Addbedrock:CallWithBearerTokenif you authenticate with a bearer token.
Call Kimi K3.1 Pro Highspeed with the Chat Completions API
If your application already uses the OpenAI SDK, point it at the Amazon Bedrock endpoint and change the model name. The following example creates a short-term bearer token from your AWS credentials and sends one request:
Kimi K3.1 Pro Highspeed always reasons before it answers. With reasoning_effort, you control how much: low, high, or max. If you don’t set it, the model uses max, so a lower value is the most direct way to reduce latency and output tokens on simpler tasks.
Call Kimi K3.1 Pro Highspeed with the Responses API
The same client works with the Responses API, which uses reasoning.effort for the same setting:
Call Kimi K3.1 Pro Highspeed with the Converse API
If you already use the Amazon Bedrock Converse API, the change is the model ID:
Lower costs with the Flex tier
The Flex tier serves Kimi K3.1 Pro Highspeed at half the Standard price, in exchange for potentially longer response times. It’s well suited to workloads where cost efficiency is a higher priority than response time, such as model evaluations, content summarization, and background tasks in agentic workflows. Because you choose the tier for each request, one application can mix tiers. For example, the same application could use Priority for latency-critical requests, Standard for everyday traffic, and Flex for cost-sensitive work. Your on-demand quota is shared across the Standard, Priority, and Flex tiers.
To use Flex, set service_tier to flex. The following example reuses the Chat Completions client from earlier:
On the Converse API, set serviceTier to {"type": "flex"} instead. To see how much of your traffic each tier served, use the ServiceTier and ResolvedServiceTier dimensions in Amazon CloudWatch. We recommend starting with a small share of your traffic on Flex and comparing latency and cost before you move more.
Optimize inference with explicit prompt caching
Agents and coding assistants resend the same large prefix on every turn: system instructions, tool definitions, repository conventions, and reference documents. Kimi K3.1 Pro Highspeed caches repeated prefixes automatically, and with explicit prompt caching, you can mark where the stable prefix ends to improve your cache hit rate. Later requests reuse that prefix instead of processing it again, which lowers both latency and input cost for long, repeated context.
A few rules apply:
- Explicit caching works on the Chat Completions, Responses, and Invoke APIs, but not on Converse.
- A
prompt_cache_breakpointmust follow at least 256 tokens of stable content. - Cached content is retained for at least 30 minutes.
- Cache writes are billed at a higher rate than standard input. Cache reads are billed at a discounted rate and don’t count toward your input tokens-per-minute quota.
The following example caches a long system prompt and adds a second breakpoint after the user content, so a follow-up question on the same document can reuse both layers:
For more information, refer to Prompt caching for faster model inference.
Kimi K3.1 Pro Highspeed in practice: Coding with OpenCode
OpenCode is an open source, model-agnostic coding agent that runs in your terminal. You can connect it to Kimi K3.1 Pro Highspeed through the Amazon Bedrock Chat Completions API, using OpenCode’s OpenAI-compatible provider and an Amazon Bedrock API key. To create a key, open the Amazon Bedrock console in the AWS Region that you set in baseURL, then choose API keys. Short-term keys last up to 12 hours, work only in the Region where you generate them, and are recommended for production use. Long-term keys are intended for exploration.
Add the following to ~/.config/opencode/opencode.json, replacing the Region in baseURL with your own:
Start OpenCode in your project directory, enter /connect, choose Amazon Bedrock (Chat Completions), and paste your API key as shown in Figure 1. OpenCode stores the key, so you connect once per key. To switch between Kimi K3.1 Pro Highspeed and other models during a session, enter /models.
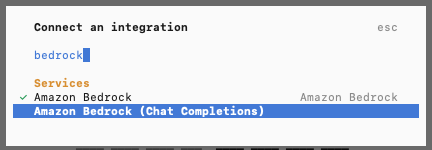
Figure 1: Connecting OpenCode to the Amazon Bedrock (Chat Completions) provider
The capabilities entry in the configuration lists the reasoning effort levels that the model supports, so OpenCode offers low, high, and max as variants of the model, as shown in Figure 2:
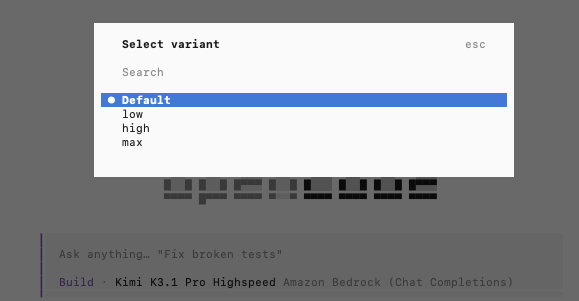
Figure 2: Reasoning effort variants for Kimi K3.1 Pro Highspeed in OpenCode
Output speed matters most in agentic coding. To complete a single task, a coding agent makes many model calls in a row. It reads files, plans a change, edits code, runs tests, and fixes what fails. Each call has to finish before the next one starts, and much of that time is spent generating reasoning and code. A higher output-token rate shortens every step, so the whole edit-test-fix loop finishes sooner and you wait less between iterations.
Availability
Kimi K3.1 Pro Highspeed is available on Amazon Bedrock through the global.moonshotai.kimi-k3.1, us.moonshotai.kimi-k3.1, and in.moonshotai.kimi-k3.1 cross-Region inference profiles. For supported Regions and model details, refer to the Kimi K3.1 Pro Highspeed model card and Regional availability. For pricing, refer to Amazon Bedrock pricing.
To get started, try Kimi K3.1 Pro Highspeed on the Amazon Bedrock console. To discuss your use case with the Amazon Bedrock team, connect with us.