Artificial Intelligence
Amazon Polly launches voice cloning: A unique voice for your brand
Voice cloning in Amazon Polly is now generally available as a gated release. Give Amazon Polly a few minutes of audio recordings from a speaker who has agreed to have their voice cloned, and Amazon Polly builds your own cloned voice in that speaker’s voice. The cloned voices run on the Amazon Polly generative engine, which delivers similar naturalness and accuracy as the rest of the generative voices. Amazon Polly voice cloning launches with seven languages: English, Spanish, German, French, Italian, Portuguese, and Hindi. Each cloned voice speaks the language it was recorded in. The cloned voices are automatically encrypted and access-controlled: only you can access your cloned voices.
Amazon Polly voice cloning is available in all the AWS Regions supported by the Amazon Polly generative engine, including the AWS GovCloud (US) Region. Access is already enabled for select Amazon Polly customers. Others can reach out to their AWS account team or apply for access to get access.
With this new feature addition, you can build the cloning lifecycle into AWS applications. Building a cloned voice is free for Amazon Polly customers, and Amazon Polly charges for cloned voice usage on a pay-as-you-go basis, see Amazon Polly Pricing page for details.
Hear it for yourself
Press play: the first few seconds are a real recording of the speaker, and then their cloned voice takes over with words they never recorded.
- From recordings to TTS voice. A few minutes of our science lead Trevor’s source audio, and the resulting generative voice.
- Recorded: “Hello, I’m Trevor, from Science.” Cloned voice: “That first sentence was my real voice. This is my cloned voice, created from a few minutes of my recordings. It can read any text you give it.”
- Supports seven languages. Hear Jonas, one of the authors, speaking German in his recording and then in his cloned voice:
- Recorded: “Hallo, ich bin Jonas. Das ist meine echte Stimme.” (Hi, I’m Jonas. This is my real voice.) Cloned voice: “Und das ist meine geklonte Stimme! Gleiche Stimme, neue Worte: Diesen Satz habe ich geschrieben, aber nie aufgenommen.” (And this is my cloned voice! Same voice, new words: I wrote this sentence, but never recorded it.)
- Use in a variety of applications. Here’s Trevor in a new job he hasn’t had: a non-player character in a game.
- “Who’s that crossing my bridge? Oh, it’s you again. Same deal as last time: answer my riddle, or hand over the sandwich.”
- Expand your voice library with voice cloning. Hear this audio sample from AWS Chief Evangelist Jeff Barr: a real recording, then his cloned voice.
- Recorded: “Hi, I’m Jeff, and this is how I really sound.” Cloned voice: “And this is how my cloned voice sounds, reading a sentence I never recorded.”
- Hannah: a real recording, then her cloned voice on a support line.
- Recorded: “Hello, I’m Hannah. This is my real voice.” Cloned voice: “Thanks for calling AnyCompany. Your order 4471 9902 ships today and should arrive on Thursday between 9 AM and 1 PM. Your confirmation code is K-7-Q-2-X-9.”
- Joely: a real recording, then her cloned voice narrating a lesson.
- Recorded: “Hi, I’m Joely, and this is how I really sound.” Cloned voice: “In this module, we’ll look at how a neural network learns. First, it makes a guess. Then it measures how far off that guess was, and adjusts, a little at a time.”
What you can build
A consistent brand voice across channels
Establish one recognizable voice and use it across your interactive voice response (IVR) system, cascaded voice agents, mobile app, in-store announcements, advertising, and connected devices. Rather than relying on a generic stock voice or re-booking a recording session each time a script changes, you can generate on-brand audio on demand, with a consistent sound in every channel.
Contact centers
Deliver a distinctive, on-brand voice across self-service flows, and update prompts as offers and policies change without a new studio session. You can create prompts from source text, test them before rollout, and use the same voice across greeting, routing, and notification experiences.
Media and content at scale
Creators, publishers, and studios can create audiobooks, courses, podcasts, game characters, and videos in multiple custom voices to enhance the listening experience, and produce subsequent chapters or updates quickly.
Localization with a consistent persona
Maintain a recognizable voice identity across a content library, so narration remains coherent across titles and updates. Each cloned voice speaks only the language it was recorded in. For multilingual experiences, create and review approved voices per supported language.
Accessibility and personalization
Offer a natural, human-sounding voice for reading experiences, assistive tools, and personalized interactions. You confirm the speaker’s consent each time you create a voice.
How voice cloning works
With voice cloning, you can build a custom Amazon Polly voice from recordings of a single speaker and then synthesize speech in that voice through the Amazon Polly generative engine. The voice moves through four steps, from recording the speaker to using the finished voice:
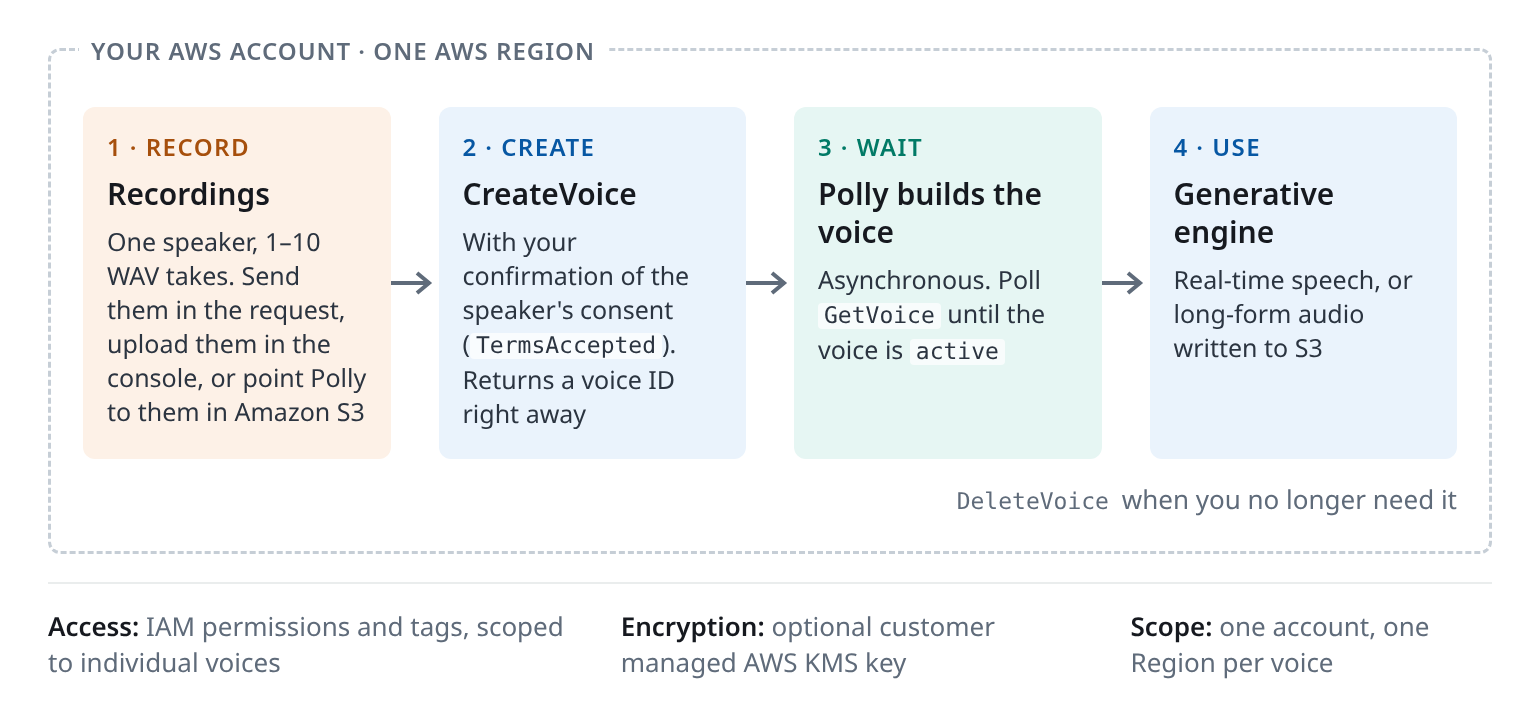
Figure 1: The voice cloning lifecycle, from recording a speaker to using the finished voice
A cloned voice goes through four steps:
- Record. You record one speaker (see the following recording tips). You can send the recordings directly in the
CreateVoicerequest or upload them on the console. You can also store them in an Amazon Simple Storage Service (Amazon S3) bucket in the AWS Region where you want the voice and point Amazon Polly to them. - Create. You call
CreateVoicewith 1-10 recordings, the language they are spoken in, andTermsAccepted=True, your confirmation that you have the speaker’s consent. Amazon Polly returns a voice ID (vc-…) right away and builds the voice in the background. - Wait. Creation is asynchronous and typically takes 5-10 minutes. During that time, Amazon Polly also checks the quality of your text-to-speech (TTS) voice for speaker similarity. You call
GetVoiceuntil the status changes frompendingtoactiveorfailed. - Use. You pass the voice ID to
SynthesizeSpeechfor real-time audio or toStartSpeechSynthesisTaskfor long-form audio written to S3, withEngine="generative", the same way you call the other generative voices in Amazon Polly. When you no longer need the voice, you callDeleteVoice.
Consent and control
A cloned voice is made from one person’s recordings. You confirm that you have the speaker’s consent for all recordings and that you control who can use the voice and when it’s deleted.
- You confirm consent for each voice you create. When you create a voice, on the console or with
TermsAccepted=Truein the API, you confirm that you have obtained all rights and consents necessary to create and use the cloned voice. Your use of voice cloning is subject to the AWS Service Terms, the Biometric Notice and Consent Terms, the AWS Responsible AI Policy, and the AWS Acceptable Use Policy. - Generated speech carries a watermark. Amazon Polly adds a watermark to text-to-speech audio generated with the cloned voice.
- Only your account can use it. A cloned voice is scoped to the AWS account that created it, and you control access with AWS Identity and Access Management (IAM). You can encrypt voices with your own AWS Key Management Service (AWS KMS) key and tag them.
- You decide when it goes away. Delete a voice with one
DeleteVoicecall or on the console, once it’s active or its creation has failed. - Amazon Polly does not retain a copy of your voice recordings once the voice is created and doesn’t use them to train Amazon Polly models. It keeps only the voice data it needs to synthesize speech, and stores it encrypted. You can use your own AWS KMS key for that encryption, and
DeleteVoiceremoves the data immediately.
We recommend that you:
- Keep a record of each speaker’s consent.
- Delete the voice if the speaker withdraws consent.
- Tell listeners when they’re hearing a synthetic voice where that’s appropriate.
- Grant voice permissions only to the people and systems that need them.
For details on intended uses and limitations, see the Amazon Polly AI Service Card and the AWS Responsible Use of AI guidance.
Best practices for recordings
Your cloned voice learns from the recording, including the parts you’d rather it didn’t: the laptop fan, the room echo, the meeting app’s noise filter.
- Record two to ten minutes of natural speech, split into takes of up to a minute. You can send up to 10 recordings per voice, and up to 15 minutes of audio in total. Quality matters more than length: more audio might not change how the voice sounds.
- One speaker, a quiet room, the same distance from the mic. Use a USB microphone, or a phone app that can record WAV. Record in mono WAV, 16-bit, at 24 kHz from the start, so there’s nothing to convert later. Amazon Polly accepts other audio formats, but we recommend WAV. See the Amazon Polly Developer Guide for supported formats and limits.
- Avoid using meeting apps and browser recorders. Their echo cancellation and noise suppression change the voice, and the clone learns those changes too.
- Record every take in the style you want the voice to have. The cloned voice takes its style from the recordings and can’t blend several, so upbeat, sad, and angry takes won’t give you a voice that can do all three.
- Record in the language the voice should speak. Voice cloning is tested with recordings in US English, German, US Spanish, French, Italian, Brazilian Portuguese, and Hindi. Recordings in other accents of these languages, such as British English or Canadian French, also work but are less tested, so check the voice with your own content.
Getting started
On the console: once voice cloning is enabled for your account (see Availability), expand the left panel and choose Voice cloning, upload up to 10 recordings or select them from Amazon S3, confirm the terms, and choose Create. Each upload can be up to 5 MB. When the voice is ready, try it out on its details page.
In code, you need:
- The latest version of boto3 (
pip install --upgrade boto3). - IAM permissions for
polly:CreateVoice,polly:GetVoice,polly:DescribeVoices,polly:SynthesizeSpeechandpolly:DeleteVoice. For long-form audio, alsopolly:StartSpeechSynthesisTask,polly:GetSpeechSynthesisTaskands3:PutObjecton the output bucket. - For the following Amazon S3 example: your recordings in a bucket in the Region where you create the voice, with
s3:GetObjectpermission for the IAM role or user that callsCreateVoice.
If Python reports that the Polly object has no attribute create_voice, upgrade boto3.
For long texts such as audiobook chapters or course modules, use an asynchronous synthesis task that writes the audio to S3:
For additional end-to-end Speech AI applications you can build with Amazon Polly, including the voice cloning feature, such as cascaded voice agents and live speech translators, go to the Amazon Polly GitHub repo.
Production considerations
Create voices ahead of time
Voice creation takes minutes, so treat it as a provisioning step, not part of a user request. A small workflow (for example, AWS Step Functions or a job queue) can call CreateVoice, check GetVoice every 30 seconds until the voice is active, and then store the voice ID in your configuration. CreateVoice and DeleteVoice share a limit of 1 request per second, so queue bulk creations and deletions.
Keep an inventory
DescribeVoices lists your cloned voices alongside the voices built into Amazon Polly. Cloned voices have Origin set to customer. Store the voice ID, Region, language, consent reference, and owner for each voice, and give each voice a unique Name. If a CreateVoice call times out or returns a server error, the voice might already exist, and the SDK’s automatic retries can create a second one. Check DescribeVoices for that name before you try again.
Plan for errors
CreateVoice returns ThrottlingException when you exceed the 1-request-per-second limit it shares with DeleteVoice, and ServiceQuotaExceededException when the account has reached its cloned-voice quota in that Region. Synthesizing with, or deleting, a voice that is still being created returns ConflictException. If a voice uses your own KMS key, callers without access to the key get an access-denied error. When creation fails, StatusReason gives only a general message, so check the recordings against the preceding recording best practices, then delete the failed voice and create a new one.
Scope permissions to voices
Cloned voices are IAM resources, so you can give the role that serves traffic permission to synthesize with one voice of choice. If the voice uses your own KMS key, that role also needs access to the key. Keep polly:CreateVoice and polly:DeleteVoice for a separate provisioning role. Here’s an example policy for the serving role:
With tags, you can write the same rule once for a whole group of voices using aws:ResourceTag conditions. Review your existing policies too: a statement that allows polly:SynthesizeSpeech on all resources ("Resource": "*") also covers every cloned voice in the account.
Plan for quotas and Regions
Each account has an initial quota of 10 cloned voices per Region. To request an increase, contact your account team or AWS Support. A voice exists only in the account and Region where you created it. To serve another Region or account, create the voice again in that Region from the same recordings, and make sure the speaker’s consent covers every copy.
Test with your real scripts
Before a voice goes live, listen to it reading your own content: product names, numbers, addresses, and the longest sentences you have. The same text can come out slightly differently from one request to the next. For fixed prompts such as phone-line greetings, generate the audio once, approve it with the speaker and your brand team, and serve the stored file. If a name or term comes out wrong, spell it differently in the text or use a Speech Synthesis Markup Language (SSML) <phoneme> tag. Phoneme tags work with cloned voices in English, French, Italian, German, and Spanish. See Supported SSML tags.
Things to know
| Availability | Access is enabled per AWS account. If you see Voice cloning in the Amazon Polly console (expand the left panel and see if Voice cloning is listed), it’s enabled for your account. If not, you can reach out to your AWS account team or apply for access to request access. Supported AWS Regions are the same as the generative engine: US East (N. Virginia), US West (Oregon), Europe (Frankfurt), Europe (Zurich), Europe (London), Asia Pacific (Sydney), Asia Pacific (Seoul), Asia Pacific (Singapore), Asia Pacific (Tokyo), Canada (Central), and AWS GovCloud (US-West). A cloned voice lives in the AWS Region where you created it. |
| Languages | English, German, Spanish, French, Italian, Portuguese, and Hindi. Tested recording locales: US English (en-US), German (de-DE), US Spanish (es-US), French (fr-FR), Italian (it-IT), Brazilian Portuguese (pt-BR), and Hindi (hi-IN). Other accents of these languages also work but are less tested. Each voice speaks the language it was recorded in. |
| Recordings | 1-10 recordings per voice, up to 15 minutes in total. WAV is recommended: mono, 16-bit, at 24 kHz or 44.1/48 kHz. Amazon Polly accepts other audio formats too. Console uploads are limited to 5 MB per file. For larger files, use Amazon S3. |
| Data handling | Amazon Polly deletes its copy of your recordings once the voice is created and doesn’t use them to train Amazon Polly models. It keeps only the voice data needed for synthesis, stored encrypted (you can use your own AWS KMS key), until you call DeleteVoice. |
| Creation time | Typically takes 5-10 minutes to build a TTS voice, asynchronous. |
| Synthesis latency | Same as Generative voices in Amazon Polly. |
| Quotas | 10 cloned voices per account per AWS Region initially. To request an increase, contact AWS Support. CreateVoice and DeleteVoice share a limit of 1 request per second. |
| Synthesis | Cloned voices follow the Amazon Polly quotas for generative voices, including the text limits per request and per synthesis task. See Amazon Polly quotas. |
| Pricing | Creating a cloned voice is free. Amazon Polly charges for cloned voice usage on a pay-as-you-go basis. See Amazon Polly pricing. |
| APIs | CreateVoice, GetVoice, DeleteVoice and DescribeVoices to manage voices. SynthesizeSpeech and StartSpeechSynthesisTask with Engine="generative" to use them. See the Amazon Polly API reference. |
Conclusion
Voice cloning in Amazon Polly gives your application a voice people recognize: recorded once, with the speaker’s consent, and ready to use through the Amazon Polly APIs. To get started on the console, make sure Voice cloning is enabled for your account, prepare a recording and the required consent, open the Amazon Polly console, and create your first cloned voice. If you are a new customer and would like to enable voice cloning, reach out to your AWS account team or apply for access to get access.
For the developer guide, refer to the Amazon Polly documentation. For pricing, see the Amazon Polly Pricing Page. For additional speech AI use cases you can build with Amazon Polly, including voice cloning, check out the GitHub repo.
We can’t wait to hear what you build.
Thanks to Trevor Wood, Jonas Rohnke, Suyin Wang, Hannah Barrett, Nikie Xiong, Jeff Barr, and Joely Huang for lending us their voices.