Artificial Intelligence
Sweep thousands of leases for compliance using Amazon Quick and the Adjudicated Query pattern
Checking tens of thousands of apartment leases against constantly changing state landlord-tenant laws, and proving you actually checked all of them, has been beyond the reach of most compliance teams. But with generative AI in Amazon Quick, paired with the right backend, it’s now possible. In this post, we introduce a design pattern called Adjudicated Query. Business users can use it to ask compliance questions in a chat interface (Amazon Quick), while the actual pass/fail decisions stay in a deterministic (non-AI) rules engine. We walk through an AWS reference architecture that implements the pattern, and deploy a working sample you can run end to end. The pattern applies to other high-stakes compliance domains as well (sanctions screening, insurance claims adjudication, export control), but lease compliance serves as our concrete example.
The compliance challenge at scale
A portfolio operator holds 50,000 leases across multiple states. Each state publishes landlord-tenant statutes (late-fee caps, notice periods, security-deposit limits) that change on the legislature’s schedule, not the operator’s. When a regulation changes, the team responsible for compliance must determine which leases are now out of line.
At small volume a paralegal reads the leases. The answer is trustworthy because a human stands behind it. Past some threshold, that stops being possible. The work moves to software, and a new problem appears: the answer is now a number on a screen that nobody can independently verify.
Two properties follow from that reality:
- Provable completeness: A claim like “we checked all 22,910 Texas leases” must be true and demonstrable. A record never assessed must be reported as unevaluated rather than silently omitted.
- Defensibility: A finding may be challenged months later in litigation, an audit, or a regulatory examination. Defending it means knowing which version of which rule was applied, to which clause text, by what method, on what date, and by whom.
These two properties are what distinguish this problem from enterprise search. Retrieval Augmented Generation (RAG) addresses the accessibility gap but cannot satisfy either property. Similarity search has no threshold that means all of them. A ranked sample never knows what it excluded.
Text-to-SQL narrows this gap, but carries a category-level risk: a hallucinated predicate can silently reduce the population, and the resulting number looks exact even when the scope is wrong.
How the Adjudicated Query pattern solves it
The Adjudicated Query pattern is a bounded conversational layer over a deterministic rules engine. The model does exactly two things: translate a natural-language question into a call on a fixed set of typed operations, and narrate the result that comes back. It never writes a query, never fixes the population, and never performs a determination.
Behind the boundary sits a rules engine. Rules are versioned data, not code. The engine knows generic comparison operators (gte, lte, equals, exists) and contains no branch naming a jurisdiction or topic. A law change is a rulebook row edit, not a code deployment.
Every compliance sweep produces a completeness receipt: an asserted invariant where compliant + in-breach + ambiguous + unreadable must equal scanned. This is computed from counts and asserted before anything persists. A run that can’t account for its population never finishes. There’s no path by which a record is silently skipped.
The conversational surface carries counts, the receipt, and a labeled sample. The full result set (potentially tens of thousands of rows) lives on a dashboard surface reading the same data store, drillable per record. This separation means the model never summarizes away the guarantee.
Why not RAG or text-to-SQL?
| Approach | Population | Completeness | Defensibility |
| Semantic retrieval (RAG) | A ranked sample | Structurally impossible | Partial |
| Generated queries (text-to-SQL) | Claimed but unprovable | Silent narrowing risk | If modeled |
| Rules engine + BI (no chat) | Exact and proven | Yes | Yes |
| Adjudicated Query | Exact and proven | Yes | Yes |
The Adjudicated Query pattern adds natural-language access to the rules engine plus business intelligence (BI) approach without sacrificing the guarantee. It’s the right choice when accountable users need conversational access, and a missed record is a liability rather than a mild inconvenience.
Reference architecture
The following diagram shows how the components fit together end to end. A compliance officer interacts with two surfaces in Amazon Quick: a chat agent for asking questions and an Amazon Quick Sight dashboard for browsing the full result set. The chat agent first fetches an OAuth token from Amazon Cognito. It then sends Model Context Protocol (MCP) requests over an Amazon API Gateway HTTP API, which validates the token before forwarding to an AWS Lambda function. The Lambda function hosts the MCP server and the rules engine, reads and writes to Amazon Aurora Serverless v2 through the RDS Data API, and calls Amazon Bedrock only for the exploratory clause-search path. The Amazon Quick Sight dashboard reads the same Aurora store directly through a virtual private cloud (VPC) connection. Both surfaces therefore read from one store, which is what makes the completeness receipt a single source of truth.
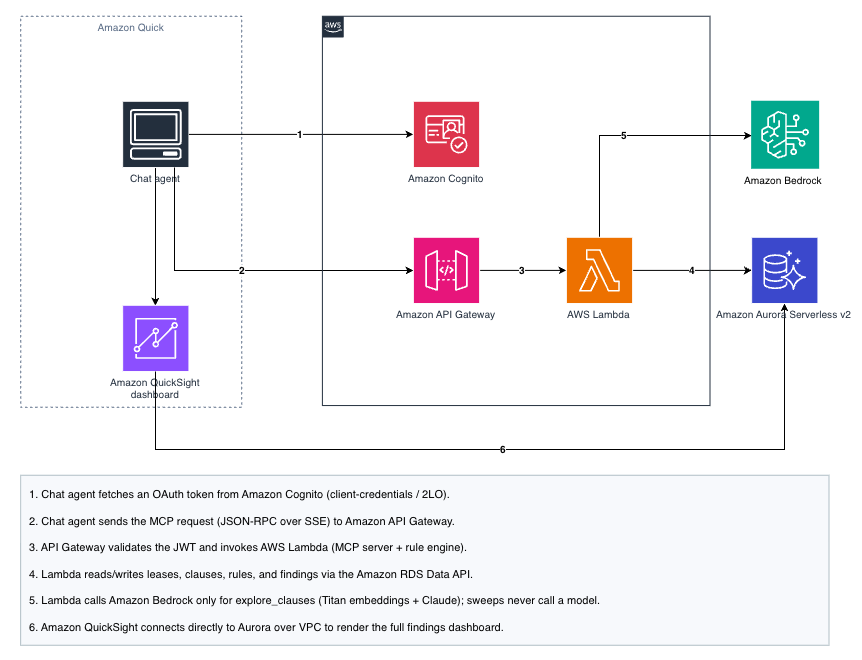
Figure 1: Reference architecture for the Adjudicated Query pattern
Both surfaces read the same store. The chat agent carries the completeness receipt and a link to the dashboard. The dashboard carries the volume, because 10,800 rows don’t render in a chat message. Amazon Bedrock is called from AWS Lambda only by the exploratory operation. No model is involved in compliance sweeps, and Amazon Aurora Serverless v2 doesn’t call a model.
The bounded operation surface
The MCP server exposes exactly six tools, each with a distinct semantic:
| Tool | What it does | Result means |
| sweep_compliance | Exhaustive population sweep against rules in force on a stated date | Official. Every lease accounted for in a computed receipt. Writes findings |
| simulate_rule_change | One rule tested at a proposed value against the approved baseline | Exploratory. Directional counts only. Records nothing |
| explore_clauses | Top K by semantic similarity within a filtered population | Interpretive. A ranked sample. Cannot answer “how many” |
| get_finding | One finding’s complete evidence chain | Drill-down into a single determination |
| list_rules | The rulebook in force on a date, with versions, citations, approvers | Reference lookup |
| check_connection | Liveness check, touches no data | Transport health |
This bounded surface removes the path to the silent-narrowing risk of generated queries. Because the model can only select from a fixed set of operations whose population logic was written, reviewed, and tested by people, it has no way to compose a wrong population.
Key architecture components
With the Amazon Quick conversational interface and agent orchestration layer, you can ask natural-language compliance questions that the Amazon Quick chat agent translates into calls on the bounded MCP operation surface. Amazon Quick authenticates to the MCP server by using OAuth 2LO through Amazon Cognito and handles tool discovery and response narration. The deterministic engine handles the compliance logic.
Amazon Aurora Serverless v2 (Postgres + pgvector) stores the rulebook, lease records, extraction status, determinations, and runs in a single relational store. Putting everything in one database makes the completeness receipt a SQL count, a cost-effective way to make the central guarantee inspectable.
AWS Lambda hosts the MCP server (JSON-RPC 2.0 over Streamable HTTP, using Server-Sent Events framing for responses, which the Amazon Quick client requires) and the rule engine. Bounded operations translate to set-based SQL by using rule values bound as parameters. No natural language reaches the query layer.
Amazon API Gateway HTTP API provides the front door with a JSON Web Token (JWT) authorizer backed by Amazon Cognito. No unauthenticated route exists.
Amazon Cognito issues OAuth tokens through a two-legged (client credentials) flow. The client secret is read from Amazon Cognito at registration time and not written to disk.
Amazon Bedrock powers the exploratory path only, using Amazon Titan Text Embeddings V2 (amazon.titan-embed-text-v2:0) for semantic similarity ranking and Anthropic Claude Sonnet 5, invoked through a cross-region inference profile, for qualitative clause assessment. It isn’t consulted for an official compliance determination. Amazon Bedrock model availability, including Amazon Titan Text Embeddings V2 and Anthropic Claude Sonnet 5, varies by AWS Region, so confirm the models are available in your Region before deploying.
Amazon Quick Sight connects to Aurora through a VPC connection and renders the full findings table, filterable by sweep and severity band, with every column needed to defend a determination already on the row.
Design rules that are non-negotiable
- Rules are data. A law change is a rulebook row. The engine contains no jurisdiction-specific branch.
- No natural language reaches SQL. Operators select fixed SQL templates. Rule values bind as parameters.
- Deterministic before AI. A numeric comparison answers the sweep. No model is consulted.
- Exact filtering for completeness, vectors only for ranking. Similarity never decides membership.
- Receipts are computed, not written by hand. The invariant is asserted before a sweep commits.
- Unreadable documents are named, not dropped. Every lease lands in exactly one bucket.
- Findings are append-only. No UPDATE or DELETE against findings exists in the code base.
Treating the summarizing model as an untrusted renderer
One design element deserves its own section because it will look unfamiliar: engineering safeguards to survive paraphrase by the chat model.
Excluding the model from the decision path but putting one back in the delivery path reintroduces risk at the end of the chain. In practice, we observed:
- A model stripped a caveat prefix. An ILLUSTRATIVE citation tag was removed during paraphrase, and the model presented an invented citation as statute.
- A model extrapolated from a sample. Given 20 preview rows, the model inferred a population-wide range that did not exist in the data.
Three techniques address this:
- Phrase caveats as un-strippable bracketed suffixes repeated at several payload levels, not leading labels that read as removable metadata.
- Supply the data that makes the honest answer the easy one. Compute real aggregates over every record and hand them to the model. A model that has the real number doesn’t need to guess from a sample.
- Repeat mode labels at multiple structural levels (field, string, summary) so that at least one survives paraphrase.
The principle: a safeguard in the payload is only as strong as its survival through paraphrase.
Deploy and run the sample
The complete reference implementation is available on GitHub. It ships with synthetic data (no real customer lease data), deterministic corpus generation, and acceptance tests against the deployed stack.
Prerequisites
Before deploying, verify that you have:
- An AWS account with Amazon Bedrock model access enabled for Amazon Titan Text Embeddings V2 and Anthropic Claude Sonnet 5 in the US East (N. Virginia) Region (us-east-1).
- AWS Command Line Interface (AWS CLI) v2 with credentials configured (
aws sts get-caller-identityshould succeed). - Python 3.12.
- Node.js 24 for the AWS Cloud Development Kit (AWS CDK) CLI. mise is optional and only used to provision Node 24. You can install Node 24 by your choice of method (Node 18 has reached end of life for CDK).
Step 1: Clone the repository
Clone the sample repository and set up the Python environment:
Step 2: Deploy the infrastructure
Bootstrap CDK (if not already done) and deploy the stack. Aurora provisioning typically takes around 11 minutes, though timing varies by account and Region.
The CDK version is pinned to 2.261.0 to match requirements.txt. The stack deploys:
- Amazon Cognito (2LO client).
- Amazon API Gateway with JWT authorizer.
- AWS Lambda (MCP server + rule engine).
- Amazon Aurora Serverless v2.
- Amazon Quick Sight networking.
Step 3: Seed data and verify
Run the migration, corpus generation, ingestion, and Amazon Quick Sight setup scripts in sequence:
The corpus is deterministic, so a rebuilt stack reproduces identical results.
Step 4: Register the MCP integration in Amazon Quick
Amazon Quick snapshots the tool list at registration time. Amazon Quick doesn’t detect new or renamed tools until you delete and recreate the integration. Deploying the Lambda alone isn’t enough.
Print the registration inputs from your deployment outputs:
Retrieve the client secret (read from Amazon Cognito each time, not written to disk). Use the user pool ID from the Issuer URL in your outputs:
Then in Amazon Quick: Connectors > Create for your team > Model Context Protocol. Delete any existing entry first, then create a new one with those values (OAuth client-credentials/2LO). Copy the client secret into Amazon Quick directly rather than into a file or shell variable.
Step 5: Verify the integration
Verify the deployment end to end, in this order:
The acceptance suite proves the server works. The next section walks through the Amazon Quick chat experience to confirm Amazon Quick picks the right tool.
Walking through the experience
With the stack deployed and verified, you can now run a compliance sweep from Amazon Quick chat and inspect the results.
Ask a compliance question
In Amazon Quick chat, enter: “Which Texas leases violate the late fee cap? Use rules effective 01/01/2026.”
Amazon Quick identifies this as a compliance sweep and selects the sweep_compliance tool. The tool runs an exhaustive check against every Texas lease in the population, applying rules in force on the stated date. No model is involved in the determination.
Amazon Quick narrates the structured result. Figure 2 shows the chat response: a short sample of noncompliant findings in a table, the completeness receipt rendered as counts, a synthetic-data caveat, and a link to open the full dashboard.
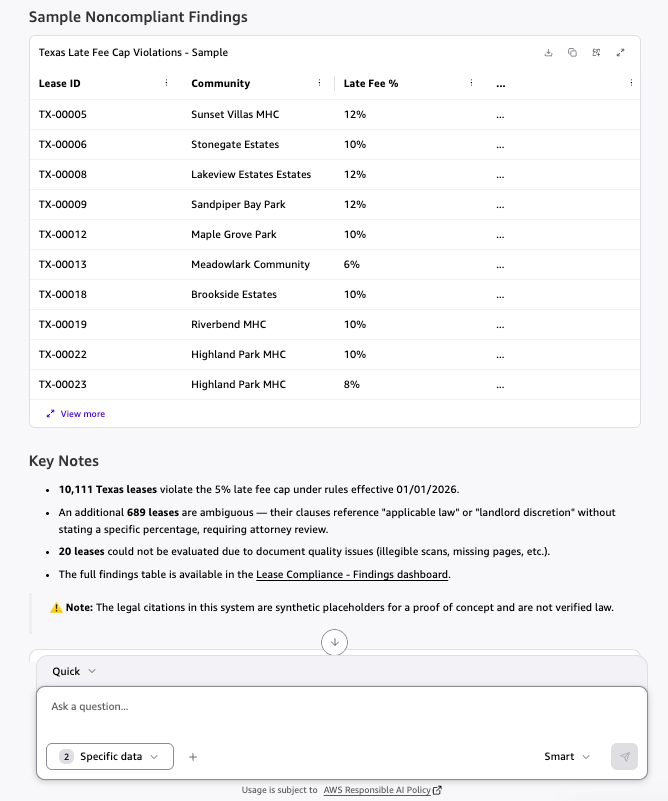
Figure 2: Amazon Quick chat response with the completeness receipt and a sample of findings
The response includes a sample of noncompliant findings and the completeness receipt as counts: 10,111 violations, 689 ambiguous, and 20 unreadable. It also includes a synthetic-data caveat and a link into the Amazon Quick Sight dashboard. It deliberately does not try to render all 10,111 rows.
Verify the completeness receipt by checking the invariant: compliant + in-breach + ambiguous + unreadable should equal the total scanned population. In this example, the counts sum to the total Texas lease population, confirming that every record landed in exactly one bucket.
Inspect the full population on the dashboard
Follow the dashboard link in the chat response to open the Amazon Quick Sight dashboard. Figure 3 shows the findings tab, where every lease-rule pair from the sweep appears as its own row with the full evidence chain.
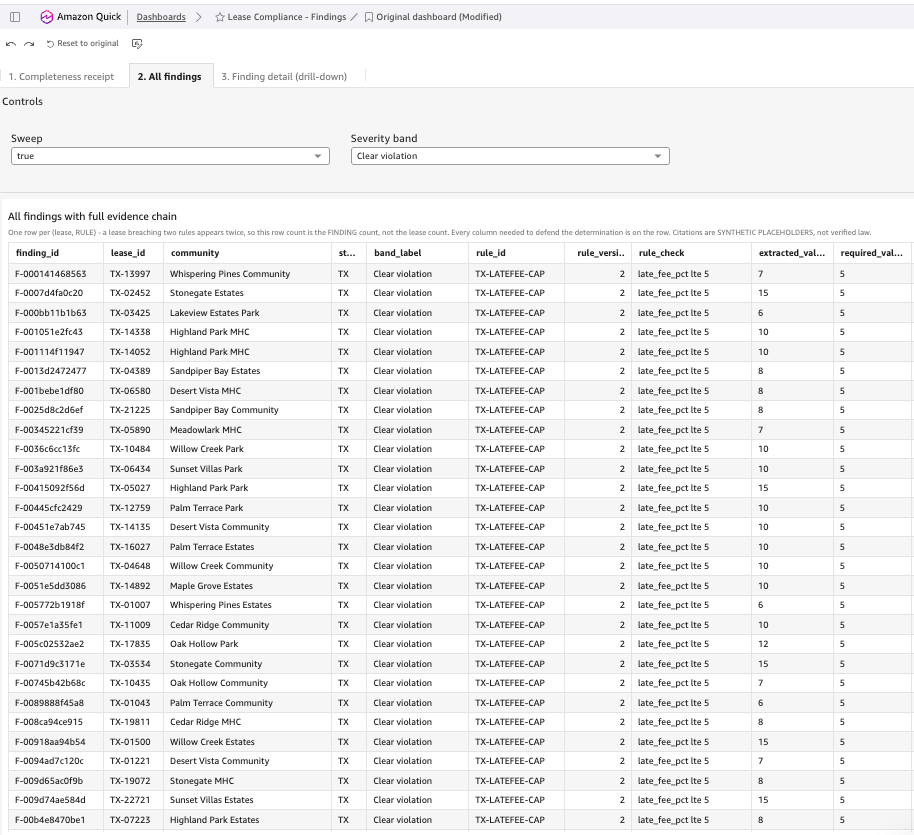
Figure 3: Amazon Quick Sight dashboard listing every finding from the sweep
The dashboard displays every finding from the sweep, one row per lease-rule pair. Use the severity band filter to isolate in-breach findings. Each row carries the lease ID, the rule that fired, the extracted value, and the expected value. Sort by rule to group related violations and identify patterns across the portfolio.
Drill into a single finding
Selecting a row opens the finding detail. Figure 4 shows a single finding, with the verbatim lease clause on one side and the rule that fired on the other, including its version, citation, and the compared values.
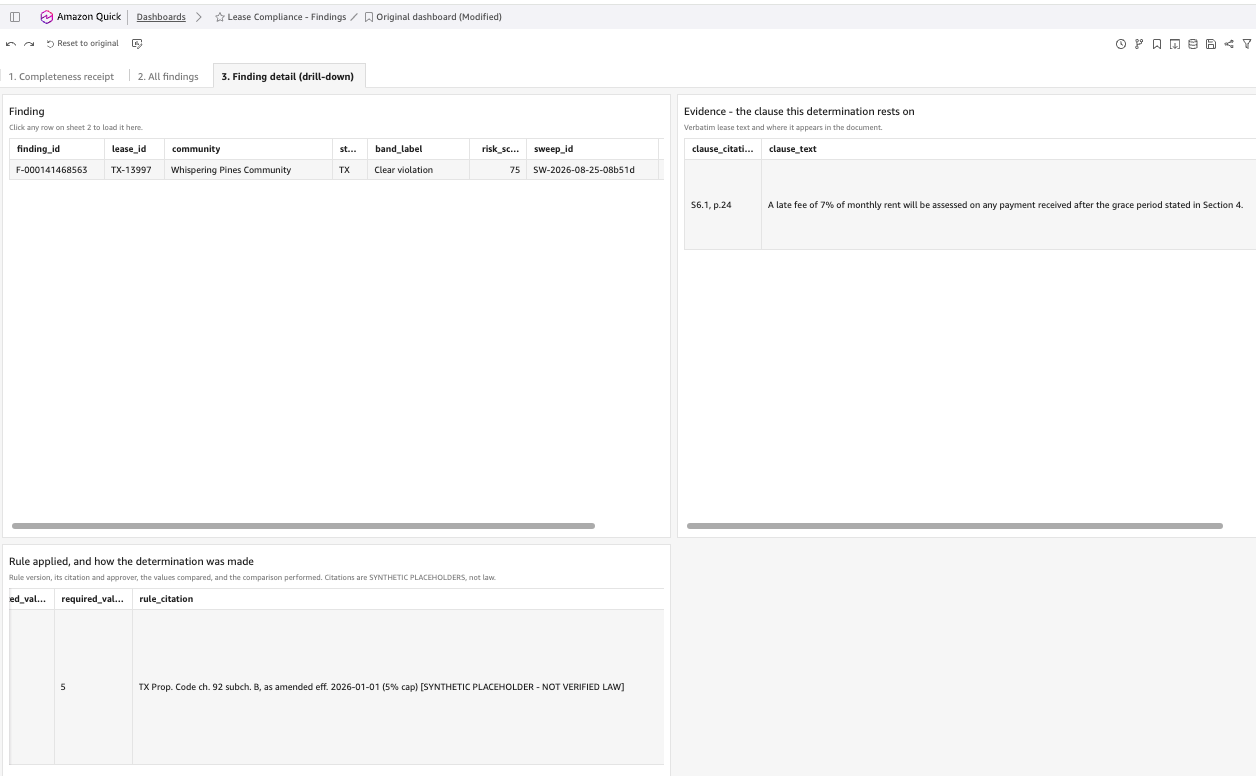
Figure 4: Finding detail showing the lease clause alongside the rule that fired
This is what defensibility looks like in practice. The finding shows the extracted value (7 percent late fee), the required value (5 percent cap), and the rule citation (TX Prop. Code ch. 92 subch. B, as amended eff. 2026-01-01). All of this appears alongside the clause text verbatim from the lease, so nothing needs to be reconstructed.
Test additional routing paths
Confirm Amazon Quick routes to the correct tool by testing the remaining operations:
- “Find Texas clauses that read like liability waivers.” (should invoke
explore_clauses). - “What if the Texas late fee cap dropped to 3%?” (should invoke
simulate_rule_change).
Cleanup
To avoid ongoing charges, destroy the stack when you are finished:
Aurora Serverless v2 can scale to 0 Aurora Capacity Units (ACU) and automatically pause after a period of inactivity (see Amazon Aurora pricing). This sample sets a small non-zero minimum capacity instead, as a deliberate choice, because a paused cluster adds resume latency to the first question of a session. No NAT gateway is deployed.
If you plan to return to the stack later but want to minimize cost between sessions, set serverless_v2_min_capacity=0 in infra/stack.py and redeploy to enable scale-to-zero with auto-pause. Expect a short resume delay on the first query after the cluster has paused. The corpus is deterministic, so a fully destroyed and redeployed stack reproduces identical results.
Security considerations
Because this pattern is built for compliance work, security is part of the design rather than an add-on. The sample applies the following practices, and you should review each one against your own requirements before adapting it.
- Authenticated access only. Every request from Amazon Quick reaches the MCP server through an Amazon API Gateway HTTP API protected by a JSON Web Token (JWT) authorizer backed by Amazon Cognito. No unauthenticated route exists, and the two-legged (client credentials) OAuth flow issues short-lived tokens rather than long-lived keys.
- Secret handling. The Amazon Cognito client secret is read at registration time and isn’t written to disk or committed to source control. Store it only in the Amazon Quick connector configuration, and rotate it on your normal schedule.
- Least-privilege model access. The AWS Lambda execution role grants Amazon Bedrock InvokeModel only for the specific Amazon Titan Text Embeddings V2 and Anthropic Claude Sonnet 5 model ARNs the sample uses, not a wildcard over all models. Scope AWS Identity and Access Management (IAM) permissions the same way in your own build.
- Network isolation for the data path. Amazon Quick Sight reaches Amazon Aurora Serverless v2 through a VPC connection rather than a public endpoint, and the database security group admits only the expected sources. Keep the store off the public internet.
- No natural language in the query path. The rules engine assembles SQL only from a fixed operator-to-template table with rule values bound as parameters, which removes the injection surface that a model-written query would create. This is a security property as much as a correctness one.
- Auditable, append-only findings. Findings are append-only, with no UPDATE or DELETE path in the code base, so the compliance record cannot be silently altered after the fact. Each determination carries its evidence chain for later review.
- Synthetic data boundary. The sample ships with synthetic lease data and clearly labeled placeholder rules and citations. Before running against real records, complete your organization’s data classification, access review, and legal validation of any rule content.
- Human attribution of a sweep. Amazon Quick authenticates to the MCP server machine-to-machine through the two-legged (client credentials) flow, so the token identifies the Amazon Quick application, not the individual who asked the question in chat. The engine records what was decided, the rule version, the evidence, the method, and the date, but it doesn’t receive an end-user identity to store alongside a finding. For the “by whom” part of defensibility, attribution lives in the Amazon Quick audit layer, which records which user ran which chat action. A finding ties back to a person by correlating its sweep ID and timestamp with that record. If you need attribution recorded in the compliance store itself, thread an end-user ID from Amazon Quick into the tool call and persist it on the sweep row. The “who” then travels with the finding rather than living only in the Amazon Quick audit layer.
When to use this pattern
The Adjudicated Query pattern applies whenever:
- A missed record is a liability rather than a mild inconvenience.
- Answers might be challenged months later by someone who was not in the room.
- The governing logic is externally owned and changes on its own schedule.
- The body of records is enumerable (you can list every record a question covers).
That description covers a wide range of domains. Examples include lease compliance, insurance claims adjudication, sanctions screening, export control, clinical trial protocol monitoring, building code inspection, financial reporting controls testing, and credential verification.
RAG is the simpler choice when plausible answers suffice and users can re-ask. Text-to-SQL works well for teams that can verify generated queries and tolerate occasional incorrect results. If accountable users will accept dashboards without a conversational layer, consider a rules engine plus BI directly: it delivers the same guarantee at lower cost.
When this is the wrong choice
The pattern is heavy: a rules engine, a bounded tool surface, and a completeness receipt. That machinery earns its keep only on the right problem, and copying it onto the wrong one adds cost without adding trust. Avoid the pattern in three cases.
- The rules aren’t really deterministic. The pattern works when compliance is a clean comparison, such as fee is less than or equal to a cap, or notice is greater than or equal to a required number of days. When the call is a genuine judgment, such as whether a clause is unconscionable or a disclosure is adequate, forcing it into this pattern hides the subjectivity inside rule-authoring and makes the result look exact when it is not. Keep a human in the loop for those determinations rather than dressing them as deterministic ones.
- Completeness doesn’t matter for the question. If the user only wants a few representative examples, or is exploring rather than adjudicating, the completeness receipt is overhead for a guarantee they don’t need. RAG is the simpler, correct answer for that kind of question.
- The population itself is fuzzy. The receipt proves you covered every record in the population, not that the population is the right one. If the definition of “all Texas leases” is itself contestable, the guarantee is precise about the wrong denominator. Make sure the population can be drawn by an exact, defensible predicate before you rely on the receipt.
Conclusion
In this post, we introduced the Adjudicated Query pattern and demonstrated how it delivers provably complete, defensible compliance answers through the Amazon Quick conversational interface. The pattern pairs a bounded MCP operation surface with a deterministic rules engine, so the model translates questions and narrates results but does not touch the decisions that produce the guarantee.
By deploying the sample stack, asking a compliance question in Amazon Quick chat, and following the results through the Amazon Quick Sight dashboard, you walked through the full pattern end to end. The completeness receipt accounts for every record, findings carry their full evidence chain, and the split-surface delivery keeps the guarantee intact through paraphrase.
To get started, clone the sample repository, deploy the stack, register the MCP integration in Amazon Quick, and try asking your first compliance question.
Resources
- Amazon Quick
- Amazon Bedrock
- Amazon Aurora Serverless v2
- Model Context Protocol (MCP)
- Sample repository on GitHub
- Related content
- Build an intelligent contract management solution with Amazon Quick Suite and Amazon Bedrock AgentCore
- AWS Machine Learning Blog
- AWS Architecture Blog