Sold by: Stratus10
Put AI to work on your data. Stratus10's forward-deployed engineers design and build Amazon Bedrock solutions that let employees and customers ask questions in plain English across documents, knowledge repositories, and analytics data. Every solution is delivered as IaC with least-privilege security. Eligible projects may qualify for AWS proof of concept funding.
Overview
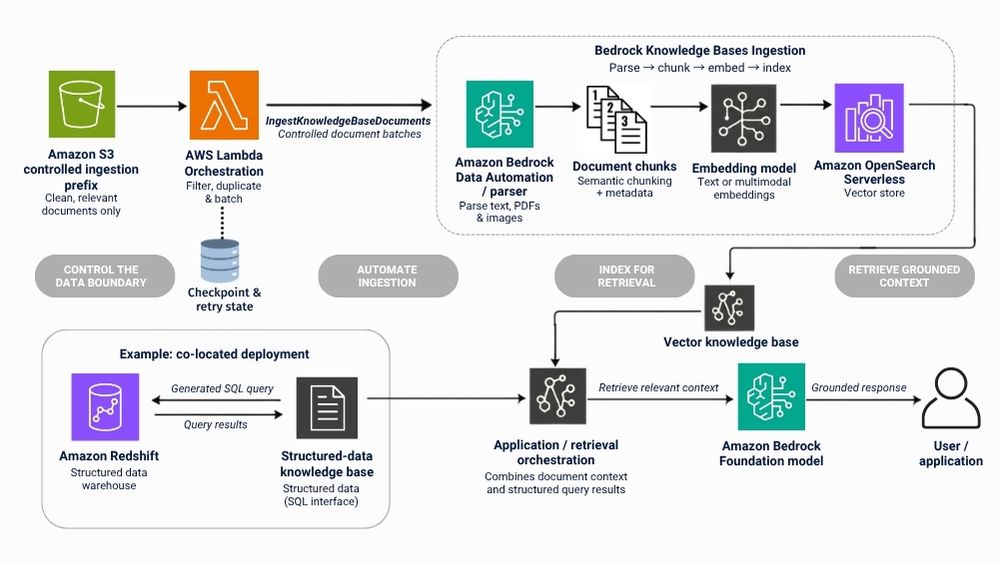
Stratus10 designs and builds Amazon Bedrock solutions that bridge structured and unstructured data, enabling employees and customers to ask questions in plain English across documents, knowledge repositories, and analytics data.
Retrieval-augmented generation (RAG) knowledge bases handle documents, PDFs, and images from sources such as Amazon S3, SharePoint, and Confluence. Structured knowledge bases use natural-language Text-to-SQL to query data warehouses such as Amazon Redshift. Automated ingestion pipelines keep knowledge bases up to date as new data arrives.
Common use cases include internal knowledge assistants, customer-facing search and support, and document-heavy business processes such as extraction, classification, summarization, and routing of incoming content.
Key Benefits:
- Fast path to production: Managed foundation models through Amazon Bedrock with no model hosting to run.
- One question, every data type: Query documents and analytics data together instead of in separate tools.
- Built for scale: Ingestion designed around Bedrock quotas and file limits, with automated pipelines for historical loads and new files.
- Cost control by design: Clean ingestion boundaries, deduplication, and tuned chunking keep embedding, parsing, and inference costs predictable.
- Secure and reproducible: Infrastructure as code (Terraform or CloudFormation) with least-privilege IAM roles, AWS Secrets Manager, and S3 bucket policies across every component.
- Funding support: Stratus10 helps eligible customers apply for AWS GenAI proof of concept funding.
Professional Services Process:
- Discover: Define the business problem, users, data sources, constraints, and success measures.
- Prioritize: Compare candidate use cases by value, feasibility, risk, cost, and time to production.
- Prototype: Validate the highest-value use case with a focused proof of concept, along with AWS funding where eligible.
- Build and Integrate: Data organization and ingestion pipelines, vector store (e.g., Amazon OpenSearch Serverless or Aurora PostgreSQL with pgvector), Text-to-SQL integration with your data warehouse, access controls, and deployment as infrastructure as code.
- Evaluate and Operate: Measure answer quality, monitor performance and cost, and refine retrieval.
Deliverables:
- Use-case assessment and prioritized roadmap
- Solution architecture diagram
- Amazon Bedrock Knowledge Base(s) for structured and/or unstructured data
- Automated ingestion pipeline (e.g., scheduled or event-driven AWS Lambda)
- Infrastructure as code for all components
- Security configuration: IAM roles and policies, Secrets Manager, S3 bucket policies
- Runbook, documentation, and team training
Stratus10 is an AWS Advanced Tier Services Partner. Our forward-deployed engineers work alongside your business and technical teams from strategy through operations, keeping technical decisions connected to business outcomes.
Funding amounts and approval depend on the project and current AWS program terms.
Highlights
- Query documents and your data warehouse together in plain English.
- Production-ready from day one with automated ingestion pipelines, least-privilege IAM security, and infrastructure as code.
- Stratus10 helps eligible GenAI proof of concepts secure AWS funding and delivers a prioritized use-case roadmap, solution architecture, and team training.
Details
New
Introducing multi-product solutions
You can now purchase comprehensive solutions tailored to use cases and industries.
Pricing
Custom pricing options
Pricing is based on your specific requirements and eligibility. To get a custom quote for your needs, request a private offer.
Legal
Content disclaimer
Vendors are responsible for their product descriptions and other product content. AWS does not warrant that vendors' product descriptions or other product content are accurate, complete, reliable, current, or error-free.
Support
Vendor support
For questions about this Amazon Bedrock implementation, contact Stratus10 at info@stratus10.com or call 619-780-6100. A Stratus10 AI specialist will respond within 24 hours.