Sold by: Scitix
ScitiX Model Inference provides serverless access to AI models through an OpenAI-compatible API. Build AI agents, chat assistants, retrieval-augmented generation (RAG), and voice applications with text generation, embeddings, speech recognition, and text-to-speech.
Overview
ScitiX Model Inference is a managed AI inference service for developers and enterprises building production applications. Access models from providers including DeepSeek, Qwen, Z.ai, Moonshot AI, and Boson AI through a unified platform, without provisioning or operating GPU infrastructure.
Use an OpenAI-compatible REST API and existing SDK workflows to integrate text generation and embeddings into AI agents, chat assistants, semantic search, and retrieval-augmented generation (RAG). Speech recognition and text-to-speech extend applications to voice workflows. Streaming responses, function calling, and JSON mode are available for supported models.
Evaluate models in the browser-based playground before integrating them into an application. ScitiX operates B200, H200, and H100 GPU infrastructure and provides inference scheduling and multi-tier failover. Prompt caching and asynchronous batch processing are available for eligible models and workloads.
Model availability and feature support vary by model. Current model catalog and product details: https://www.scitix.ai/inference
Highlights
- Integrate model inference through an OpenAI-compatible API, with streaming, function calling, and JSON mode for supported models.
- Power high-performance model inference with ScitiX-operated B200, H200, and H100 GPU infrastructure and optimized inference scheduling, designed for high throughput and low latency.
- Build generative AI applications with text generation, embeddings, speech recognition, and text-to-speech on one platform.
Details
New
Introducing multi-product solutions
You can now purchase comprehensive solutions tailored to use cases and industries.

Features and programs
Financing for AWS Marketplace purchases
AWS Marketplace now accepts line of credit payments through the PNC Vendor Finance program. This program is available to select AWS customers in the US, excluding NV, NC, ND, TN, & VT.

Pricing
Pricing is based on the duration and terms of your contract with the vendor. This entitles you to a specified quantity of use for the contract duration. If you choose not to renew or replace your contract before it ends, access to these entitlements will expire.
Additional AWS infrastructure costs may apply. Use the AWS Pricing Calculator to estimate your infrastructure costs.
Dimension | Description | Cost/12 months |
|---|---|---|
Input Tokens | Total number of input tokens processed by the AI model, including prompts, instructions, and context provided by the customer. Usage is measured per 1 million tokens. | $100.00 |
Dimensions summary
This listing uses one usage-based pricing dimension. You pay for input tokens processed by the AI model, measured per 1 million tokens. Input tokens include prompts, instructions, and context you provide. There are no seats or minimum commitments. Your cost scales directly with how many input tokens you send. The more you process, the more you pay, since billing ties to actual token volume. This per-token structure lets you start small and grow usage without upfront capacity reservations.
Top-of-mind questions for buyers
Input tokens are the units the AI model reads before responding. They include your prompts, instructions, and any context you supply. Billing counts these per 1 million tokens. Output tokens the model generates are measured separately and are not part of this input token dimension.
Yes. Cached input tokens are billed at a reduced rate through prompt caching. When a prompt or context repeats within a session, cache reads cost 10% of the normal input price. Session-aware routing raises cache hit rates, which lowers charges on repeated calls common in retrieval-heavy applications.
No. Billing ties to input tokens actually processed. There are no seats and no minimum commitments, so idle time accrues no charge. Data transfer in and out is also free. You pay only for the tokens the model processes.
www.scitix.ai
Helpful?
Vendor refund policy
Refund Policy - ScitiX AI
Customers may request refunds within 30 days of purchase. Refund requests are reviewed individually for service issues or billing errors. Approved refunds will be processed through AWS Marketplace. Usage charges are non-refundable except for verified metering errors or duplicate charges. To request a refund, contact hello@scitix.ai . All refunds are subject to applicable AWS Marketplace policies.

Legal
Vendor terms and conditions
Upon subscribing to this product, you must acknowledge and agree to the terms and conditions outlined in the vendor's End User License Agreement (EULA) .
Content disclaimer
Vendors are responsible for their product descriptions and other product content. AWS does not warrant that vendors' product descriptions or other product content are accurate, complete, reliable, current, or error-free.
Delivery details
Software as a Service (SaaS)
SaaS delivers cloud-based software applications directly to customers over the internet. You can access these applications through a subscription model. You will pay recurring monthly usage fees through your AWS bill, while AWS handles deployment and infrastructure management, ensuring scalability, reliability, and seamless integration with other AWS services.
Support
Vendor support
Support Contact
Support Email: hello@scitix.ai
For technical support, billing inquiries, account management, and general assistance related to ScitiX AI Inference Services, please contact our support team at hello@scitix.ai .
Our team will assist customers with service onboarding, API integration, model access, usage monitoring, and troubleshooting to ensure a smooth experience with ScitiX services.
AWS infrastructure support
AWS Support is a one-on-one, fast-response support channel that is staffed 24x7x365 with experienced and technical support engineers. The service helps customers of all sizes and technical abilities to successfully utilize the products and features provided by Amazon Web Services.
Similar products
Cohere provides a representative AI model: Embed that translates text into numerical vectors that models can understand.
Fast inference API for open-source models like Llama, Qwen, OpenAI GPT-OSS, and more, powered by the revolutionary Cerebras Wafer-Scale Engine.
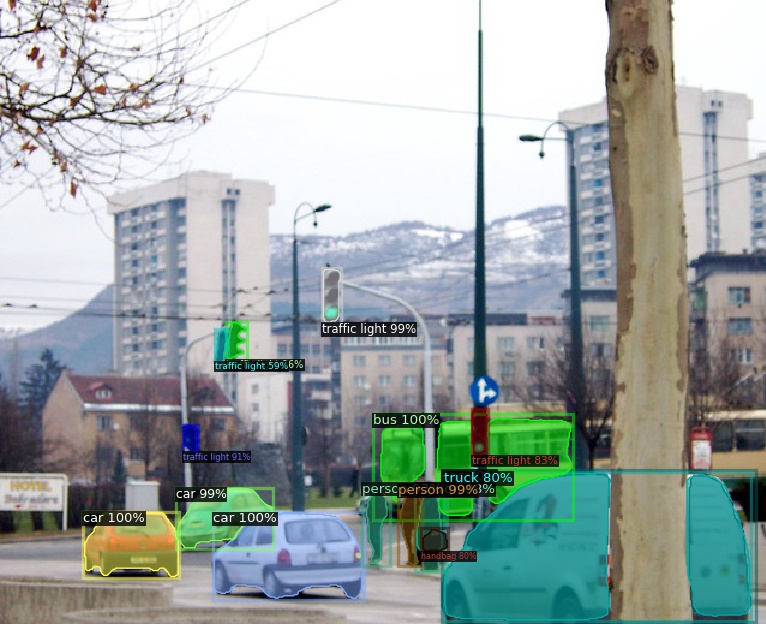
Detect and segment objects on images using the state of the art Mask R-CNN model

Want to learn more about how to build your Generative AI with best practices and scale its development on AWS? This is a free, 60-minute consultation with one of Mission Cloud's AI Specialists to discuss your ideas, concerns, and needs.
Customer reviews
No customer reviews yet
Be the first to review this product . We've partnered with PeerSpot to gather customer feedback. You can share your experience by writing or recording a review, or scheduling a call with a PeerSpot analyst.