Sold by: Sigmodata
Deployed on AWS
Free Trial
Score financial news, headlines and analyst commentary as positive, neutral or negative for research and risk teams. Runs inside your AWS account, so no text is sent to a third-party API. 85.1% accuracy on 3,397 held-out examples.
Overview
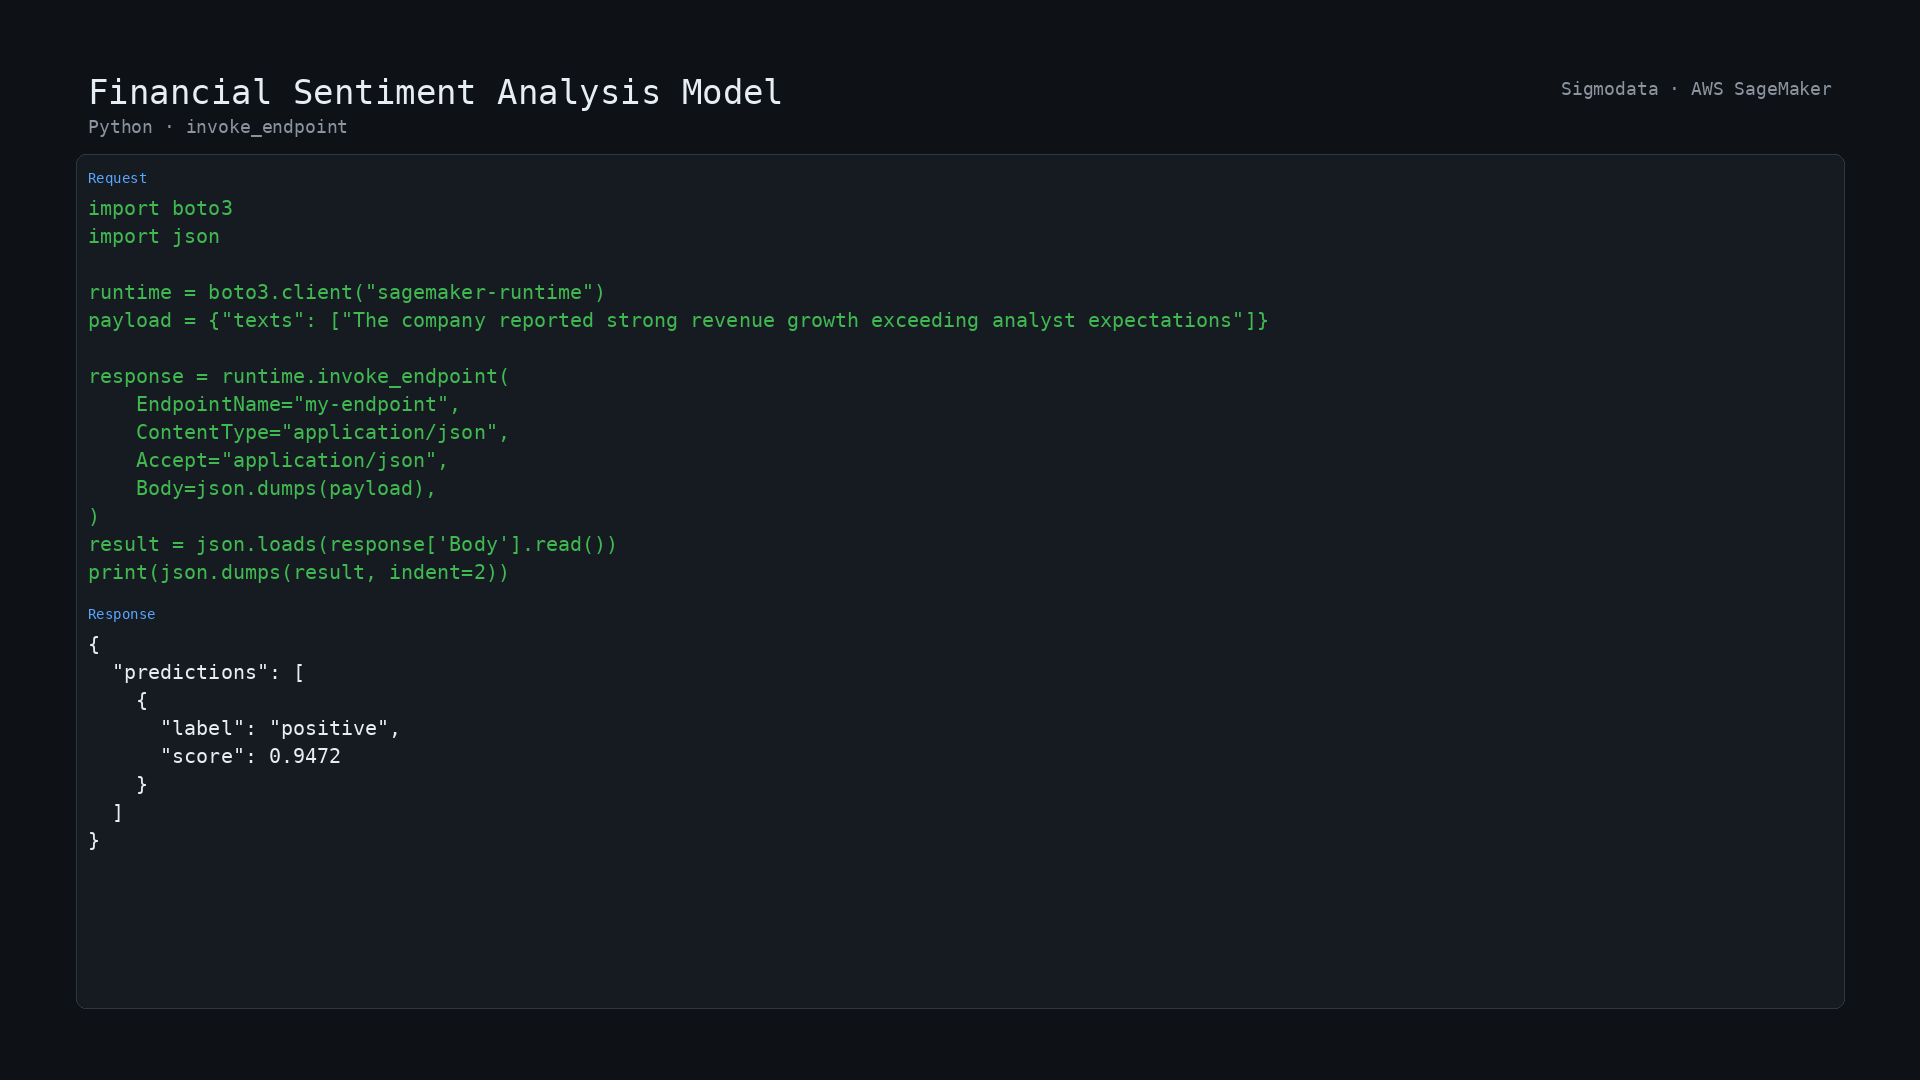
Image
Python predict
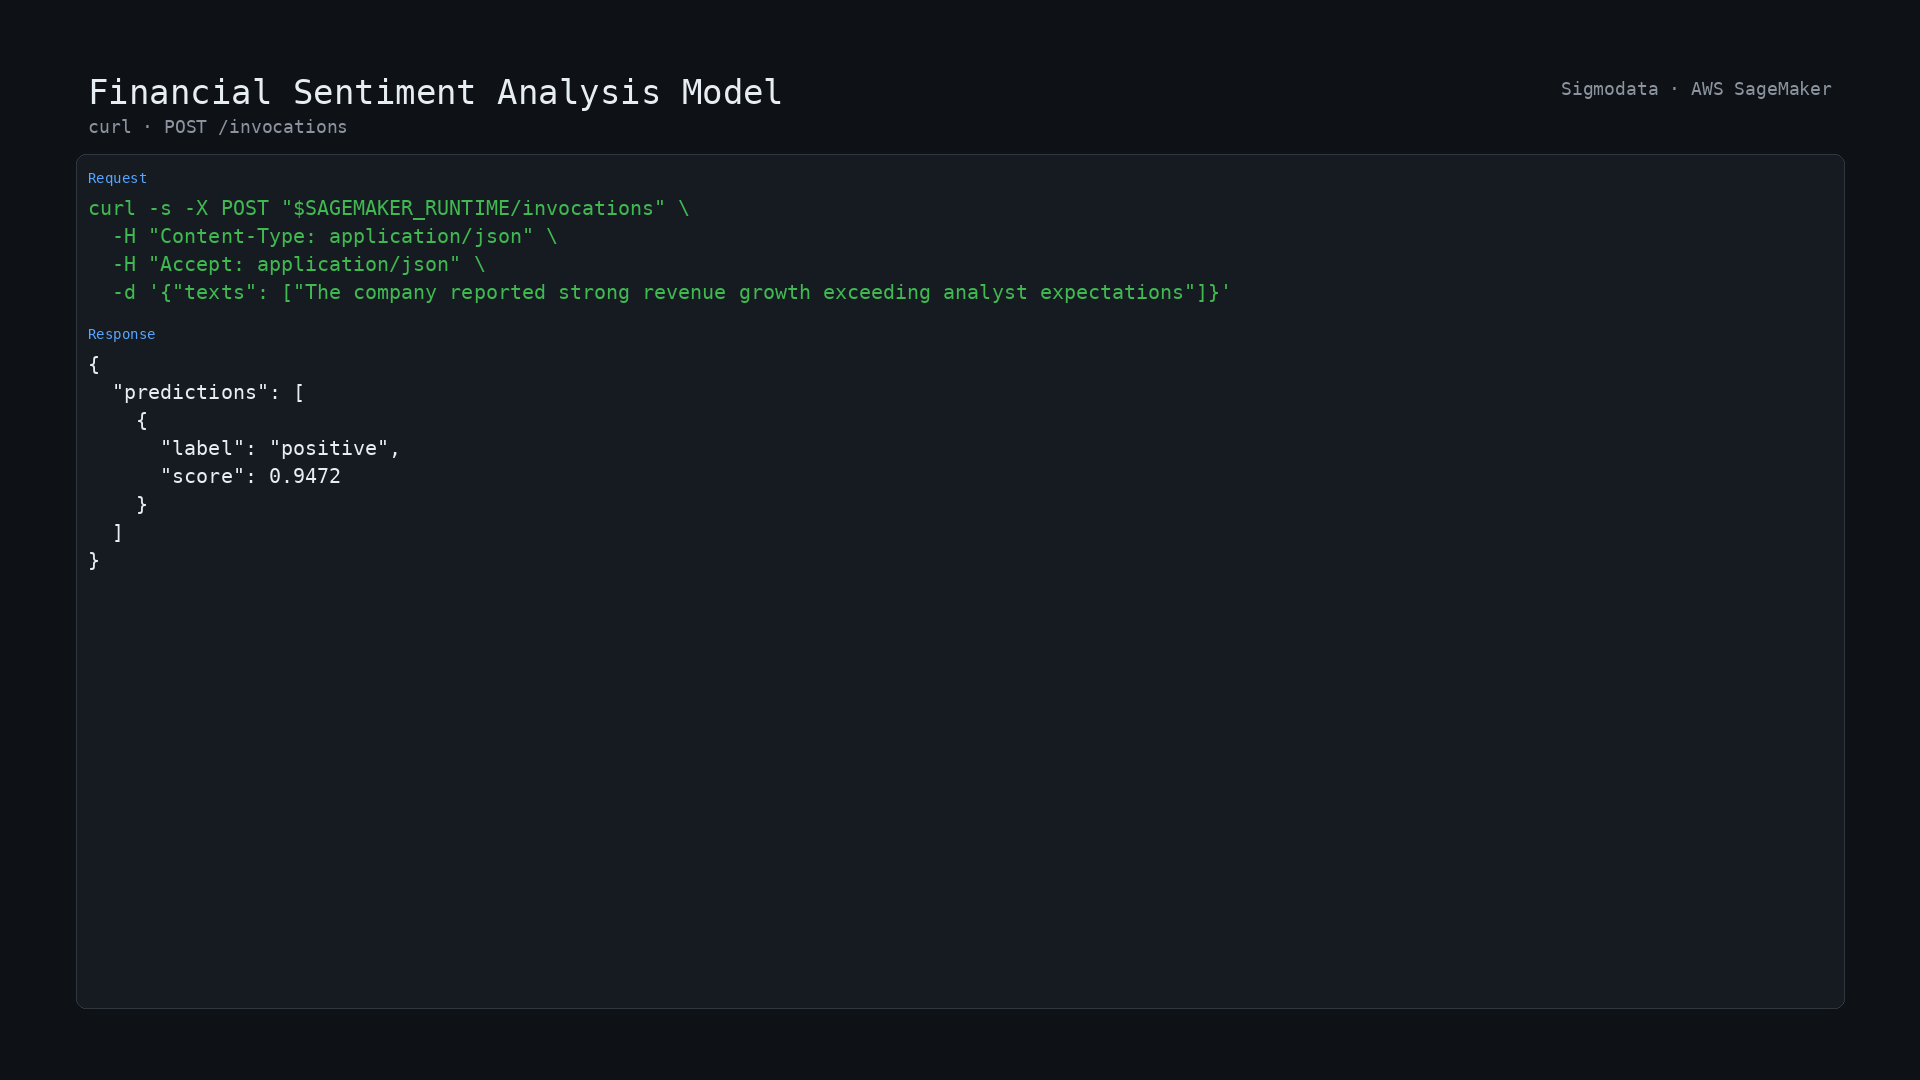
Image
POST /invocations
Runs inside your own AWS account: your text is processed on a SageMaker endpoint you control, inside your VPC, and is never sent to a third-party API.
This SageMaker model package provides a REST API to analyze the sentiment of financial text such as news headlines, analyst notes, and market commentary.
Each input text is classified as negative, neutral, or positive with a confidence score. The model is fine-tuned on financial news and financial phrase datasets, so it reads market language such as "beat estimates" or "missed guidance" in context rather than as generic positive or negative wording.
Use it to tag news and analyst commentary in a research pipeline, monitor tone around a ticker or sector, or enrich market data feeds before downstream analysis.
The API accepts input as JSON or CSV and supports real-time endpoints and batch transform.
We welcome your feedback at support@sigmodata.com
Model and training data The model is a ModernBERT-base (answerdotai/ModernBERT-base) text classifier fine-tuned with PyTorch and Hugging Face Transformers on the public nickmuchi/financial-classification and zeroshot/twitter-financial-news-sentiment datasets. Labels follow each dataset's own definition: negative (bearish), neutral, and positive (bullish). About 63 percent of the examples are neutral, 22 percent positive and 14 percent negative. It runs in network isolation on SageMaker, so no data leaves your account.
Known limitations
- English only. Other languages are not supported.
- The model was trained on short texts: the longest training example is about 110 tokens and 99 percent are under 64. Input up to 512 tokens is accepted, but accuracy is only characterized for short text; split long documents into sentences before sending.
- Precision on the minority classes is lower than on neutral: about 0.73 for negative and 0.75 for positive (recall 0.86 and 0.83), against 0.93 for neutral. Treat low-confidence negative and positive scores with care.
- Tuned for short financial text such as headlines and analyst notes. Long filings should be split into sentences first.
- Sentiment is about the language used, not a prediction of price movement. Do not use it as investment advice.
Measured performance
- Accuracy 85.1 percent, macro-F1 0.823, measured on 3,397 held-out examples from the financial news and phrase datasets. The split is seeded (70/20/10, seed 42) and was not used in training. F1 by class: negative 0.79, neutral 0.89, positive 0.79.
- On the same 3,397 examples the public ProsusAI/finbert model scores 77.0 percent accuracy (macro-F1 0.735). FinBERT is ahead on the Financial PhraseBank sentences alone (macro-F1 0.876 against 0.829); this model is ahead on short news and analyst-rating text (0.821 against 0.677), which is the larger part of the test set and of the training data.
- Real-time endpoint on ml.m5.large: 284 ms median per request (312 ms p95).
- Throughput on the same instance: about 23 texts per second at a batch size of 32.
Highlights
- Classify financial news and market commentary as negative, neutral or positive, with a confidence score
- Runs inside your own AWS account and VPC - text is never sent to a third-party API
- 85.1 percent accuracy (macro-F1 0.823) on 3,397 held-out examples; about 23 texts per second on ml.m5.large
Details
Sold by
Delivery method
Latest version
Deployed on AWS
New
Introducing multi-product solutions
You can now purchase comprehensive solutions tailored to use cases and industries.
Features and programs
Financing for AWS Marketplace purchases
AWS Marketplace now accepts line of credit payments through the PNC Vendor Finance program. This program is available to select AWS customers in the US, excluding NV, NC, ND, TN, & VT.

Pricing
Free trial
Try this product free for 5 days according to the free trial terms set by the vendor.
Pricing is based on actual usage, with charges varying according to how much you consume. Subscriptions have no end date and may be canceled any time.
Additional AWS infrastructure costs may apply. Use the AWS Pricing Calculator to estimate your infrastructure costs.
Dimension | Description | Cost/host/hour |
|---|---|---|
ml.m5.large Inference (Batch) Recommended | Model inference on the ml.m5.large instance type, batch mode | $0.10 |
ml.m5.large Inference (Real-Time) Recommended | Model inference on the ml.m5.large instance type, real-time mode | $0.10 |
ml.c5.2xlarge Inference (Batch) | Model inference on the ml.c5.2xlarge instance type, batch mode | $0.10 |
ml.c5.2xlarge Inference (Real-Time) | Model inference on the ml.c5.2xlarge instance type, real-time mode | $0.10 |
ml.c5.xlarge Inference (Batch) | Model inference on the ml.c5.xlarge instance type, batch mode | $0.10 |
ml.c5.xlarge Inference (Real-Time) | Model inference on the ml.c5.xlarge instance type, real-time mode | $0.10 |
ml.m5.2xlarge Inference (Batch) | Model inference on the ml.m5.2xlarge instance type, batch mode | $0.10 |
ml.m5.2xlarge Inference (Real-Time) | Model inference on the ml.m5.2xlarge instance type, real-time mode | $0.10 |
ml.m5.xlarge Inference (Batch) | Model inference on the ml.m5.xlarge instance type, batch mode | $0.10 |
ml.m5.xlarge Inference (Real-Time) | Model inference on the ml.m5.xlarge instance type, real-time mode | $0.10 |
Dimensions summary
You pay by the hour for model inference, billed per host-hour on the instance you run. Pricing splits along two lines. First, you pick an instance type: ml.m5.large, ml.m5.xlarge, ml.m5.2xlarge, ml.c5.xlarge, or ml.c5.2xlarge. These differ in compute and memory size. Second, you pick a mode: real-time for live endpoints or batch for bulk jobs. Each instance-and-mode pairing is a separate rate. Your cost scales with how long each endpoint or batch job runs, plus standard AWS infrastructure charges. There is no upfront commitment.
Top-of-mind questions for buyers
Real-time mode runs a live endpoint that stays up to answer requests, billing per host-hour while the endpoint is active. Batch mode runs a job over bulk data, billing per host-hour while the job runs, then stops. Real-time suits continuous request flows; batch suits large one-off processing.
One host-hour is one hour that your chosen instance runs the model, whether serving requests or waiting. A real-time endpoint accrues charges the whole time it stays up, even with no traffic. To stop software charges, delete the endpoint. Batch jobs meter only while running.
Both combine: your per-host-hour rate depends on the instance type and mode you pick, then multiplies by hours run. Larger instances carry a higher hourly rate. Runtime hours usually drive total cost for steady real-time endpoints. AWS infrastructure charges apply on top of the software rate.
www.sigmodata.com
Helpful?
Vendor refund policy
No refunds offered but you may cancel at any time
Legal
Vendor terms and conditions
Upon subscribing to this product, you must acknowledge and agree to the terms and conditions outlined in the vendor's End User License Agreement (EULA) .
Content disclaimer
Vendors are responsible for their product descriptions and other product content. AWS does not warrant that vendors' product descriptions or other product content are accurate, complete, reliable, current, or error-free.
Delivery details
Amazon SageMaker model
An Amazon SageMaker model package is a pre-trained machine learning model ready to use without additional training. Use the model package to create a model on Amazon SageMaker for real-time inference or batch processing. Amazon SageMaker is a fully managed platform for building, training, and deploying machine learning models at scale.
Deploy the model on Amazon SageMaker AI using the following options:
Version release notes
Retrained after correcting a label error in the training data.
- Positive and neutral labels were swapped for the Twitter-sourced portion of the previous training data (about 71 percent of it). This version is trained on the corrected labels.
- Measured on 3,397 held-out examples: accuracy 85.1 percent, macro-F1 0.823 (F1 by class: negative 0.79, neutral 0.89, positive 0.79).
- Request and response formats are unchanged: JSON or CSV in, label plus confidence out. Real-time latency on ml.m5.large is about 284 ms median.
Additional details
Inputs
- Summary
A JSON object with a "texts" array of strings to classify (or a CSV file, one text per line, for batch transform).
- Input MIME type
- application/json, text/csv
{"texts": ["The company reported strong revenue growth exceeding analyst expectations"]}
The company reported strong revenue growth exceeding analyst expectations
Input data descriptions
The following table describes supported input data fields for real-time inference and batch transform.
Field name | Description | Constraints | Required |
|---|---|---|---|
texts | List of text strings to classify | - | Yes |
Resources
Vendor resources
Support
Vendor support
Support contact: Email: support@sigmodata.com Support URL: https://www.sigmodata.com/contact
Support description: Email support@sigmodata.com or https://www.sigmodata.com/contact . We reply within one business day, Monday through Friday, US Pacific time.
AWS infrastructure support
AWS Support is a one-on-one, fast-response support channel that is staffed 24x7x365 with experienced and technical support engineers. The service helps customers of all sizes and technical abilities to successfully utilize the products and features provided by Amazon Web Services.
Similar products
Deep Learning based solution which predicts positive, negative and neutral sentiments from text.
This solution identifies financial statements in an annual report and classifies them into Profit and Loss, Balance Sheet, and Cash Flow.
Machine Learning based solution which classifies tweets about airlines into positive, neutral and negative sentiment categories.
This solution assesses a corpus of text to predict the following emotion classes: Anger, Fear, Joy, and Sadness.
Customer reviews
No customer reviews yet
Be the first to review this product . We've partnered with PeerSpot to gather customer feedback. You can share your experience by writing or recording a review, or scheduling a call with a PeerSpot analyst.