Sold by: Sigmodata
Deployed on AWS
Free Trial
Send a ticket, log line, document or JSON object plus typed questions and get back a choice, a yes/no probability or a score level, never generated text. Runs inside your AWS account on a SageMaker endpoint, so no text is sent to a third-party API.
Overview
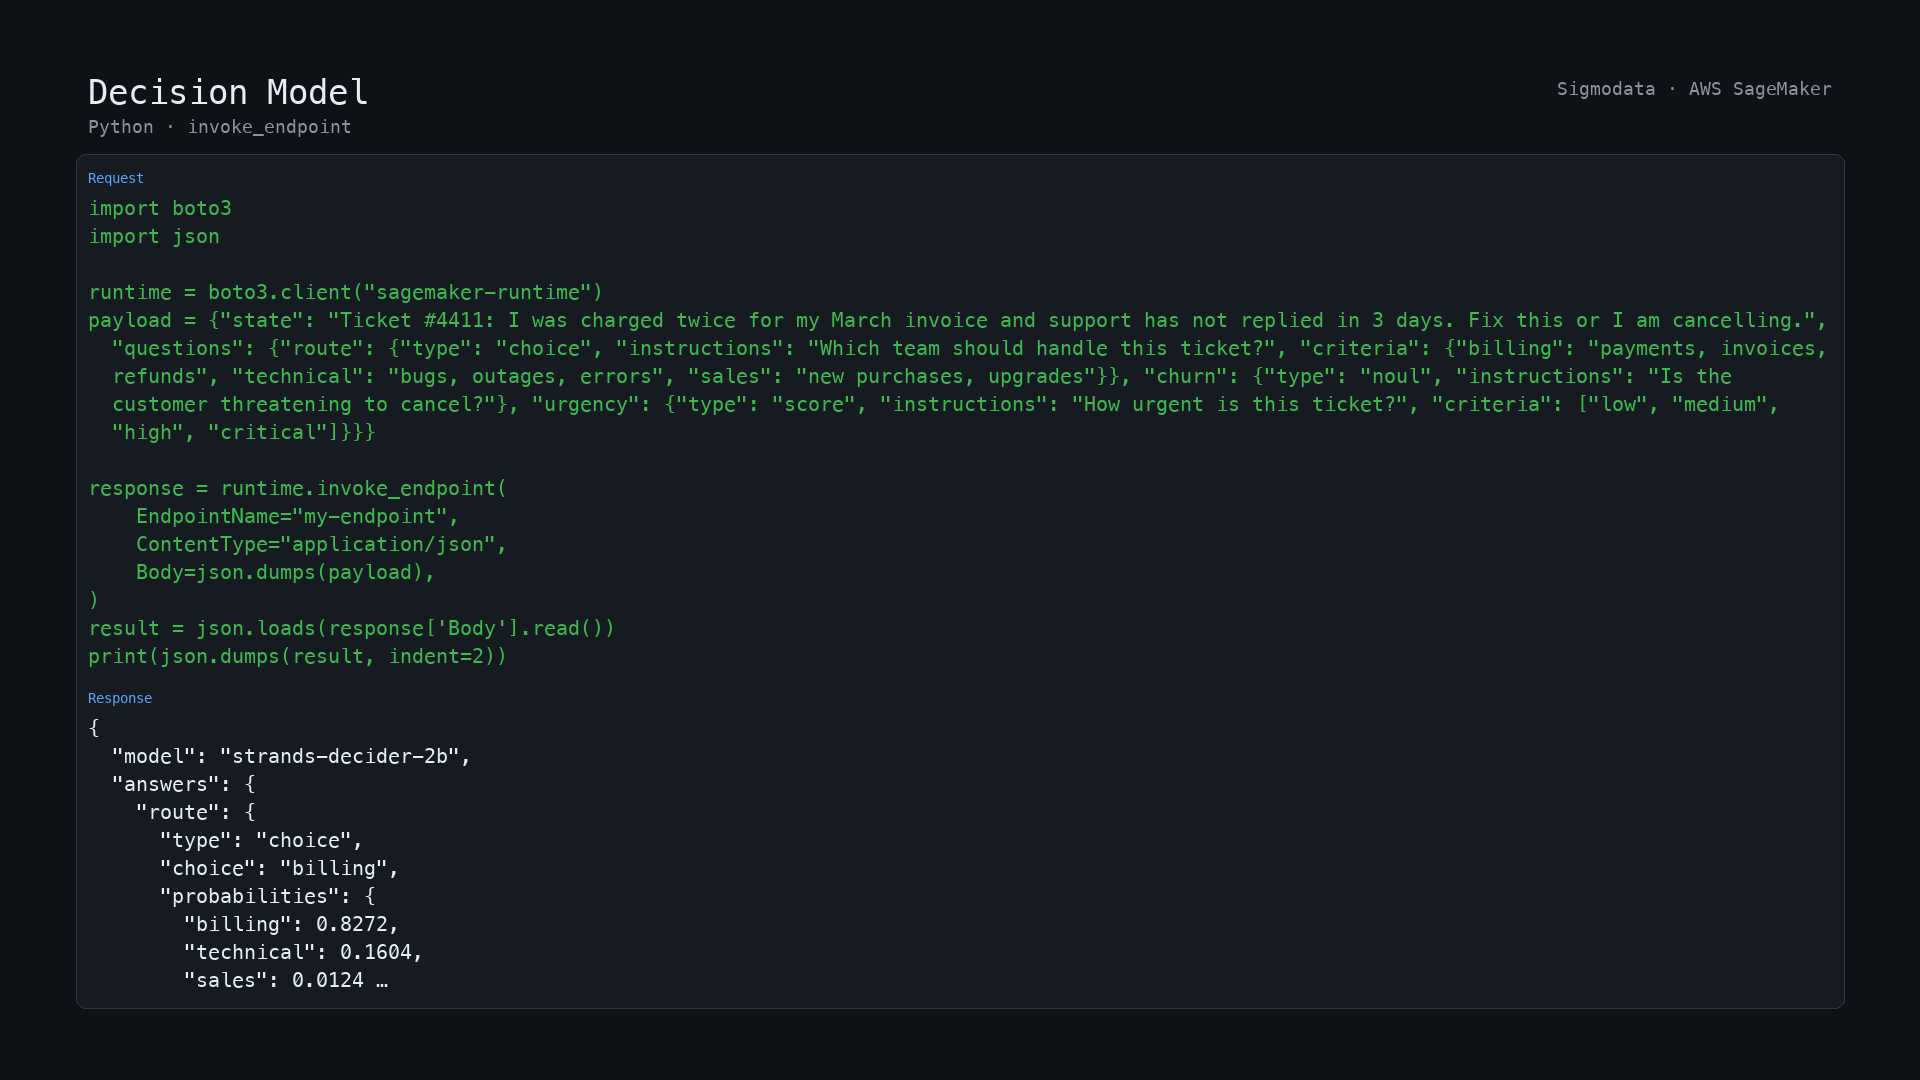
Image
Python predict
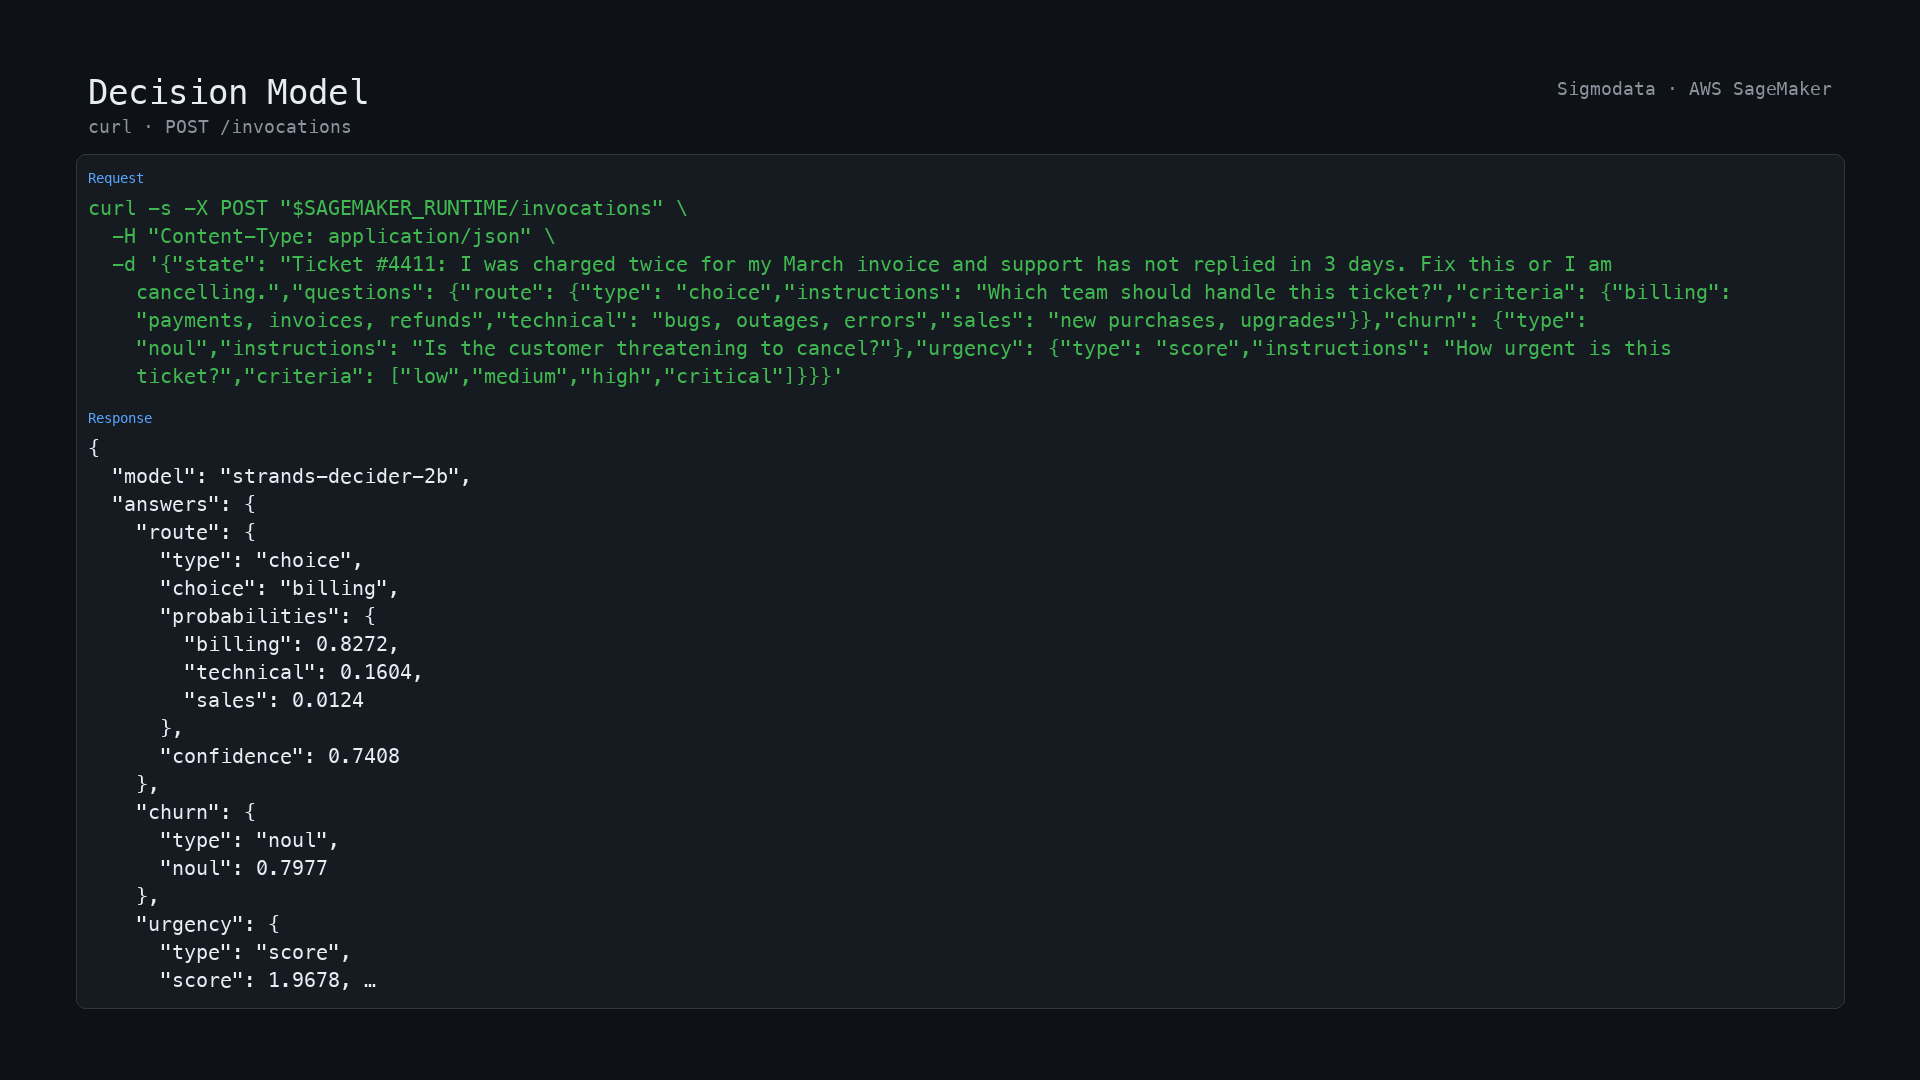
Image
POST /invocations
Runs inside your own AWS account: your data is processed on a SageMaker endpoint you control, inside your VPC, and is never sent to a third-party API.
Ask typed questions about unstructured input and get answers your code can act on, instead of free text to parse. Send one "state" (text, or any JSON object or array) and up to 64 questions. Every answer is one of the options you supplied:
- choice: one of your named options, with a probability for each
- noul: the probability that a yes/no question is true
- score: a level on a rubric you define, with the most likely level and the expected level
Typical uses are routing support tickets, flagging churn, fraud or abuse signals, classifying log lines by severity, and scoring reviews. Every answer carries a confidence, so you can act automatically on confident answers and send the rest to a person. Questions about one state are evaluated together, so adding a question is cheap.
The request and response shapes follow the public Jev System One API, so existing Jev clients work unchanged. Real-time endpoints and SageMaker batch transform (JSON Lines, one request per line) are supported. Use a GPU instance (ml.g4dn.xlarge or ml.g5.xlarge) for production speed; CPU instances (ml.m5.xlarge) suit low volume. Batch transform is validated on ml.m5.xlarge and ml.g4dn.xlarge.
We welcome your feedback at support@sigmodata.com .
Known limitations
- English-centric. Other languages are not evaluated.
- The context window is 4096 tokens. Your questions and options are kept intact first, and a long state is truncated from the end.
- One evaluation runs at a time per instance. Add instances for more throughput.
- Score questions are the least accurate type. Act on "level" and check "confidence".
Model and training data
Strands Decider 2B from AWS (Apache-2.0), a LoRA fine-tune of Qwen3.5-2B, served as published. The authors' training data is described in the model card: https://huggingface.co/StrandsAgents/strands-decider-2B-hobson-v19 . The container runs in network isolation, so no data leaves your account.
Measured performance
- Accuracy of 94 percent on our validation set, the same on GPU and CPU.
- One question, median and 95th percentile: ml.g4dn.xlarge 451 ms and 959 ms; ml.g5.xlarge 389 ms and 994 ms; ml.m5.xlarge 2.2 seconds.
- Twelve questions in one request: ml.g5.xlarge 0.6 seconds (about 18 questions per second); ml.g4dn.xlarge 1.6 seconds (about 7 per second); ml.m5.xlarge 14.1 seconds.
Highlights
- Typed answers, not generated text: pick one of your options, a yes/no probability or a rubric level, each with calibrated confidence
- Runs inside your own AWS account and VPC - your text is never sent to a third-party API
- 94 percent accuracy on our validation set; about 0.4 s per question on a GPU instance
Details
Sold by
Categories
Delivery method
Latest version
Deployed on AWS
Features and programs
Financing for AWS Marketplace purchases
AWS Marketplace now accepts line of credit payments through the PNC Vendor Finance program. This program is available to select AWS customers in the US, excluding NV, NC, ND, TN, & VT.

Pricing
Free trial
Try this product free for 5 days according to the free trial terms set by the vendor.
Pricing is based on actual usage, with charges varying according to how much you consume. Subscriptions have no end date and may be canceled any time.
Additional AWS infrastructure costs may apply. Use the AWS Pricing Calculator to estimate your infrastructure costs.
Dimension | Description | Cost/host/hour |
|---|---|---|
ml.g4dn.xlarge Inference (Real-Time) Recommended | Model inference on the ml.g4dn.xlarge instance type, real-time mode | $0.10 |
ml.m5.xlarge Inference (Batch) Recommended | Model inference on the ml.m5.xlarge instance type, batch mode | $0.10 |
ml.g4dn.2xlarge Inference (Real-Time) | Model inference on the ml.g4dn.2xlarge instance type, real-time mode | $0.10 |
ml.g4dn.xlarge Inference (Batch) | Model inference on the ml.g4dn.xlarge instance type, batch mode | $0.10 |
ml.g5.2xlarge Inference (Real-Time) | Model inference on the ml.g5.2xlarge instance type, real-time mode | $0.10 |
ml.g5.xlarge Inference (Batch) | Model inference on the ml.g5.xlarge instance type, batch mode | $0.10 |
ml.g5.xlarge Inference (Real-Time) | Model inference on the ml.g5.xlarge instance type, real-time mode | $0.10 |
ml.m5.2xlarge Inference (Batch) | Model inference on the ml.m5.2xlarge instance type, batch mode | $0.10 |
ml.m5.2xlarge Inference (Real-Time) | Model inference on the ml.m5.2xlarge instance type, real-time mode | $0.10 |
ml.m5.xlarge Inference (Real-Time) | Model inference on the ml.m5.xlarge instance type, real-time mode | $0.10 |
Dimensions summary
You pay by the hour for each inference instance you run, billed per host hour. The ten dimensions split across three instance families: GPU types (ml.g4dn and ml.g5) for production speed, and CPU types (ml.m5) for low-volume use. Each family offers xlarge and 2xlarge sizes. You also pick an inference mode: real-time for live requests, or batch for processing sets of inputs at once. GPU instances cover both modes; CPU instances cover both modes too. Cost scales with the instance size you choose and the hours you keep it running.
Top-of-mind questions for buyers
A host hour is one hour that a single inference instance stays running. Each instance you launch bills separately. One evaluation runs at a time per instance, so you add more instances to raise throughput. Charges accrue for every hour an endpoint stays active, whether real-time or batch.
Real-time mode runs a live endpoint that responds to single requests as they arrive. Batch mode processes sets of inputs at once using SageMaker batch transform. Both bill per host hour. Real-time suits continuous live traffic; batch suits processing large input sets in scheduled runs.
You pay per host hour for whichever instance you pick. GPU instances (ml.g4dn and ml.g5) process questions faster, suiting production volume. CPU instances (ml.m5) run the same model but slower, suiting low volume. Accuracy stays the same across both. Your cost tracks instance size and running hours, not throughput.
www.sigmodata.com
Helpful?
Vendor refund policy
No refunds offered but you may cancel at any time

Legal
Vendor terms and conditions
Upon subscribing to this product, you must acknowledge and agree to the terms and conditions outlined in the vendor's End User License Agreement (EULA) .
Content disclaimer
Vendors are responsible for their product descriptions and other product content. AWS does not warrant that vendors' product descriptions or other product content are accurate, complete, reliable, current, or error-free.
Delivery details
Amazon SageMaker model
An Amazon SageMaker model package is a pre-trained machine learning model ready to use without additional training. Use the model package to create a model on Amazon SageMaker for real-time inference or batch processing. Amazon SageMaker is a fully managed platform for building, training, and deploying machine learning models at scale.
Deploy the model on Amazon SageMaker AI using the following options:
Version release notes
Initial release.
- Strands Decider 2B typed decisions: choice, noul and score
- JSON requests with up to 64 questions per state
- Real-time endpoints and SageMaker batch transform (JSON Lines)
- GPU recommended (ml.g4dn.xlarge, ml.g5.xlarge); runs on GPU with default settings
Additional details
Inputs
- Summary
A JSON object with "state" (text, or any JSON object or array) and "questions" (a map of question name to a typed question). For batch transform, one such object per line (JSON Lines).
- Input MIME type
- application/json, application/jsonlines
{"state": "Ticket #4411: I was charged twice for my March invoice and support has not replied in 3 days. Fix this or I am cancelling.", "questions": {"route": {"type": "choice", "instructions": "Which team should handle this ticket?", "criteria": {"billing": "payments, invoices, refunds", "technical": "bugs, outages, errors", "sales": "new purchases, upgrades"}}, "churn": {"type": "noul", "instructions": "Is the customer threatening to cancel?"}, "urgency": {"type": "score", "instructions": "How urgent is this ticket?", "criteria": ["low", "medium", "high", "critical"]}}}
{"state": "Ticket #4411: I was charged twice for my March invoice and support has not replied in 3 days. Fix this or I am cancelling.", "questions": {"route": {"type": "choice", "instructions": "Which team should handle this ticket?", "criteria": {"billing": "payments, invoices, refunds", "technical": "bugs, outages, errors", "sales": "new purchases, upgrades"}}, "churn": {"type": "noul", "instructions": "Is the customer threatening to cancel?"}, "urgency": {"type": "score", "instructions": "How urgent is this ticket?", "criteria": ["low", "medium", "high", "critical"]}}}
Input data descriptions
The following table describes supported input data fields for real-time inference and batch transform.
Field name | Description | Constraints | Required |
|---|---|---|---|
state | The input to decide about, as text or any JSON object or array | - | Yes |
questions | Map of question name to a typed question (choice, noul or score), up to 64 per request | - | Yes |
Resources
Vendor resources
Support
Vendor support
Support contact: Email: support@sigmodata.com Support URL: https://www.sigmodata.com/contact
Support description: Email support@sigmodata.com or https://www.sigmodata.com/contact . We reply within one business day, Monday through Friday, US Pacific time.
AWS infrastructure support
AWS Support is a one-on-one, fast-response support channel that is staffed 24x7x365 with experienced and technical support engineers. The service helps customers of all sizes and technical abilities to successfully utilize the products and features provided by Amazon Web Services.
Similar products

FICO® Decision Modeler enables business users to author, test, and optimize decision logic that delivers their organizations higher profitability, lower development costs, and the flexibility to rapidly iterate and adapt to current and future business climates. (Private Offer Only)
Make smarter 1:1 decisions so you can achieve your most important goals, at scale.
FICO® Platform brings data, analytics, and decisioning together into a single decision intelligence platform, connecting previously siloed experiences into an operating framework that drives value creation across the customer lifecycle.

Infor Augmented Intelligence (AI) accelerates the power of AI/ML with our turn-key Decision Science as a Service offering. Focus on your business outcomes while we take care of augmented decision making using our expertise in enabling and managing personalized ML solutions for your business on AWS.
Customer reviews
No customer reviews yet
Be the first to review this product . We've partnered with PeerSpot to gather customer feedback. You can share your experience by writing or recording a review, or scheduling a call with a PeerSpot analyst.