AWS Storage Blog
Category: Analytics
How Proscia built unlimited observability with Amazon S3 and the Altinity Kubernetes Operator
Observability can claim a growing share of IT budgets. Learn how Proscia, a pathology AI company, built a self-hosted observability platform on Amazon S3, Amazon EKS, and ClickHouse managed by the Altinity Kubernetes Operator, achieving unlimited telemetry retention at object-storage cost under HIPAA, GDPR, and data-residency requirements.

How Comcast scaled analytics 80x while cutting costs 38% with GraphQL and Amazon S3 Tables
Customer Story | Amazon S3 Tables – Learn how Comcast redesigned their analytics layer with GraphQL and Amazon S3 Tables, scaling to 80x higher concurrent request volumes while cutting costs by 38% and reducing query latency by 28%. Comcast is building America’s largest and most intelligent broadband network with a simple purpose: connect everyone, everywhere […]
How Precisely transforms user experience with AI agents using Amazon S3 Vectors
At Precisely, the team is reimagining the user experience for its Data Integrity Suite by adding a conversational interface powered by AI agents to the traditional UI. With this enhancement, users can interact with the platform more naturally and intuitively (asking questions, making requests, and exploring data assets through dialogue) while still benefiting from the […]

Run Spark 31% faster and optimize compute costs with Amazon S3 Express One Zone on Amazon EMR
As your Spark datasets grow, storage latency often becomes the constraint, impeding application performance. Query runtimes stretch, and the bottleneck shifts from compute to how fast each node can read from Amazon Simple Storage Service (Amazon S3). We benchmarked this directly on Amazon EMR with TPC-DS at 3 TB scale. On an 8-node Graviton4 cluster […]
Optimize your self-managed PostgreSQL data warehouse with Amazon FSx for OpenZFS
A data warehouse is the analytical backbone of a modern enterprise, consolidating data from disparate sources into a single, authoritative view that enables complex queries, trend analysis, and confident decision-making. In financial services, this means sharper regulatory reporting, faster fraud detection, and deeper customer understanding. The operational reality is demanding. Enterprises juggle multiple source databases […]
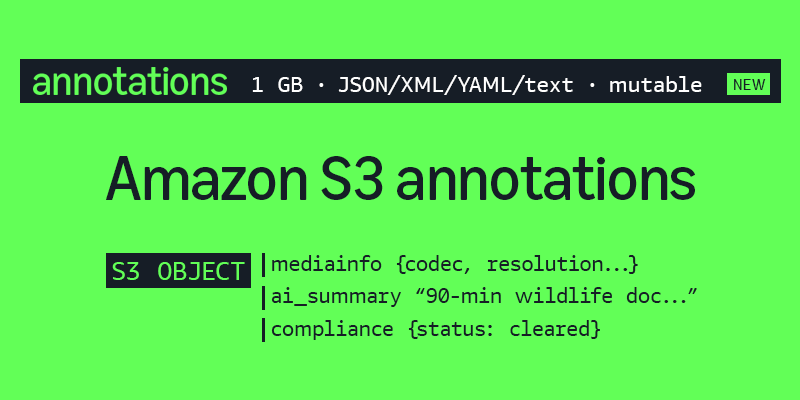
Track healthcare data lineage in real time with Amazon S3 annotations
Organizations that store sensitive data need to answer a simple question: where did this data come from, and what happened to it? In healthcare, this isn’t optional. Regulations like HIPAA, GDPR, and SOX require organizations to produce this information on demand. When an auditor asks, for example, “Show me every transformation that touched patient record […]
Analyze Amazon S3 annotations at scale with materialized views
Customers managing large volumes of objects in Amazon Simple Storage Service (Amazon S3) often need to attach rich business context like compliance classifications, processing lineage, AI-generated labels, and more. Until now, this context lived in external databases or sidecar files that were stored as separate objects, which created complexity to manage and keep it up […]

Accelerate Amazon S3 Replication with automated S3 Batch Operations parallelization
As data volumes grow, organizations must move large datasets between storage locations to meet compliance requirements, optimize performance, and help meet data sovereignty requirements. However, migrating petabytes of data presents significant challenges: lengthy transfer times, complex coordination of parallel operations, data integrity verification, and substantial engineering overhead. Automation reduces resource consumption and operational complexity during […]

How Vanderbilt University scales digital archive discovery with Amazon S3 Metadata
Managing massive digital collections is hard. When you’re preserving decades of historical content and adding new materials daily, making that content discoverable matters more than the storage itself. Vanderbilt University Library discovered this firsthand while managing their extensive digital archives, including the renowned Vanderbilt Television News Archive (VTNA). Amazon S3 Metadata accelerates data discovery by […]
Query Amazon S3 access logs instantly with CloudWatch and S3 Tables
Knowing who accessed your data, when, and how is the foundation for security investigations, compliance audits, cost attribution, and performance troubleshooting. Detailed access logs capture every request: who made it, which resource was accessed, and what response was returned. In practice, though, they arrive as semi-structured records spread across different locations. Turning them into actionable […]